- What CPU offloading actually means
- Why a model can run without fitting entirely in VRAM
- GPU layers: the most useful mental model
- CPU offloading does not eliminate the memory problem
- Do not calculate RAM from the GGUF file size alone
- Context length still consumes memory
- Quantization and CPU offloading solve different problems
- Why partial offloading can be much slower than full GPU inference
- How to find a practical offload configuration
- 1. Choose the model and quantization first
- 2. Set a realistic context length
- 3. Leave memory headroom
- 4. Offload as much as is useful
- 5. Test the actual workload
- When CPU offloading makes sense
- When CPU offloading is the wrong solution
- Common mistakes
- Assuming model file size equals required VRAM
- Using the maximum advertised context window
- Filling VRAM to the last megabyte
- Expecting CPU offloading to perform like extra VRAM
- Choosing a much larger model simply because it loads
- CPU offloading versus buying more VRAM
- The practical rule
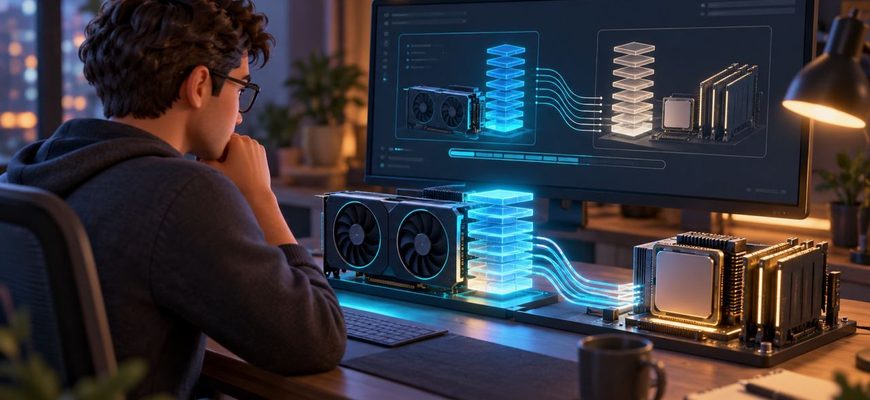
A local LLM does not necessarily have to fit entirely inside your GPU’s VRAM. If the model is too large, runtimes such as llama.cpp can keep part of it in system RAM and place the rest on the GPU. This is usually called CPU/GPU hybrid inference or, more loosely, CPU offloading.
The practical result is important: a machine with 8 GB or 12 GB of VRAM may still be able to run a model whose total memory requirements exceed that capacity. The trade-off is performance. The more work that remains on the CPU side, the less the system behaves like full-GPU inference.
CPU offloading therefore does not create extra VRAM. It gives you another way to divide a local inference workload across the memory and compute resources you already have.
What CPU offloading actually means
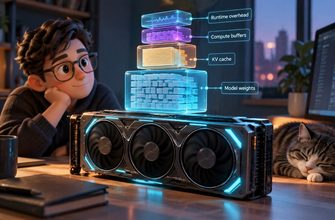
An LLM consists of many tensors containing its weights, plus runtime memory used for things such as the KV cache, temporary computation buffers and other backend-specific allocations.
When a compatible runtime uses a discrete GPU, it can place model tensors in VRAM and execute supported operations on the GPU. This is normally desirable because modern GPUs provide very high memory bandwidth and substantial parallel compute capacity.
But VRAM is finite.
If the complete workload does not fit, a runtime that supports hybrid CPU/GPU inference can keep some model data in host memory instead of requiring everything to reside on the GPU.
The official llama.cpp project, for example, explicitly supports CPU+GPU hybrid inference for partially accelerating models larger than available VRAM.
In simplified form, the machine can look like this:
| Resource | Possible role during inference |
|---|---|
| VRAM | GPU-resident model tensors, KV cache and runtime buffers depending on configuration |
| System RAM | Model data that is not resident in VRAM, plus host-side runtime allocations |
| GPU | Accelerates the portion of computation assigned to the GPU backend |
| CPU | Processes CPU-resident work and coordinates inference |
The exact placement is runtime- and backend-dependent. It should not be assumed that every byte not stored in VRAM simply becomes an equivalent byte of ordinary RAM usage.
Why a model can run without fitting entirely in VRAM
A common misconception is that a 12 GB GPU can only run models smaller than 12 GB.
That is true only if the goal is to keep the relevant workload entirely inside that GPU’s memory.
For hybrid inference, the more useful question is:
Can the combined system provide enough usable memory, while placing enough of the workload on the GPU to achieve acceptable performance?
Consider a hypothetical desktop with:
- 12 GB VRAM
- 32 GB system RAM
- a modern desktop CPU
- a supported discrete GPU
A GGUF model may be too large to run fully inside the 12 GB VRAM budget once model weights, context-related memory and runtime overhead are considered. That does not automatically make the model unusable.
With a runtime such as llama.cpp, some layers can remain on the CPU side while as many as practical are stored in VRAM.
This is fundamentally different from trying to force the complete model onto an undersized GPU.
GPU layers: the most useful mental model
For llama.cpp users, one of the most visible controls is the number of model layers placed on the GPU.
The current llama.cpp command-line interface exposes --gpu-layers, also available as -ngl or --n-gpu-layers. The setting controls the maximum number of layers stored in VRAM, and current versions can also automatically choose a value intended to fit available device memory.
A conceptual configuration might look like:
llama-cli -m model.gguf -ngl 20This is an example rather than a recommended universal value. The appropriate layer count depends on the model architecture, quantization, available VRAM, context configuration and runtime.
Increasing the number of GPU-resident layers generally shifts more of the model toward GPU execution and consumes more VRAM. Reducing it leaves more work on the CPU side and reduces the model’s VRAM requirement.
| Configuration | VRAM demand | CPU involvement | Typical implication |
|---|---|---|---|
| CPU-only | Very low for model weights | Highest | Maximum dependence on CPU and RAM performance |
| Partial GPU offload | Moderate | Moderate | Useful compromise when the full workload does not fit |
| Mostly GPU-resident | High | Lower | Closer to full-GPU performance |
| Full practical GPU offload | Highest | Lowest for model computation | Usually preferable when sufficient VRAM is available |
This is a conceptual comparison rather than a performance benchmark. Actual throughput depends heavily on the hardware, model architecture and backend.
CPU offloading does not eliminate the memory problem
Moving part of a model out of VRAM solves one constraint by creating another: you now need sufficient system memory.
If a model cannot fit in VRAM but can fit comfortably across RAM and VRAM, hybrid inference can be practical.
If it cannot fit comfortably in system memory either, performance may deteriorate severely once the operating system starts relying on swap or compressed memory. Storage is dramatically different from RAM as working memory for inference, even when the machine has a fast NVMe SSD.
This is why the amount of installed RAM matters on a local AI workstation even when the machine has a capable GPU.
Do not calculate RAM from the GGUF file size alone
A GGUF file size is useful for estimating model-weight storage, but it is not a complete prediction of runtime memory consumption.
Inference also requires memory for the context and KV cache, runtime buffers, backend allocations and the operating system itself. Multimodal models can introduce additional components.
ESTIMATE: Treat the model file size as a starting point rather than the exact amount of RAM or VRAM the process will require.
A machine with a model that technically fits into the remaining physical memory but leaves almost no headroom can still be a poor configuration.
Context length still consumes memory
Offloading model weights does not make context memory disappear.
During autoregressive inference, the runtime maintains a KV cache so previous tokens do not have to be recomputed from scratch for every generated token. Its memory requirement depends on factors including model architecture, context length, cache precision and the number of concurrent sequences.
This creates a situation that surprises many local-AI users:
A model may load successfully with a short context but fail, spill out of the intended memory budget or require a different GPU split when configured for a much larger context.
llama.cpp also exposes controls for KV-cache placement and cache data types. These can change the memory equation, but they are advanced tuning options rather than free memory reductions.
RECOMMENDATION: Choose the context window you actually need before maximizing GPU offload. Do not configure an enormous context simply because the model advertises support for it.
Quantization and CPU offloading solve different problems
Quantization and CPU offloading are often discussed together, but they should not be confused.
Quantization reduces the storage precision of model weights.
CPU/GPU hybrid inference changes where model data and computation are placed.
According to the llama.cpp quantization documentation, converting weights from higher-precision formats to lower-bit quantized formats can substantially reduce model size, although quantization can introduce some accuracy loss.
The two techniques can therefore be combined.
Suppose a higher-precision version of a model is far beyond the practical memory capacity of a workstation. A quantized GGUF version may reduce the memory requirement enough that a substantial portion fits in VRAM, while the remainder can stay on the CPU side.
That is often much more useful than trying to run the higher-precision version with extreme memory pressure.
| Approach | Main purpose | Main trade-off |
|---|---|---|
| Quantization | Reduce model weight size | Lower precision can affect model quality |
| CPU/GPU hybrid inference | Run a model beyond available VRAM | More CPU-side work can reduce performance |
| Shorter context | Reduce context-related memory use | Less usable conversation or document history |
| Smaller model | Reduce total compute and memory requirements | May reduce capability for some workloads |
Why partial offloading can be much slower than full GPU inference
A GPU is not merely additional memory. Its memory subsystem and compute hardware are designed for highly parallel workloads.
When part of an LLM remains on the CPU side, those parts of the inference pipeline become dependent on CPU compute and system-memory bandwidth. Data movement and synchronization between host and accelerator can also matter.
The exact penalty is not constant.
It depends on factors including:
- the CPU architecture and memory bandwidth;
- the GPU and its VRAM bandwidth;
- the number and type of tensors placed on each device;
- model architecture;
- quantization format;
- prompt-processing workload;
- context length;
- backend implementation;
- memory configuration.
For that reason, there is no honest universal claim such as “offloading half the model makes inference twice as slow.”
It does not scale that neatly.
FACT: llama.cpp supports CPU+GPU hybrid inference specifically so models larger than available VRAM can still receive partial GPU acceleration.
ESTIMATE: As more of the workload remains CPU-bound, performance will generally move further away from a configuration where the relevant model workload fits on the GPU.
How to find a practical offload configuration
The best configuration is usually discovered by starting with the workload rather than an arbitrary GPU-layer number.
1. Choose the model and quantization first
Decide which model you actually need and choose an appropriate quantized build if using GGUF.
A more compact quantization can allow significantly more of the model to reside in VRAM. However, using the smallest possible quantization should not automatically be the goal because more aggressive quantization can affect quality.
2. Set a realistic context length
Configure the context required by your workload.
A private document assistant may genuinely need more context than a simple command-line assistant. A short-form coding or classification workflow may need much less.
This decision should happen before filling VRAM with model layers because context-related allocations also need room.
3. Leave memory headroom
Do not assume that reported GPU capacity is available exclusively for model weights.
The runtime can require additional GPU memory, and a desktop GPU may also be driving displays or other GPU applications.
RECOMMENDATION: Aim for a stable configuration with some free VRAM rather than a setup that fails whenever another application allocates a few hundred megabytes.
4. Offload as much as is useful
With llama.cpp, --gpu-layers can control how much of the model is stored in VRAM. Current llama.cpp builds also include automatic fitting behaviour that can adjust unset parameters around available device memory.
Manual tuning remains useful when you want predictable memory behaviour or need to reserve VRAM for another workload.
5. Test the actual workload
A successful model load is not enough.
Test the kinds of prompts you intend to use, at the context lengths you expect to reach. Observe both RAM and VRAM consumption and evaluate whether generation latency is acceptable.
A configuration that works well for short interactive prompts may behave differently when processing a long document.
When CPU offloading makes sense
Hybrid inference is particularly useful when your preferred model is only moderately beyond your GPU’s memory capacity.
For example, it can make sense when you already own a capable GPU but need several additional gigabytes of host memory to run a particular quantized model. It can also be useful when model capability matters more than maximum token-generation speed.
Another useful case is experimentation. CPU offloading can let you test whether a larger model is valuable for your workload before changing hardware.
For a private local system, it also preserves one of the central advantages of local inference: model inputs and generated data can remain on hardware you control rather than being sent to an external inference service.
When CPU offloading is the wrong solution
The fact that a model can run does not mean it is the right model for the machine.
If most of a large model must remain CPU-bound and interactive performance becomes unacceptable, moving to a smaller model or a more compact quantization can be the better decision.
The same applies when the machine has insufficient RAM. Heavy swapping is not a substitute for adequate physical memory.
CPU offloading is also less attractive for workloads where latency or throughput matters more than obtaining the capabilities of a larger model. A smaller model that fits comfortably in VRAM can be more useful in practice than a stronger model that responds too slowly for the intended workflow.
Common mistakes
Assuming model file size equals required VRAM
It does not. Model weights are only part of the runtime memory budget.
Using the maximum advertised context window
Longer context can increase memory consumption substantially. Configure context according to the workload rather than the model’s headline limit.
Filling VRAM to the last megabyte
A configuration with no headroom can become unstable when context allocations grow or other applications use the GPU.
Expecting CPU offloading to perform like extra VRAM
System RAM and VRAM are not interchangeable resources. Moving part of inference to the CPU changes both memory placement and performance characteristics.
Choosing a much larger model simply because it loads
Usability matters more than successfully reaching the first token. Compare the larger hybrid model against a smaller model that fits comfortably on your hardware.
CPU offloading versus buying more VRAM
CPU offloading is best understood as a flexibility feature, not a replacement for GPU memory.
If you occasionally need to run a model slightly larger than your GPU can hold, hybrid inference can extend the useful life of existing hardware.
If your main workload constantly requires large models and performance matters, additional VRAM changes the problem more fundamentally because a larger portion of the inference workload can remain on the accelerator.
The decision is therefore workload-dependent.
| Situation | Practical direction |
|---|---|
| Model almost fits in VRAM | Partial CPU offloading is worth trying |
| Model is substantially larger than VRAM | Test performance carefully; consider stronger quantization or a smaller model |
| System RAM is also nearly full | Reduce memory requirements rather than relying on swap |
| Low latency is important | Prefer a model that fits mostly or fully on the accelerator |
| Larger-model capability matters more than speed | Hybrid CPU/GPU inference can be a reasonable trade-off |
The practical rule
Do not treat VRAM capacity as a hard dividing line between models your computer can and cannot run.
Instead, think of local inference as a memory hierarchy. Quantization determines how compactly the model weights can be represented. VRAM determines how much of the workload can stay close to GPU compute. System RAM provides additional capacity for hybrid inference. Context length and runtime settings determine how much memory remains available once the model is loaded.
If the complete workload fits comfortably in VRAM, that is usually the simplest path to strong GPU performance. If it misses by a manageable amount, CPU offloading can make the model usable without changing hardware.
But when a model exceeds the machine’s natural capabilities by a wide margin, successfully loading it is not the same as running it well. In that situation, a smaller model, a different quantization or more suitable hardware is often the more practical local-AI configuration.