RAM
A 16-core CPU can load a quantized local LLM, show activity across many cores, and still generate text much more slowly than expected. Adding threads may help at first.
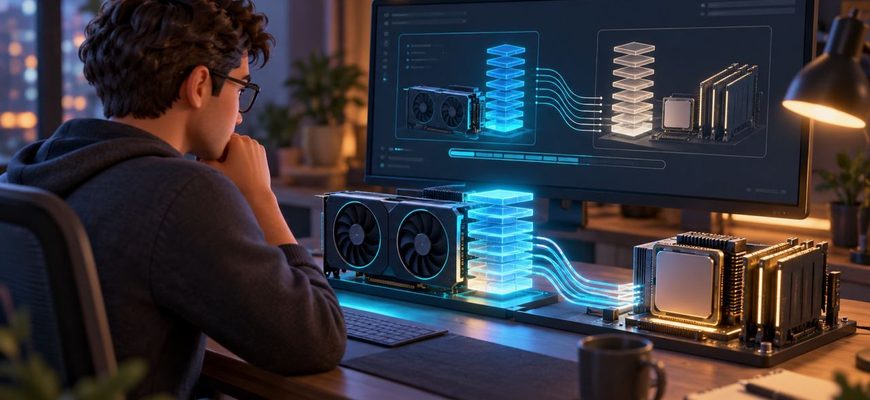
A local LLM does not necessarily have to fit entirely inside your GPU’s VRAM. If the model is too large, runtimes such as llama.cpp can keep part