Hardware
An AI rack can fit the room and still exceed its floor limits. The key is how its weight reaches the building, including during delivery.
Intel's GPU D-series introduces an unusual choice: up to 480GB of LPDDR5X memory instead of HBM. Here's why memory capacity, bandwidth and power consumption
A 12GB GPU can run a 30B local LLM — but usually not entirely in VRAM. Here is what quantization, CPU offloading and context memory actually do.
A faster PCIe connection does not always make local LLM inference faster. Learn when PCIe bandwidth matters for model loading, CPU offloading, and GPU performance.
A local LLM does not necessarily have to fit entirely inside your GPU’s VRAM. If the model is too large, runtimes such as llama.cpp can keep part
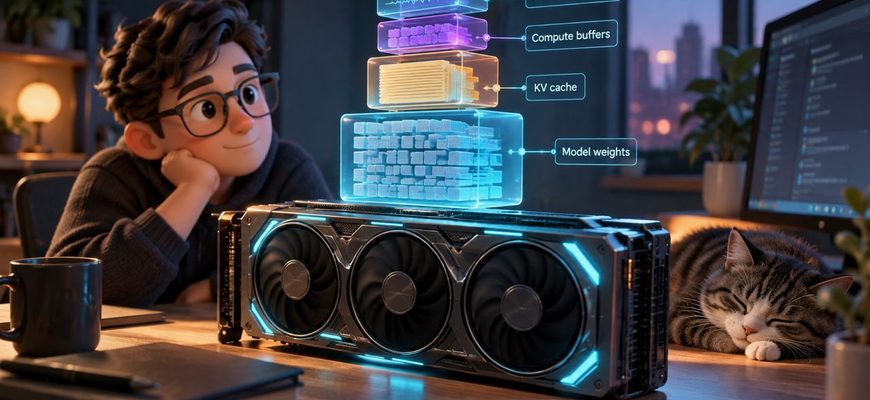
A 14 GB model file does not mean you need exactly 14 GB of VRAM to run it. The weights are only one part of the memory used during inference.
A local LLM can fit comfortably into your GPU at an 8,000-token context and run out of memory when you increase that context several times over.

A good local AI machine is not simply “the computer with the fastest GPU.” The right build depends on model size, context length, speed expectations, power