- What actually uses VRAM when you run an LLM?
- Model weights usually consume most of the memory
- Why the GGUF file size is a useful starting point — but not the answer
- Context length can materially change VRAM requirements
- Maximum supported context is not the context you must allocate
- KV cache precision is another memory lever
- Compute buffers need space too
- How to estimate the VRAM you need
- Step 1: Start with the actual quantized model
- Step 2: Decide how much of the model you want on the GPU
- Step 3: Choose a realistic context length
- Step 4: Account for the KV cache
- Step 5: Leave room for compute and runtime allocations
- What different VRAM capacities mean in practice
- What happens when the model does not fit in VRAM?
- More VRAM can be useful even when your current model already fits
- Common mistakes when estimating local LLM VRAM
- Matching GPU VRAM directly to the GGUF file size
- Estimating from parameter count without considering quantization
- Ignoring context length
- Assuming maximum context is free
- Confusing “runs” with “fits in VRAM”
- Treating published VRAM numbers as universal
- How to check VRAM usage instead of guessing
- So how much VRAM should you plan for?
A 14 GB model file does not mean you need exactly 14 GB of VRAM to run it. The weights are only one part of the memory used during inference. The runtime may also need GPU memory for the KV cache, compute buffers and other allocations — and those requirements change with context length and configuration.
This is why two people can load the same quantized model and report different VRAM usage without either result being wrong.
For local LLMs, the useful question is not simply “How large is the model?” It is: how much memory will the complete inference configuration require?
The practical way to answer that question is to treat VRAM as a budget shared by several components rather than as a container that only needs to hold a model file.
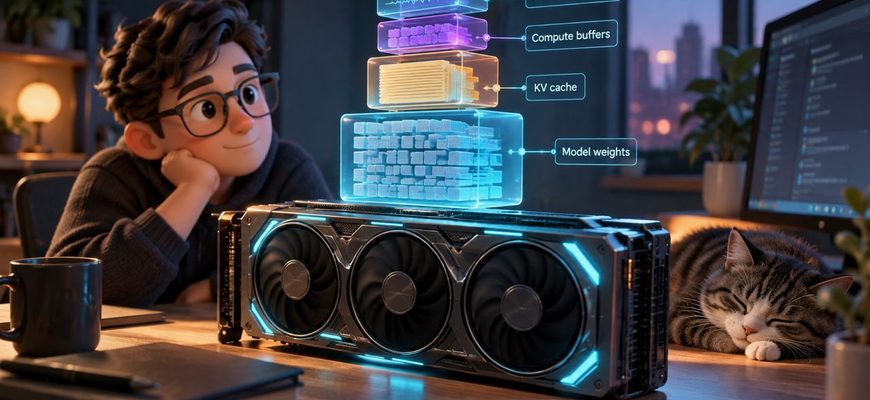
What actually uses VRAM when you run an LLM?
For a typical GPU-accelerated local inference workload, memory consumption can be thought of as four broad parts:
- Model weights — usually the largest allocation.
- KV cache — memory associated with the active context.
- Compute buffers — temporary memory needed while performing inference.
- Runtime and backend overhead — additional allocations made by the inference stack and GPU environment.
A useful planning model is therefore:
required VRAM ≈ GPU-resident weights + KV cache + compute/runtime memory + safety margin
This is an estimate, not a universal formula. Exact allocations depend on the model architecture, runtime, quantization, context length, batch settings, cache precision and which tensors are actually placed on the GPU.
The distinction matters because looking only at the model’s parameter count or GGUF file size ignores several allocations that can become significant.
Model weights usually consume most of the memory
Start with the weights. An unquantized model stores every parameter at some numerical precision. As a rough theoretical calculation, a model with 8 billion parameters stored at 16 bits per parameter requires about 16 GB just for the parameters:
8 billion × 2 bytes ≈ 16 GB
At 8 bits per parameter, the theoretical payload falls toward 8 GB. At 4 bits, it approaches 4 GB.
Real model files do not map perfectly to these simple numbers. Quantization formats have metadata, some tensors may use different precision, and implementations differ. The calculation is useful for understanding the relationship, not for predicting an exact allocation.
This is why quantization is so important for local inference. Projects such as llama.cpp support multiple low-bit quantization formats specifically to reduce model size and memory requirements.
| Weight precision | Theoretical bytes per parameter | Approximate weight payload for 8B parameters |
|---|---|---|
| FP16 / BF16 | 2 bytes | 16 GB |
| 8-bit | 1 byte | 8 GB |
| 4-bit | 0.5 bytes | 4 GB |
Estimate: these figures describe the theoretical parameter payload, not guaranteed VRAM usage. A real quantized file and a running model will differ from this simplified calculation.
Why the GGUF file size is a useful starting point — but not the answer
For a GGUF model used with llama.cpp or a runtime built around it, the model file size gives you a much better starting point than parameter count alone.
A llama.cpp maintainer has explained that the memory allocated for model weights should, in most cases, be very close to the size of the model file on disk. But the same runtime separately allocates memory for the KV cache and compute buffers.
So if a quantized GGUF file is 8 GB, an 8 GB GPU should not automatically be expected to hold the complete workload.
You still need room for everything around the weights.
Recommendation: do not buy or choose a GPU by matching its advertised VRAM capacity exactly to the size of the GGUF file you intend to run.
Context length can materially change VRAM requirements
The next major variable is context.
During autoregressive inference, transformer models commonly maintain a key-value cache — usually called the KV cache — so previously processed tokens do not have to be recomputed from scratch for every generated token.
That cache consumes memory.
As the allocated context becomes larger, the KV cache generally becomes larger as well. The exact relationship depends on the model architecture and runtime implementation, so there is no reliable universal rule such as “every 1,000 tokens requires X MB of VRAM.”
Ollama’s own documentation explicitly warns that increasing context length increases the memory required to run a model. Its current defaults also vary the allocated context according to available VRAM.
This has an important practical consequence: a model that fits comfortably at a modest context can stop fitting when you configure a much larger context window.
Maximum supported context is not the context you must allocate
Suppose a model supports a very large context window. That does not mean every local session needs to allocate that entire capacity.
If you mostly ask short questions, summarize modest documents or use a compact system prompt, allocating an enormous context may simply consume memory that could otherwise be used for a larger model or more GPU-resident layers.
Large contexts make more sense for workloads such as long-document analysis, large coding sessions, agents carrying substantial state, or retrieval workflows that insert significant amounts of material into the prompt.
Recommendation: choose context length from the workload first. Do not automatically configure the model’s maximum supported context just because the model allows it.
KV cache precision is another memory lever
The KV cache itself does not necessarily have to use one fixed data type.
Current llama.cpp options allow separate cache types for keys and values, including formats such as f32, f16, bf16, q8_0 and several 4- and 5-bit types.
Lower-precision cache formats can reduce cache memory requirements, although support, quality implications and performance characteristics depend on the backend and configuration.
This is another reason that a single statement such as “Model X requires 12 GB of VRAM” is incomplete unless the test configuration is also specified.
Model quantization, cache type and context allocation can all change the result.
Compute buffers need space too
Inference also requires working memory for intermediate calculations.
In llama.cpp, these allocations are visible separately from the model weights and KV cache. Their size can depend on runtime parameters and implementation choices.
Compute memory is usually less intuitive than model weight memory because you cannot infer it directly from the GGUF file size. It is one reason a configuration that appears to fit on paper can fail near the VRAM limit.
The practical lesson is simple: leave headroom.
A GPU whose entire capacity is consumed by your estimated weight allocation leaves no realistic budget for the rest of inference.
How to estimate the VRAM you need
You can make a useful estimate without pretending to know an exact universal number.
Step 1: Start with the actual quantized model
Do not estimate from the parameter count if you already know which model file you intend to use.
A 4-bit quantized model and an FP16 version of the same architecture belong to completely different memory classes. Even different quantization schemes at nominally similar bit rates can produce different file sizes.
Use the actual model artifact as your starting point.
Step 2: Decide how much of the model you want on the GPU
If the complete model fits in VRAM with enough room for the context and runtime allocations, full GPU offload is usually the simplest high-performance target.
If it does not fit, that does not necessarily mean the model cannot run.
llama.cpp explicitly supports CPU+GPU hybrid inference, allowing models larger than available VRAM to be partially accelerated on the GPU. Its runtime exposes controls for how many model layers are stored in VRAM.
The trade-off is performance: moving more of the workload away from the GPU generally means relying more heavily on system RAM, CPU computation and the interconnect between CPU and GPU.
So there are two different questions:
Can this model run? and Can this model fit entirely in VRAM?
They are not the same question.
Step 3: Choose a realistic context length
Estimate the context your workload actually needs.
For interactive chat with relatively short histories, that may be much smaller than the model’s maximum. Document analysis, coding assistants and agentic workloads can require substantially more.
Then test the intended context rather than benchmarking the model at one context size and assuming memory usage will remain unchanged at another.
Step 4: Account for the KV cache
The runtime can often tell you exactly how much memory it allocated for the cache.
For example, llama.cpp reports separate model, KV and compute buffer allocations in relevant runtime output. This is more useful than relying on a generic online VRAM table because it reflects the actual model and configuration you are running.
If VRAM becomes tight as you increase context, the KV cache is one of the first allocations to inspect.
Step 5: Leave room for compute and runtime allocations
Do not plan around using every last megabyte of advertised VRAM for weights.
The exact margin cannot be specified as a universal percentage. Backend, model architecture, batch parameters, context and other applications using the GPU all affect the available memory.
Recommendation: treat a configuration that barely fits as a configuration that still needs testing, not as proof that the GPU has sufficient capacity.
What different VRAM capacities mean in practice
It is tempting to create a simple table saying that 8 GB runs one model class, 12 GB another and 24 GB another. That can be useful only if the assumptions remain visible.
A better way to interpret GPU capacity is as a memory budget.
| VRAM situation | Practical implication |
|---|---|
| Weights comfortably below VRAM capacity | More room remains for KV cache, compute buffers and larger contexts. |
| Weights close to total VRAM | The model may require reduced context, different cache settings or partial CPU offload. |
| Weights larger than VRAM | Full GPU residency is not possible, but hybrid CPU/GPU inference may still work. |
| Large unused VRAM margin | You may be able to use a larger context, a less aggressive quantization or a larger model. |
This framework is more durable than a list of specific GPUs because the underlying constraint remains the same even as hardware and models change.
What happens when the model does not fit in VRAM?
With a runtime that supports partial GPU offloading, exceeding VRAM does not automatically prevent inference.
llama.cpp, for example, supports hybrid CPU+GPU execution and can keep only part of the model on the GPU. The rest remains on the CPU side.
This is particularly useful when system RAM is plentiful but GPU memory is limited.
There is a cost. A fully GPU-resident workload avoids much of the CPU-side work and data movement involved in hybrid inference. Partial offloading can therefore make a model usable without making it equally fast.
The exact slowdown depends on the model, CPU, memory bandwidth, GPU, backend and offload configuration. It should be measured rather than assumed.
On supported configurations, other mechanisms can also change out-of-memory behavior. For example, llama.cpp documents an optional CUDA unified-memory mode on Linux that can allow allocations to spill into system RAM instead of immediately failing when VRAM is exhausted. That can make an oversized workload runnable, but it should not be confused with having sufficient physical VRAM.
More VRAM can be useful even when your current model already fits
Extra VRAM is not only about moving to a model with more parameters.
A larger memory budget can also let you use:
- less aggressive weight quantization;
- larger context allocations;
- higher-precision KV cache settings;
- more GPU-resident layers;
- multiple model components required by a workflow;
- more room for concurrent inference, depending on the runtime.
This means two users running nominally the same model can benefit differently from additional VRAM.
Someone doing short interactive prompts may prefer to spend the extra capacity on a larger or higher-quality quantization. Someone building a document assistant may care more about context and cache capacity.
Common mistakes when estimating local LLM VRAM
Matching GPU VRAM directly to the GGUF file size
An 11 GB file and an 11 or 12 GB GPU are not automatically a safe match. The runtime needs additional memory beyond the model weights.
Estimating from parameter count without considering quantization
“8B model” does not describe a memory requirement. The precision and quantization format are essential.
Ignoring context length
A model that fits at one context allocation may consume substantially more memory when configured for a much larger context.
Assuming maximum context is free
A model’s supported context window describes capability, not zero-cost memory. Allocating more context can increase memory consumption.
Confusing “runs” with “fits in VRAM”
Hybrid inference can make an oversized model runnable by keeping part of it in system memory. That does not mean the model fits on the GPU, nor that performance will match full GPU residency.
Treating published VRAM numbers as universal
A memory figure without the model file, quantization, context length, cache configuration, runtime and offload settings is incomplete.
How to check VRAM usage instead of guessing
Estimation is useful before downloading a model or choosing hardware. Once you can run the software, measurement is better.
With llama.cpp, inspect the runtime’s reported memory allocations and pay attention to the distinction between model weights, KV cache and compute buffers.
With Ollama, ollama ps can show whether a loaded model is running entirely on the GPU or is split between CPU and GPU, together with its allocated context.
This is particularly useful when tuning a machine with limited VRAM. Instead of asking only whether the model starts, check what the runtime actually did.
If it silently moved part of the workload to the CPU, the model may be usable while performing very differently from the fully GPU-resident configuration you expected.
So how much VRAM should you plan for?
Start with the quantized model you actually intend to run, not with its parameter count. Treat its weight size as the beginning of the calculation rather than the final requirement.
Then add the memory demanded by your intended context, cache configuration and runtime. Leave enough headroom for compute buffers and other allocations. If the complete workload does not fit, decide whether reducing context, using a smaller quantization or accepting partial CPU offload is the better compromise.
The important distinction is between three targets:
- Runnable: the system can execute the model, potentially with substantial CPU involvement.
- Mostly GPU accelerated: most of the useful workload fits on the GPU, but some components may remain elsewhere.
- Comfortably GPU resident: the intended model, context and inference buffers fit in VRAM with practical headroom.
For a machine you already own, the first target may be enough. For a workstation being selected specifically for local AI, the third is usually the more useful design goal.
That is the practical answer to the VRAM question: do not size the GPU for the model file. Size it for the inference workload.