quantization
A 16-core CPU can load a quantized local LLM, show activity across many cores, and still generate text much more slowly than expected. Adding threads may help at first.
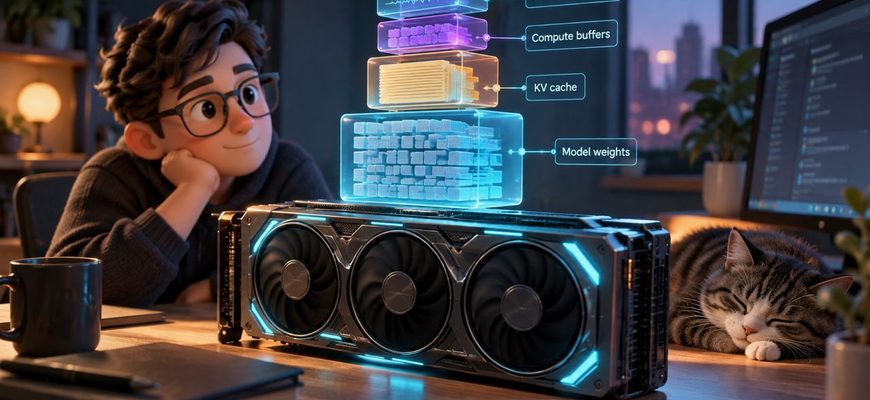
A 14 GB model file does not mean you need exactly 14 GB of VRAM to run it. The weights are only one part of the memory used during inference.
A local LLM can fit comfortably into your GPU at an 8,000-token context and run out of memory when you increase that context several times over.