Inference
A model can finish quickly while the app keeps you waiting. Follow the request through retrieval, streaming, proxies and rendering to find which delay
A GPU-utilization meter counts activity, while you experience waiting time. Understanding the gap explains why a fully occupied accelerator can still deliver
Your local LLM fits in VRAM — until you increase the context window. Here is why KV cache can consume several extra gigabytes and trigger an OOM.
A 12GB GPU can run a 30B local LLM — but usually not entirely in VRAM. Here is what quantization, CPU offloading and context memory actually do.
Two requests can contain almost the same 20,000-token prompt and still reach the first generated token at very different times. On the first request, the
Three people are using the same local AI server. Two answers are already streaming at a comfortable pace. Then a third user pastes a long document and presses Send.
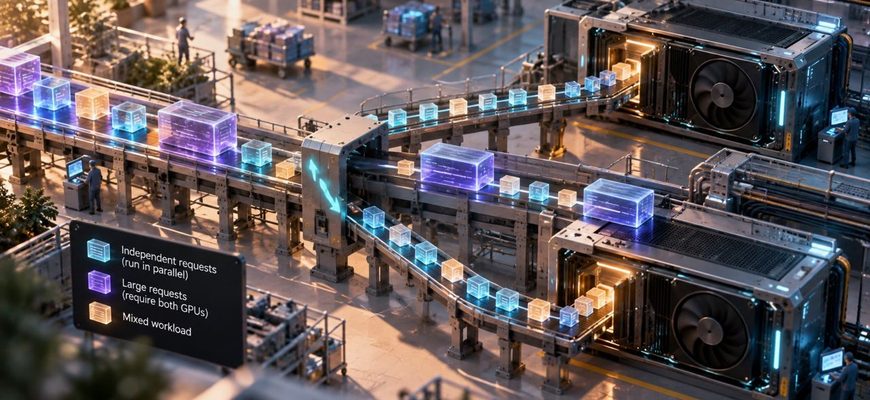
There is an appealingly simple upgrade path for a busy local AI server: install another GPU. Twice the accelerators should mean something close to twice
A local AI server can feel almost instantaneous when one person is using it. Add a second conversation and it may still feel fine. Add several people with
A local LLM produces 100 tokens per second. On paper, that sounds fast. Then a real user sends a long prompt and waits several seconds before anything
A local LLM does not have one meaningful “tokens per second” number. Before it can write the first token of an answer, it has to process the tokens already in the prompt.