Servers
AI Infrastructure
AI servers are arriving before data centers have enough power to run them. Discover why electricity shortages are delaying deployment, even as powerful
Deleting a document doesn't always erase what your AI can find. Discover how RAG search indexes retain information, why deleted files may remain searchable
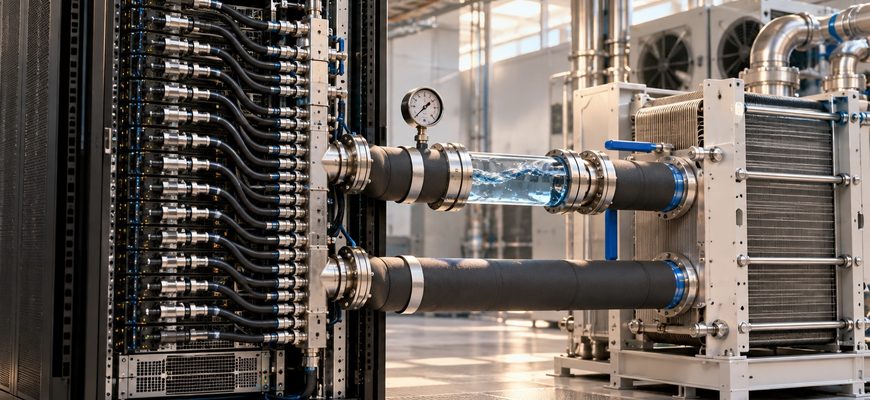
A single AI rack can produce an enormous amount of heat. We examine Lenovo's 135 kW GB300 NVL72 design, calculate how much coolant would need to circulate
LLM request cancellation should stop work that nobody needs anymore. Yet you can ask your local AI server for a long report, read the first few lines and
Project Natick · Microsoft 864 servers. Two years underwater. No technicians. Microsoft sealed an entire datacenter inside a steel cylinder and lowered
A 16-core CPU can load a quantized local LLM, show activity across many cores, and still generate text much more slowly than expected. Adding threads may help at first.
A shared LLM server is approaching its limit. The model weights still fit. The GPU has not reported an out-of-memory error. But long conversations and
The shared LLM server has not crashed. GPU utilization remains high, requests are still finishing, and the monitoring dashboard shows no conventional out-of-memory failure.
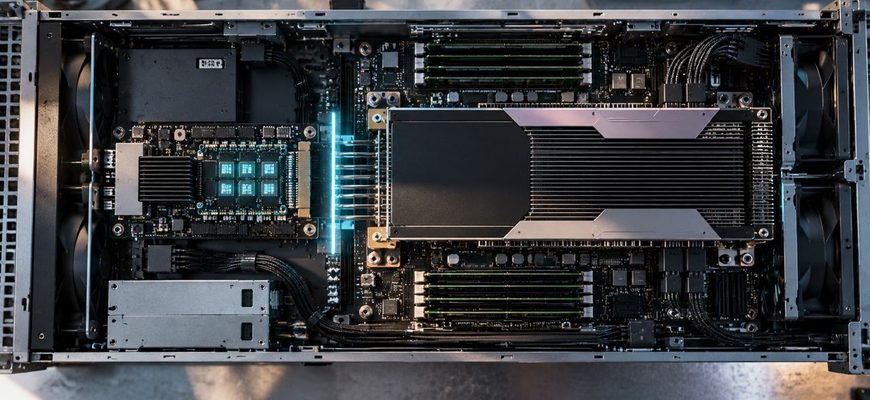
A large language model can have a powerful GPU almost to itself and still produce a single conversation one token at a time. The accelerator finishes one
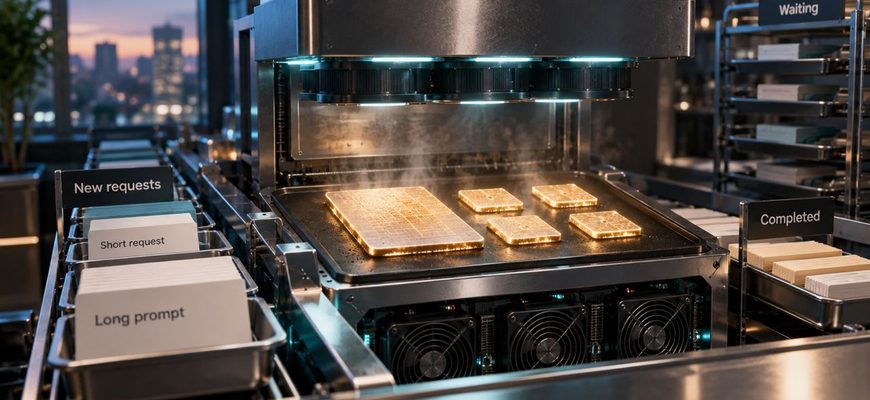
Four people are talking to the same local LLM. One asks a short question and gets an answer in seconds. Another requests a long explanation.