GGUF
A local LLM does not necessarily have to fit entirely inside your GPU’s VRAM. If the model is too large, runtimes such as llama.cpp can keep part
Q4_K_M, Q5_K_M and Q8_0 can run the same model with very different memory requirements. Here is how to choose without wasting VRAM.
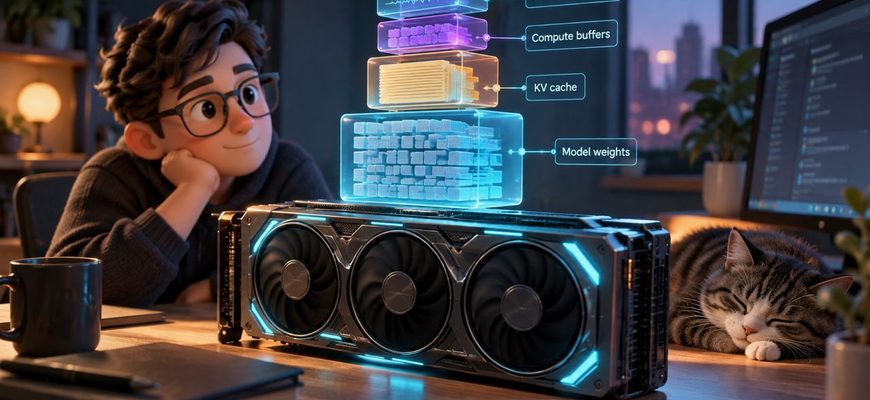
A 14 GB model file does not mean you need exactly 14 GB of VRAM to run it. The weights are only one part of the memory used during inference.