Skip to content
Search for:
il.digital
Local AI, language models and GPU infrastructure — explained clearly.
Home
Real-World Stories
Explore Topics
All Articles
About
Home
CPU Offloading
Hardware
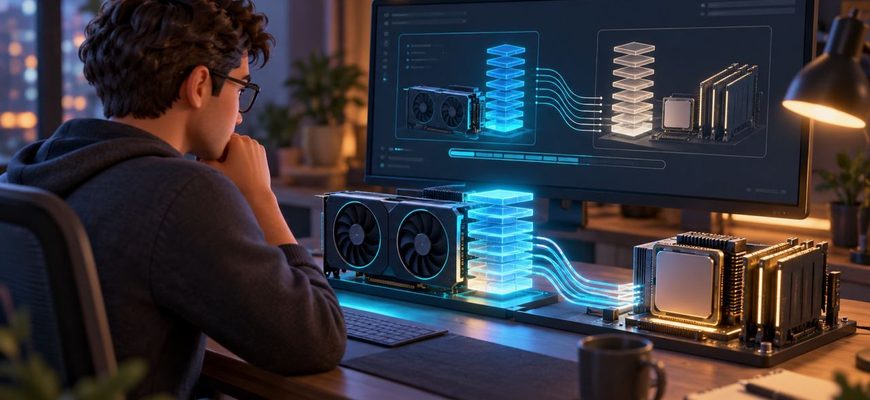
CPU Offloading Explained: How to Run a Local LLM That Doesn’t Fit in VRAM
17.09.2026
1
637
A local LLM does not necessarily have to fit entirely inside your GPU’s VRAM. If the model is too large, runtimes such as llama.cpp can keep part