A local model may advertise a 32K, 64K, 128K, or even larger context window. That does not mean you should configure your local runtime to use the maximum.
Context has a cost. Longer sequences require more prompt processing, and the inference engine needs memory for the model’s KV cache. On a machine with limited VRAM, allocating an unnecessarily large context can turn an otherwise comfortable model into one that barely fits, requires CPU offloading, or leaves too little memory for parallel requests.
The useful question is therefore not “What is the maximum context this model supports?” It is “How much context does my workload actually need?”
- What context length actually controls
- Maximum supported context is not recommended context
- Why longer context consumes more memory
- A 14 GB model does not mean a 16 GB GPU has 2 GB left for everything else
- Long context also costs processing time
- How much context do common local AI workloads need?
- Do not use context as long-term memory
- RAG should reduce the need for huge context, not fill it
- Long-context document processing has alternatives
- Context becomes more expensive on a shared local server
- Can you reduce KV-cache memory?
- How to find your practical context setting
- 1. Measure a representative workload
- 2. Leave room for output
- 3. Test memory at realistic context
- 4. Measure time to first token
- 5. Test concurrency separately
- 6. Increase only when the workload requires it
- Common context-window mistakes
- Setting the maximum because it is available
- Looking only at model-file size
- Testing only with tiny prompts
- Keeping unlimited conversation history
- Retrieving too much text in RAG
- Ignoring server concurrency
- When very long context does make sense
- A practical decision rule
What context length actually controls
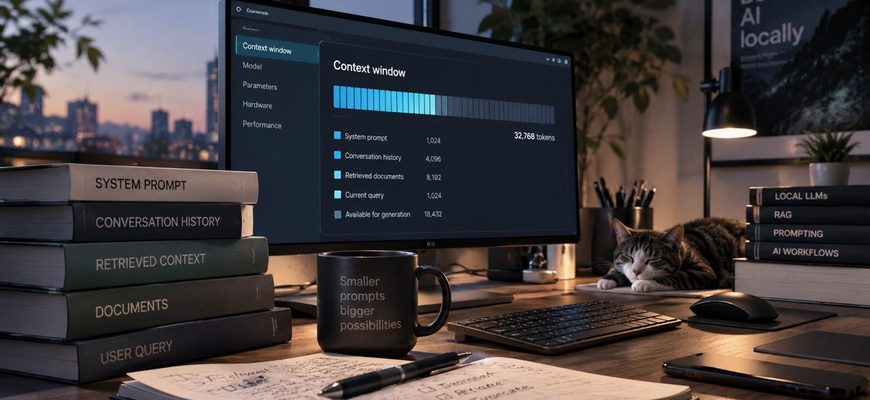
The context window is the amount of tokenized information the model can work with during an inference sequence. Depending on the application, that can include the system prompt, conversation history, retrieved documents, tool-related information, the current user request, and generated tokens.
Tokens are not the same as words. The relationship varies by language and content, so converting a context limit directly into a fixed number of pages or words is only an estimate.
If a runtime is configured for a context of 8192 tokens, for example, the relevant sequence must fit within that token budget. Increasing the configured context gives the runtime room for longer sequences, but it does not automatically improve the model’s answers.
In llama.cpp, context size is configurable through --ctx-size. The project also supports using the context information stored with the model rather than always forcing a manually selected value.
Maximum supported context is not recommended context
It helps to separate three different numbers:
| Number | What it means |
|---|---|
| Model-supported context | The sequence length the model architecture and training or context-extension method are designed to support |
| Runtime context | The context capacity allocated or configured by your inference software |
| Actual context | The number of tokens your current workload really uses |
These do not need to be identical.
A model might support a very long context while your normal requests rarely exceed a few thousand tokens. Configuring the runtime around the actual workload can be more practical than treating the model’s maximum as a target.
RECOMMENDATION: Start from the context your workload requires, not from the largest number in the model card.
Why longer context consumes more memory
Model weights are not the only data that inference needs to keep in memory.
During autoregressive generation, transformer inference commonly stores key and value states from previous tokens. This is the KV cache. It prevents the runtime from having to recompute the same attention information from scratch for every newly generated token.
The cache therefore grows with the sequence capacity and depends on characteristics of the model architecture.
A useful conceptual memory budget is:
inference memory ≈ model weights + KV cache + compute buffers + runtime overhead
This is intentionally not a universal formula for calculating exact VRAM requirements. KV-cache size depends on factors including architecture, layer count, attention design, cache data type, configured context and runtime implementation.
llama.cpp, for example, exposes separate cache data-type controls for K and V through --cache-type-k and --cache-type-v. Its current CLI supports multiple cache representations rather than requiring only one fixed precision. :contentReference[oaicite:0]{index=0}
The practical implication is simple: two models with similar weight-file sizes can have different memory behavior at long context.
A 14 GB model does not mean a 16 GB GPU has 2 GB left for everything else
This is where local context settings often become confusing.
Suppose a quantized model’s weights occupy roughly 14 GB. A 16 GB GPU appears, at first glance, to have enough VRAM.
But inference needs additional allocations. The KV cache is one of them, and there are also compute buffers and backend overhead.
llama.cpp reports these categories separately when initializing a model. Its developers describe model-weight buffers, KV-cache buffers and compute buffers as distinct allocations. Context and cache-type settings affect the KV-cache allocation. :contentReference[oaicite:1]{index=1}
As a result, “the GGUF file is smaller than my VRAM” is not a reliable test for whether the entire workload will fit comfortably on the GPU.
You need headroom for inference.
Long context also costs processing time
Memory is only half of the problem.
Before a model generates an answer, it needs to process the input tokens. This stage is often called prompt processing or prefill.
If you send a short question with a small system prompt, there is relatively little input to process. If you send a large document plus conversation history plus retrieved RAG chunks, there may be tens of thousands of input tokens before generation starts.
This can increase time to first token even if subsequent token generation remains reasonably fast.
That distinction is useful when diagnosing local inference:
| Symptom | Likely area to investigate |
|---|---|
| Long wait before first token | Prompt size and prefill performance |
| Fast start but slow generation | Decode performance, model size, hardware and offloading |
| Performance degrades as chats grow | Conversation context and KV-cache pressure |
| Short chat works but long documents cause memory problems | Context allocation and available VRAM/RAM |
A large context window is therefore not free simply because the model technically supports it.
How much context do common local AI workloads need?
There is no universal ideal context size, but workload type gives you a much better starting point than model specifications alone.
| Workload | Context behavior | What matters |
|---|---|---|
| Short assistant chats | Usually modest | System prompt and recent conversation history |
| Coding assistant | Can grow quickly | Source files, errors, diffs and generated code |
| RAG | Controlled by retrieval | Number and size of retrieved chunks |
| Document analysis | Potentially large | Document length and whether the whole document must be present at once |
| Long-running assistant | Grows over time | History management and summarization |
| Multi-user server | Multiplied across active sequences | Concurrency and memory capacity |
These categories deliberately do not prescribe a fixed token count. A coding session involving one function is different from repository-scale context, and a RAG system retrieving three compact passages is different from one injecting entire documents.
The right number should come from measuring representative prompts.
Do not use context as long-term memory
A common local-assistant design is to keep appending every previous message to the prompt.
Initially this works well. Eventually the conversation contains thousands of tokens that may have little relevance to the current question.
The result is larger prompts, more processing, higher cache requirements, and eventually a full context window.
A large context window delays this problem. It does not solve it.
For assistants that need to operate over long periods, it is usually better to decide which information deserves to remain in active context.
Possible strategies include keeping recent messages, summarizing older exchanges, retrieving relevant historical information on demand, or storing structured state outside the prompt.
RECOMMENDATION: Treat context as working memory, not as an unlimited conversation database.
RAG should reduce the need for huge context, not fill it
Retrieval-augmented generation is especially relevant to local AI because it lets the system search a larger knowledge base and insert only selected information into the prompt.
But a poorly configured RAG pipeline can defeat that advantage.
Imagine that retrieval returns 20 large chunks for every question. The model must process all of that material even if only two chunks contain useful evidence.
This has three costs:
- more prompt-processing work;
- more active context;
- more irrelevant material competing for the model’s attention.
Retrieval quality therefore matters to inference efficiency as well as answer quality.
A practical RAG pipeline should retrieve enough evidence to answer the question without automatically filling every available token.
Long-context document processing has alternatives
Suppose you want to summarize a document that is larger than the context you can comfortably run.
The obvious solution is to increase context until the entire document fits. That is not always the best solution.
Depending on the task, alternatives include splitting the document into sections, extracting information from chunks independently, creating intermediate summaries, or using retrieval to locate relevant sections before asking the final question.
These approaches are not interchangeable.
If the task depends on relationships between information at opposite ends of a document, chunking can lose useful global context. If the task is extracting invoice fields from hundreds of independent pages, forcing every page into one prompt may provide little benefit.
The workflow should determine whether long context is actually necessary.
Context becomes more expensive on a shared local server
A context configuration that works comfortably for one interactive user may be inappropriate for a server handling multiple simultaneous sequences.
llama.cpp supports parallel sequences, and its server implementation includes controls for how context and KV-cache resources are handled across slots. The current server documentation includes a per-slot context control and describes sizing a shared KV pool in relation to the number of parallel sequences. :contentReference[oaicite:2]{index=2}
This creates a basic capacity-planning problem.
If you increase the context available to each active request, the memory budget available for concurrency can shrink. Conversely, limiting context per request can make it possible to serve more simultaneous workloads on the same hardware.
For a personal workstation, maximizing a single sequence may be reasonable. For a household or small-office AI server, predictable per-user limits can be more useful than the largest possible context window.
Can you reduce KV-cache memory?
Some runtimes expose controls over KV-cache representation.
Current llama.cpp builds allow K and V cache types to be configured independently, including lower-precision options. KV-cache offloading is also configurable. :contentReference[oaicite:3]{index=3}
Using a lower-precision cache can reduce memory requirements, which may be valuable when long context is important and VRAM is constrained.
But this should be treated as a trade-off rather than free memory.
FACT: Lower-precision KV-cache formats require less storage per cached value than higher-precision representations.
ESTIMATE: The amount of VRAM saved in a complete workload depends on the model architecture, context configuration, backend and other allocations.
RECOMMENDATION: First eliminate context you do not need. Consider cache quantization when the workload genuinely requires long sequences and memory remains the limiting resource.
How to find your practical context setting
You can determine a useful context size without guessing.
1. Measure a representative workload
Do not begin with the model’s maximum. Look at the prompts your application actually produces.
For chat, include the system prompt and realistic history. For RAG, include retrieved chunks. For coding, include the source context normally sent to the model.
2. Leave room for output
The input is not necessarily the entire sequence budget. Your application may also need room for the model to generate a substantial answer.
A configuration that accepts the prompt but leaves almost no practical generation room is not useful.
3. Test memory at realistic context
Load the model with the intended runtime configuration and observe actual memory allocation rather than estimating everything from GGUF file size.
If the setup leaves almost no VRAM headroom, test whether longer sequences or other runtime allocations push it into an undesirable memory configuration.
4. Measure time to first token
Compare a short prompt with a representative long one.
If long inputs create unacceptable latency before generation starts, additional context capacity will not fix the problem. You may need to reduce the amount of input being processed.
5. Test concurrency separately
If the machine is a server, repeat the test with the expected number of simultaneous requests.
Single-user success does not prove that the same context configuration is appropriate for several users.
6. Increase only when the workload requires it
If prompts are being truncated or the application genuinely needs more source material at once, increase context and repeat the memory and latency tests.
This produces a context setting based on observed requirements rather than a specification-sheet number.
Common context-window mistakes
Setting the maximum because it is available
A large advertised context window is a capability ceiling, not an instruction to allocate that amount for every local deployment.
Looking only at model-file size
The weights are not the complete inference memory budget. KV cache and compute allocations also matter.
Testing only with tiny prompts
A model that works perfectly with a one-line prompt may behave differently when processing the actual documents, code or chat history your application will use.
Keeping unlimited conversation history
Old messages consume context even when they are no longer relevant. History management can be more effective than simply increasing the context limit.
Retrieving too much text in RAG
Sending more chunks is not automatically better. Retrieval should select useful evidence rather than use the context window as bulk storage.
Ignoring server concurrency
A context configuration designed for one user can consume too much memory when multiple sequences are active.
When very long context does make sense
There are workloads where large context is genuinely useful.
Analyzing a long source document as a coherent whole, working with large sections of a codebase, examining long transcripts, or performing tasks that depend on relationships across distant parts of the input can justify a larger sequence.
In those cases, the additional memory and processing cost may be worthwhile.
But “the model supports it” is not itself a workload requirement.
The distinction matters particularly on local hardware, where VRAM and memory bandwidth are finite resources. Cloud APIs can hide much of the infrastructure behind a request price. On your own workstation, the cost appears directly as memory allocation, latency, reduced concurrency, or the need for different hardware.
A practical decision rule
Choose the smallest context configuration that comfortably handles your real workload, including the input, required generation space, and reasonable variation between requests.
Then test it on the hardware and runtime you will actually use.
If you regularly hit the limit, determine why before increasing it. A genuinely long document may justify more context. An assistant carrying months of irrelevant conversation history probably needs better history management. A RAG pipeline filling the prompt with weak retrieval results needs better retrieval. A multi-user server may need stricter context limits rather than larger ones.
Long context is valuable when the model needs access to more relevant information at the same time. It is wasteful when it simply provides unused capacity or allows an application to avoid managing its inputs.
For local AI, that distinction translates directly into VRAM, latency and the number of useful workloads your machine can run.