context length
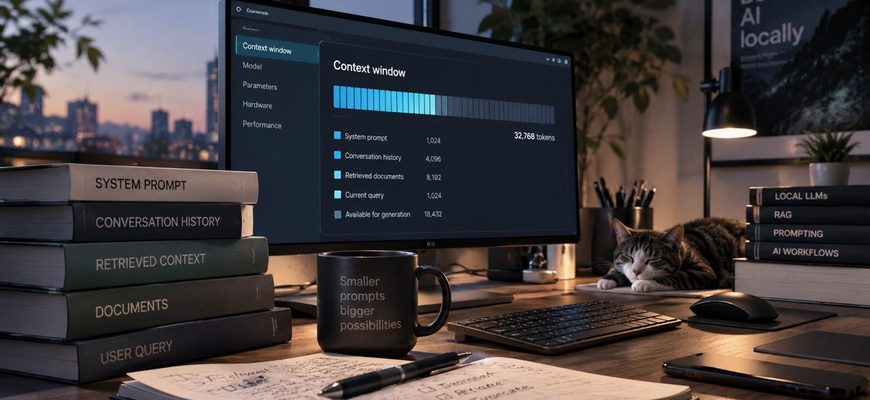
A local model may advertise a 32K, 64K, 128K, or even larger context window. That does not mean you should configure your local runtime to use the maximum.
Local AI, Local LLMs, GPU hardware, inference, RAG and AI server infrastructure explained clearly.