prompt processing
A local LLM does not have one meaningful “tokens per second” number. Before it can write the first token of an answer, it has to process the tokens already in the prompt.
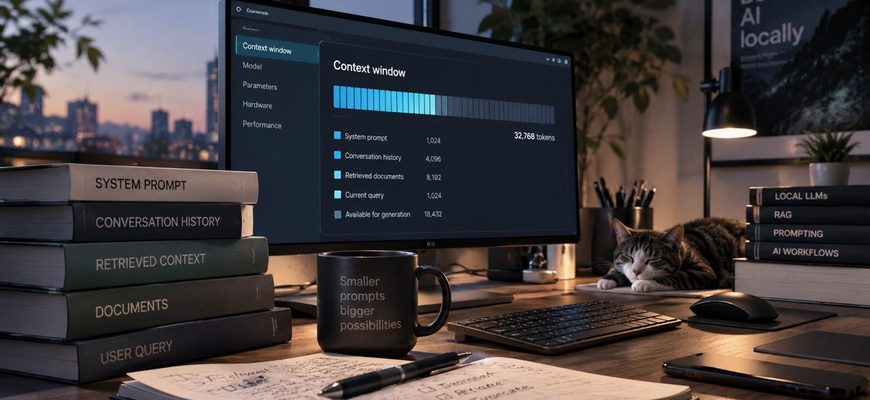
A local model may advertise a 32K, 64K, 128K, or even larger context window. That does not mean you should configure your local runtime to use the maximum.