context window
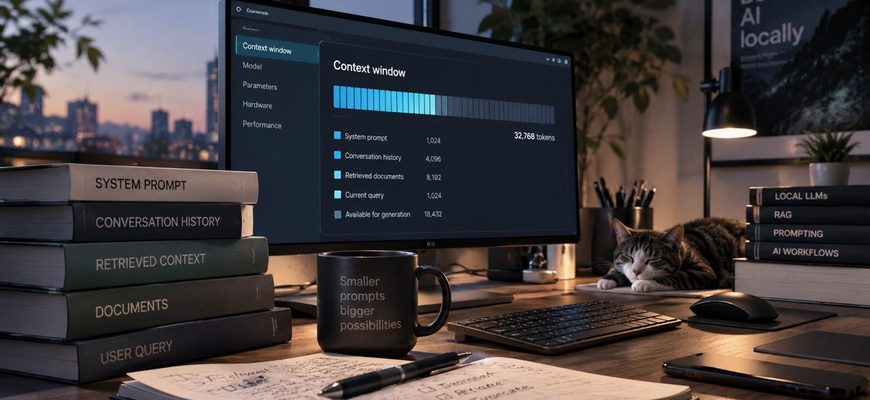
A local model may advertise a 32K, 64K, 128K, or even larger context window. That does not mean you should configure your local runtime to use the maximum.
A local LLM can fit comfortably into your GPU at an 8,000-token context and run out of memory when you increase that context several times over.