A local LLM can fit comfortably into your GPU at an 8,000-token context and run out of memory when you increase that context several times over. The model has not become larger. Its weights have not changed. What changed is the amount of conversation the inference engine must keep available while generating the next token.
This is why VRAM estimates based only on a GGUF file size or parameter count are incomplete. During inference, memory is also required for the model’s working state. One of the most important parts of that state is the key-value cache, usually called the KV cache.
For anyone running an LLM locally, the practical consequence is simple: a model fitting into VRAM does not guarantee that every context length advertised by that model will fit as well.
- Model weights are only the starting point
- What the KV cache actually stores
- Why context length increases VRAM usage
- Context length and KV cache are not the same thing
- Why two models of similar size can need different cache memory
- Why a 4-bit model can still consume substantial VRAM
- Why long prompts and long outputs both matter
- Why the maximum context is rarely the best target
- Memory
- Prompt processing
- Useful information density
- Long context can change a GPU-offloading strategy
- Context becomes even more expensive with concurrent users
- How to choose a practical context size
- Common mistakes when estimating VRAM
- Looking only at the model file
- Assuming advertised context is free
- Assuming all models have the same KV-cache cost
- Assuming weight quantization solves all memory problems
- Testing only short prompts
- What to change when you run out of VRAM
- The practical VRAM rule
Model weights are only the starting point
When loading a local language model, its weights usually account for the largest obvious block of memory. Quantization can reduce that requirement substantially, which is why a quantized model can run on hardware that could not hold the same weights at higher precision.
But inference needs more than weights.
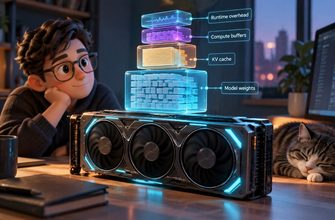
A simplified memory budget looks like this:
memory ≈ model weights + KV cache + runtime buffers + temporary allocations + other overhead
This is deliberately not a formula for predicting an exact number. Runtime implementation, GPU backend, model architecture, cache precision, batch configuration and other settings affect actual memory use.
It is nevertheless a useful way to think about local inference. Quantizing the weights attacks one part of the budget. Reducing context length attacks another.
That distinction becomes important when VRAM is tight.
What the KV cache actually stores
An autoregressive LLM generates text one token at a time. To produce a new token, the transformer needs information from tokens that came before it.
Without caching, the model would repeatedly calculate attention-related information for previous tokens during generation. Instead, inference systems generally preserve key and value states produced by attention layers and reuse them when processing subsequent tokens.
That stored state is the KV cache.
The practical effect is faster autoregressive generation at the cost of memory. Hugging Face’s Transformers documentation describes the cache as storing key-value calculations so they can be reused rather than recomputed for each prediction.
Imagine beginning a conversation with:
User: Summarize this document.
The model processes the prompt and stores the relevant cached states. If you then provide a long document, those additional tokens add more state. When the model writes its response, generated tokens become part of the active sequence too.
Continue chatting without discarding earlier context and there is progressively more history for the runtime to manage.
For conventional full-attention transformer layers using a dynamically growing cache, longer active sequences therefore mean a larger KV cache.
Why context length increases VRAM usage
The context window describes how many tokens a model can consider within its active sequence, subject to the model and runtime configuration.
It is easy to interpret a specification such as a large context window as a promise that using the full window is practical on any machine capable of loading the model. It is not.
There are two separate questions:
- Can the model architecture support this context?
- Can your hardware and runtime afford it?
The first is a model capability question. The second is a resource question.
For a conventional KV cache, memory requirements depend on factors including the number of cached tokens, number of relevant layers, the model’s attention architecture, dimensions of the key and value states, cache data type and number of simultaneous sequences.
As a first-order mental model, increasing the number of cached tokens increases KV-cache storage approximately in proportion to the active sequence length for ordinary full-attention layers.
That does not mean total inference memory grows according to one universal ratio. Model architectures differ, and newer attention designs can change cache behavior substantially.
Context length and KV cache are not the same thing
Another useful distinction is between configured capacity and currently occupied context.
Some runtimes can use dynamically growing cache structures. Hugging Face Transformers, for example, documents a DynamicCache that grows as generation progresses.
A static cache works differently. It can reserve storage based on a predefined maximum cache length. That may use more memory up front even when the current prompt is short, in exchange for properties useful to particular execution strategies.
This means two programs running the same model with the same nominal maximum context can report different memory behavior.
When comparing VRAM measurements, ask what was actually configured and used:
- Was the cache allocated dynamically or statically?
- How many tokens were actually in the active sequence?
- What precision was used for the cache?
- Was the KV cache on the GPU or partially elsewhere?
- Was one sequence running, or several?
Without those details, a statement such as “this model uses 10 GB of VRAM” is incomplete.
Why two models of similar size can need different cache memory
Parameter count alone does not determine KV-cache size.
Two models with roughly similar weight sizes can use different attention architectures. One important difference is how key and value heads are organized.
Traditional multi-head attention can maintain separate key and value states for each attention head. Architectures using grouped-query attention or multi-query attention can share key/value information across groups of query heads, reducing the amount of KV state that must be stored.
Other architectures use sliding-window, chunked or specialized attention mechanisms that can change how cache growth behaves.
Hugging Face notes, for example, that its dynamic cache stops growing for layers using sliding-window or chunked attention once those layers reach their configured window or chunk size.
So this rule is useful:
Do not estimate long-context memory from parameter count alone.
The model’s attention architecture matters.
Why a 4-bit model can still consume substantial VRAM
Weight quantization sometimes creates a misleading expectation.
Suppose you download a heavily quantized GGUF model because its weights fit comfortably within your available memory. It is tempting to assume that everything involved in inference is now operating at that same bit depth.
That is not necessarily true.
Weight quantization and KV-cache precision are separate decisions.
A runtime can store model weights in a low-bit quantized representation while keeping the KV cache in a different format. As the context grows, the cache can therefore become an increasingly meaningful part of the total memory footprint even though the model weights themselves remain unchanged.
llama.cpp, for example, exposes separate configuration for the data types used by key and value cache storage. Its implementation allocates key and value tensors according to the selected cache types and the model’s attention dimensions.
The lesson is not that one cache format is universally correct. Lower-precision cache formats can reduce memory requirements, but support and quality implications depend on the runtime, model and configuration.
The important point is that model quantization does not automatically define KV-cache precision.
Why long prompts and long outputs both matter
Context is not just the text you paste into the model.
The active sequence can include a system prompt, conversation history, retrieved documents, tool results, your latest message and tokens the model has generated.
Consider a local assistant used to analyze documents. A simplified context might contain:
| Context component | Why it consumes context |
|---|---|
| System prompt | Instructions are included in the sequence |
| Conversation history | Previous turns may be sent again |
| Retrieved passages | RAG inserts relevant source material |
| Current question | The user’s new input adds tokens |
| Generated answer | New output extends the active sequence during generation |
A workflow with a short user question can therefore have a large context if the application quietly attaches extensive history or retrieved material.
This is especially relevant to RAG systems. Increasing the number or size of retrieved chunks may provide more source material, but it also consumes context and can increase inference memory requirements.
Why the maximum context is rarely the best target
If a model supports a very large context window, should you configure your local runtime to use all of it?
Usually, not by default.
Maximum context is a capability ceiling, not a recommended operating point.
There are several reasons to use only as much context as the task requires.
Memory
More cached tokens can require more memory. On a GPU with little headroom, that can determine whether the workload remains fully GPU-resident or runs at all under the chosen configuration.
Prompt processing
A long prompt must be processed before generation can proceed. Efficient attention implementations can reduce the memory traffic and intermediate-memory costs of attention, but processing more tokens still represents more work than processing fewer tokens.
Useful information density
A larger context window gives an application room to provide more information. It does not mean every additional token improves the answer.
Dumping entire document collections or months of chat history into a prompt can add irrelevant material. Good context management is therefore both a systems problem and an information-selection problem.
For local AI, the practical goal is generally not maximum context. It is enough relevant context for the task.
Long context can change a GPU-offloading strategy
The interaction between context and GPU offloading is particularly important on machines that cannot fit everything comfortably in VRAM.
Runtimes such as llama.cpp can place different parts of a workload on available compute devices according to configuration and backend capabilities. A setup may appear comfortable when tested with a short prompt because enough GPU memory remains for the working state.
Increase context substantially and that headroom can shrink.
The resulting behavior depends on the runtime and configuration. You may need to reduce the amount of model data placed on the GPU, reduce context capacity, change cache settings or accept a different memory/performance trade-off.
This is why a local-AI configuration should be tested with something resembling the real workload rather than a single short “Hello” prompt.
Context becomes even more expensive with concurrent users
A single-user desktop assistant is the simplest case. A local server introduces another variable: concurrency.
Each active sequence needs state associated with its context. Serving several long conversations at once can therefore create substantially different cache requirements from serving one conversation.
Modern inference engines use techniques such as paged KV caches to manage this memory more efficiently. Hugging Face’s continuous batching architecture, for example, documents a paged cache in which memory is divided into blocks allocated to requests as needed.
This can reduce problems such as fragmentation and improve utilization, but it does not make per-request state free.
For a local AI server, asking “How many users can this GPU serve?” therefore requires more information than the model size. Typical prompt length, output length, concurrency, cache representation and latency expectations all matter.
How to choose a practical context size
There is no universal context setting that is optimal for every local model and machine. A better approach is to work backward from the task.
- Start with the workload. A chat assistant, coding assistant, RAG system and long-document analyzer need different amounts of context.
- Measure real token usage. Do not assume every supported token must be available for every request.
- Leave memory headroom. Loading the model with only a tiny amount of free VRAM can make larger real-world requests problematic.
- Test realistic prompts. Include the system prompt, history, retrieved material and expected output length.
- Check runtime-specific cache options. Cache precision, offloading and allocation strategies can materially change memory behavior.
- Increase context when the workload justifies it. Do not treat the model’s maximum supported context as the default target.
For a personal chat assistant, a moderate context may be sufficient even when the model supports much more. A document-analysis workflow may genuinely need longer sequences. A RAG system may benefit more from improving retrieval than from continuously increasing the amount of retrieved text.
The correct context is therefore a workload decision, not simply a model specification.
Common mistakes when estimating VRAM
Looking only at the model file
A GGUF file fitting inside available memory does not prove that the entire inference workload will fit. The runtime still needs memory for cache and other allocations.
Assuming advertised context is free
A model supporting a large context window tells you about its capability. It does not tell you how much memory your particular runtime will require to use that capacity.
Assuming all models have the same KV-cache cost
Attention architecture, layer structure and cache representation matter. A simple “memory per token” figure from one model should not automatically be applied to another.
Assuming weight quantization solves all memory problems
Quantizing model weights can dramatically change the weight footprint. The KV cache is a separate part of the memory budget.
Testing only short prompts
A model that starts successfully is not necessarily configured successfully for the intended workload. Test the context lengths you expect to use.
What to change when you run out of VRAM
If a local model works at short context but fails or becomes impractical as context grows, replacing the GPU is not the only option.
Depending on the model and runtime, useful adjustments can include reducing the configured context, limiting conversation history, retrieving fewer or better-targeted RAG passages, changing KV-cache precision where supported, adjusting GPU offloading, or choosing a model whose attention architecture has more favorable cache characteristics for the workload.
These choices involve trade-offs. Reducing context can remove information the model needs. More aggressive cache compression can introduce its own quality or compatibility considerations. Moving work away from the GPU may reduce VRAM pressure but affect performance.
That is why the useful question is not “What is the largest context I can configure?”
It is “How much context does this task need, and what does that context cost on this machine?”
The practical VRAM rule
When sizing a local LLM, think about memory in two stages.
First, ask whether the model weights fit at the precision or quantization you intend to use. Then ask how much room remains for the context and the rest of the inference workload.
That second question becomes increasingly important as context windows grow.
A smaller quantized model with enough memory headroom for the context you actually need can be more useful than a larger model squeezed into VRAM so tightly that realistic prompts no longer fit comfortably.
The model file tells you what you can load. The full inference memory budget tells you what you can actually use.