GPU memory
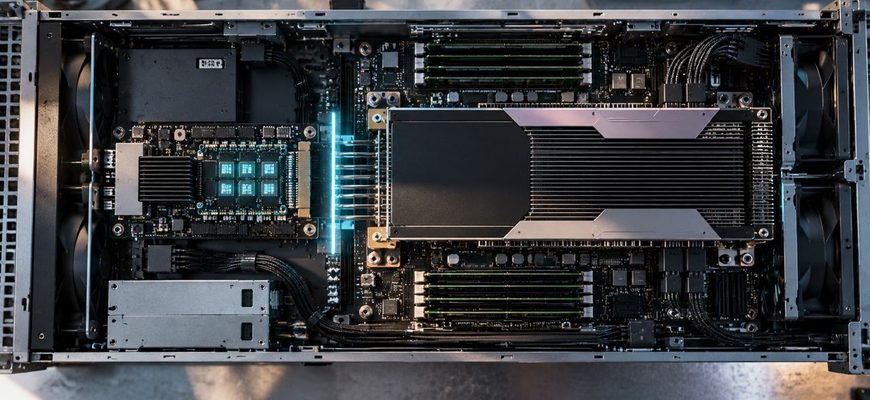
A large language model can have a powerful GPU almost to itself and still produce a single conversation one token at a time. The accelerator finishes one
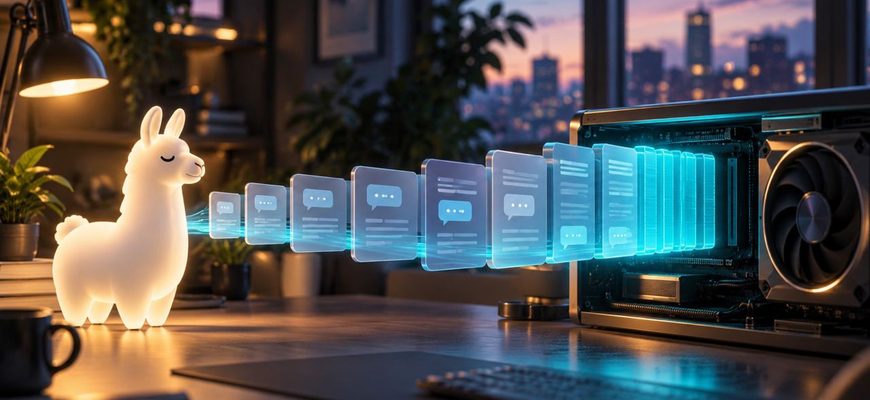
A local LLM can fit comfortably into your GPU at an 8,000-token context and run out of memory when you increase that context several times over.