The shared LLM server has not crashed. GPU utilization remains high, requests are still finishing, and the monitoring dashboard shows no conventional out-of-memory failure. Yet one conversation suddenly pauses halfway through its answer.
A few seconds later, the stream resumes. Its next token took far longer than the ones before it, while another request appeared to continue normally. The interruption may look like random congestion, but it can mark a specific transition inside the inference engine: the KV-cache pool no longer has enough free space for every active sequence.
The scheduler now has to protect the server. It can delay new work, reclaim reusable cache blocks or preempt an active request so another can continue. In a recompute-based design, the interrupted request later returns to the GPU and rebuilds state the machine had already calculated.
- The KV cache is a finite memory pool that grows as active sequences receive more tokens.
- Evicting an inactive reusable prefix is different from preempting a request that is still generating.
- Preemption can avoid a server-level failure while producing long inter-token gaps and extra computation.
- High GPU utilization does not reveal whether the accelerator is doing new work or rebuilding discarded state.
- Cache usage, preemption count, queue time and tail latency should be measured together.
- The model fits, but the active workload no longer does
- Cache eviction and request preemption are not the same event
- Recomputation turns memory pressure into repeated GPU work
- Why the symptom can look random
- GPU utilization cannot tell you whether work is useful
- Prefix caching makes the memory decision more interesting
- How to confirm that cache pressure is the bottleneck
- Reproduce the problem with a length distribution
- Increase concurrency gradually
- Separate queueing from interrupted generation
- Check logs and engine metrics
- Change one capacity variable
- What can actually help
- The cache limit appears before the crash
The model fits, but the active workload no longer does
Model weights are usually the most visible resident in GPU memory. They are also relatively stable: once loaded, the same weights serve many requests.
The KV cache behaves differently. Each active sequence accumulates attention state for tokens that have already been processed. Longer prompts begin with more state, and every generated token extends the sequence further.
Concurrency multiplies that growth across requests. One conversation may be small, but several long-running conversations can collectively consume the cache pool that the serving engine reserved from available VRAM.
This is why a server can load its model successfully and still encounter memory pressure later. “The model fits in VRAM” describes only one part of a changing memory budget.
| Memory resident | How it behaves | What increases pressure | Operational consequence |
|---|---|---|---|
| Model weights | Mostly fixed after the model is loaded. | Larger models, higher precision or additional resident models. | Determines how much VRAM remains for serving state. |
| Active KV state | Grows as prompts are processed and responses generate. | Longer sequences and more concurrent requests. | Can force admission delays or request preemption. |
| Reusable prefix state | May remain after computation so later requests can reuse it. | More cached prefixes and longer reusable regions. | Can improve future TTFT but competes for finite cache capacity. |
| Runtime allocations | Depends on the engine, kernels and execution configuration. | Larger batches, temporary buffers and additional features. | Reduces the practical headroom available to the cache. |
The number of users one GPU can serve therefore depends partly on how much active state those users create. Registered users are not the relevant unit. Simultaneous tokens occupying memory are.
Two EventsCache eviction and request preemption are not the same event
The word “eviction” is often used loosely, which can hide an important distinction.
A completed request may have left reusable prefix state in the cache. If nobody is actively depending on a reusable block, the engine can reclaim it when new work needs memory. The immediate cost is losing a possible future cache hit.
An active request is different. Its KV state is part of ongoing generation. If the scheduler removes that request from active execution to free memory, the request has been preempted.
What happens next depends on the serving engine and configuration. State may be retained elsewhere, transferred through another memory tier or discarded and recomputed when the request runs again.
“The cache evicted something” does not reveal the user impact. Reclaiming an idle reusable prefix may affect only a later request. Preempting an active decode can affect the conversation currently visible on screen. Logs and metrics must distinguish the two.
| Event | State affected | Immediate effect | Possible later cost |
|---|---|---|---|
| Reusable-prefix eviction | Cached state not required by an active request. | Memory becomes available for current work. | A future matching prompt may require fresh prefill. |
| Admission delay | A waiting request has not received enough cache space. | The request remains queued. | TTFT and tail queue latency increase. |
| Active-request preemption | State belonging to a request that has already started. | The request stops receiving normal execution slots. | Streaming pauses and end-to-end latency increases. |
| Recomputation | Discarded state is reconstructed from retained tokens. | The GPU repeats earlier model work. | Useful throughput can fall even while utilization remains high. |
| Host offload and restore | Cache state moves between accelerator and host memory. | GPU capacity is freed without immediately discarding the state. | Transfers add latency and depend on the host link and implementation. |
Recomputation turns memory pressure into repeated GPU work
Consider a request that has processed a long prompt and generated part of an answer. Its cache state records the attention history needed to continue efficiently.
If that request is preempted and its relevant state is discarded, the server still has the original token sequence. It can schedule the request again and process those tokens as a new prefill until the required state has been reconstructed.
This makes the system resilient: the request can eventually continue instead of forcing the entire engine to fail. But the recovery is not free. Tokens that had already passed through the model now pass through it again.
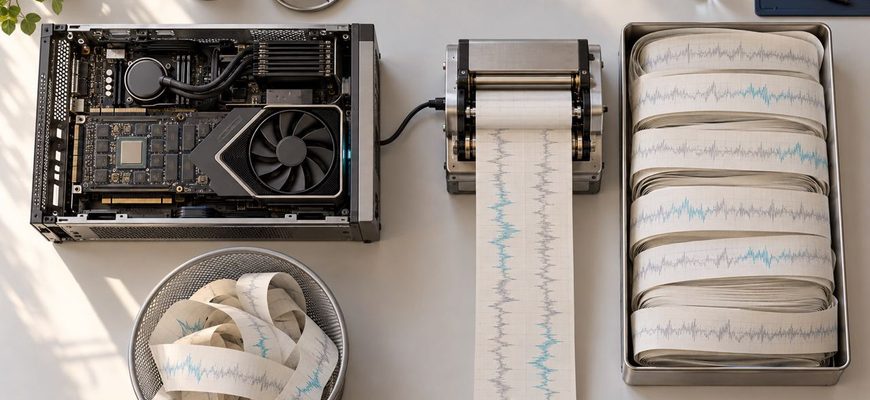
Recomputation converts a VRAM-capacity problem into additional accelerator work. GPU memory is released, but the machine later reads model weights and executes layers again to recreate state that previously occupied the cache. The server avoided an allocation failure by spending time and electricity repeating computation.
Why the symptom can look random
Cache pressure is driven by the live mixture of sequence lengths, arrival times and generation durations. Two requests with identical prompts may experience different outcomes because they entered different populations of active work.
A short request can arrive when the pool has comfortable headroom and finish normally. The same request can arrive later, behind several document-heavy conversations, and wait while the scheduler protects active work.
The longest request is not necessarily the one users notice failing. Scheduling policy decides which work waits or is preempted. What looks like random latency may be the visible result of a deterministic policy operating on a rapidly changing memory pool.
Continuous batching makes the active batch dynamic, but it does not make VRAM dynamic. Finished sequences can release blocks and waiting requests can enter; until that happens, the cache pool remains finite.
MeasurementGPU utilization cannot tell you whether work is useful
A saturated accelerator can look reassuring. It means the GPU is receiving work. It does not prove that every operation is advancing a response for the first time.
During repeated preemption, some of that activity may be reconstructing state the server discarded earlier. Aggregate utilization can remain high while queue time, inter-token latency and end-to-end latency deteriorate.
Correlate those measurements on the same timeline. A preemption counter without latency data does not show user impact. A latency spike without cache pressure does not prove memory caused it.
The useful pattern is cache usage approaching its practical limit, followed by preemption or queue growth and a simultaneous increase in tail latency. Prompt and generation lengths help explain which requests created the pressure.
- KV-cache usage over time, not only one current value.
- Running and waiting request counts.
- Cumulative and interval preemption counts.
- Prompt and generated-token distributions.
- Queue time, TTFT, inter-token latency and end-to-end latency.
- Prefix-cache queries and hits, kept separate from active-request preemption.
- GPU utilization and useful token throughput on the same timeline.
Prefix caching makes the memory decision more interesting
Prefix caching keeps previously computed state available so a later matching request can avoid repeated prefill work. That state is valuable, but its value depends on reuse.
When new active work needs memory, the engine may reclaim reusable blocks. A prefix that remains warm under light traffic may disappear quickly when concurrency and output lengths increase.
This is not necessarily a failure. Active generation normally deserves capacity before a speculative future cache hit. The trade-off appears later, when another request arrives with the same prefix and discovers that the reusable state is gone.
A cache can therefore protect current work while sacrificing future TTFT. If active requests themselves are preempted, the trade becomes more severe: current latency is affected and previous computation may be repeated.
DiagnosisHow to confirm that cache pressure is the bottleneck
Reproduce the problem with a length distribution
Do not test only identical short prompts. Use the application’s real mixture of input and output lengths. Cache pressure depends on the simultaneous population of active tokens.
Increase concurrency gradually
At each level, record cache use, preemptions, queue time, TTFT, ITL and throughput. The objective is to locate the point where additional traffic stops providing useful throughput and begins producing disproportionate latency.
Separate queueing from interrupted generation
A request that has not started affects TTFT. A request that was already streaming and then pauses affects ITL and end-to-end latency. Those symptoms identify different parts of the scheduler’s response.
Check logs and engine metrics
Use explicit preemption telemetry where the runtime provides it. Do not infer recomputation from GPU utilization alone.
Change one capacity variable
Reduce maximum concurrent sequences or shorten the test workload while keeping the model and hardware fixed. If preemptions disappear and tail latency stabilizes, the result supports a cache-capacity diagnosis.
Paged cache allocation reduces waste caused by reserving one large contiguous memory region for every sequence. It does not make memory unlimited. Once the available blocks are committed, the scheduler still needs an admission, eviction, offload or preemption policy.
What can actually help
The correct intervention depends on which event is occurring.
| Observation | Likely pressure | Direction to test | Trade-off |
|---|---|---|---|
| Frequent active-request preemption | Too much simultaneous sequence state for the available pool. | Reduce concurrent sequences or increase cache headroom. | Lower peak concurrency or less memory for other uses. |
| Long prompts dominate cache growth | Input and subsequent active state are larger than the tested workload assumed. | Reduce unnecessary context and tighten retrieval. | Less material is available to each request. |
| Long generations retain blocks | Requests remain active and hold state for longer. | Use realistic output limits and workload-specific routing. | Limits may constrain legitimate long-form output. |
| Prefix hits vanish under load | Reusable state is evicted before it can be requested again. | Inspect cache locality, retention policy or host offload support. | Retaining old state can reduce room for active work. |
| One model leaves little cache capacity | Weights consume most accelerator memory. | Test a smaller model, lower weight precision or a different parallel layout. | Quality, synchronization or architecture may change. |
More VRAM can help, but it should not be the first explanation offered without measurement. A workload with unbounded conversation history can consume additional capacity on a larger card and eventually reproduce the same behavior.
Likewise, increasing the fraction of memory assigned to the cache is not free. The runtime and other GPU consumers still need headroom. A setting that works on an otherwise idle card may fail when the display, another process or a changed engine configuration allocates memory.
A useful first-party test would locate the point where cache growth begins causing active-request preemption and repeated computation on one fixed inference server.
The cache limit appears before the crash
An out-of-memory error is easy to recognize. Cache saturation can be more deceptive because the serving engine may keep operating by delaying, evicting and recomputing.
That resilience is useful, but it moves the failure from a clean allocation error into user-visible latency. The machine remains busy and the request eventually finishes, while part of the GPU’s effort is spent reconstructing its own discarded past.
Do not wait for the server to crash before declaring it full. For a shared LLM service, the practical cache limit is the point where useful state stops remaining resident long enough for requests to meet their latency target.