LLM Serving
The shared LLM server has not crashed. GPU utilization remains high, requests are still finishing, and the monitoring dashboard shows no conventional out-of-memory failure.
Three people are using the same local AI server. Two answers are already streaming at a comfortable pace. Then a third user pastes a long document and presses Send.
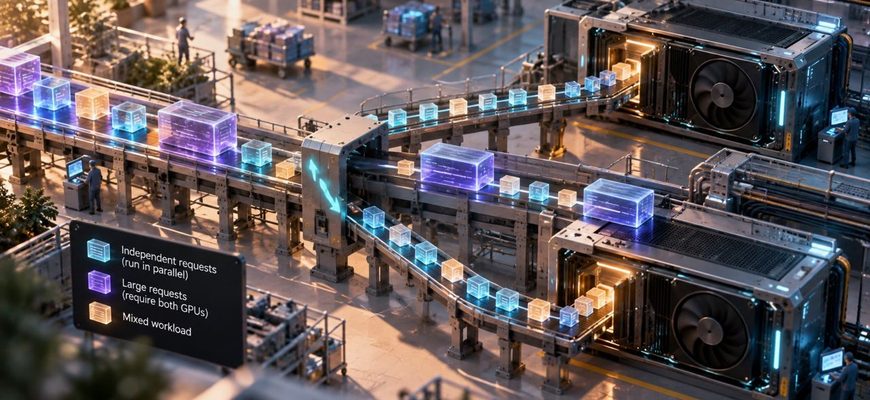
There is an appealingly simple upgrade path for a busy local AI server: install another GPU. Twice the accelerators should mean something close to twice
A local AI server can feel almost instantaneous when one person is using it. Add a second conversation and it may still feel fine. Add several people with