vLLM
The shared LLM server has not crashed. GPU utilization remains high, requests are still finishing, and the monitoring dashboard shows no conventional out-of-memory failure.
A large language model can have a powerful GPU almost to itself and still produce a single conversation one token at a time. The accelerator finishes one
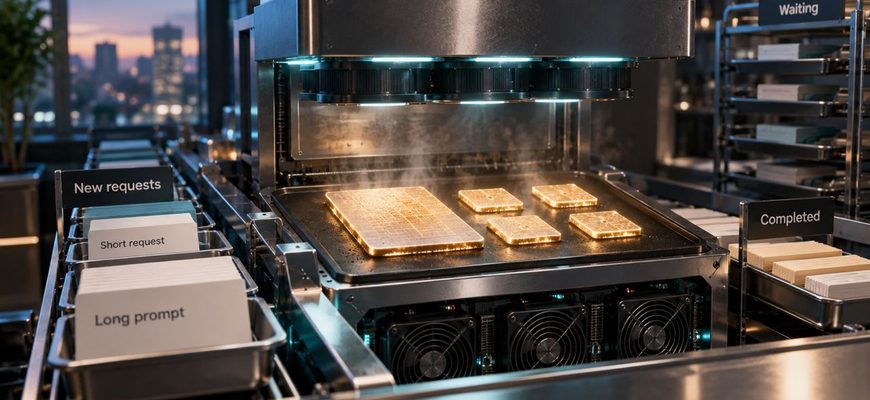
Four people are talking to the same local LLM. One asks a short question and gets an answer in seconds. Another requests a long explanation.