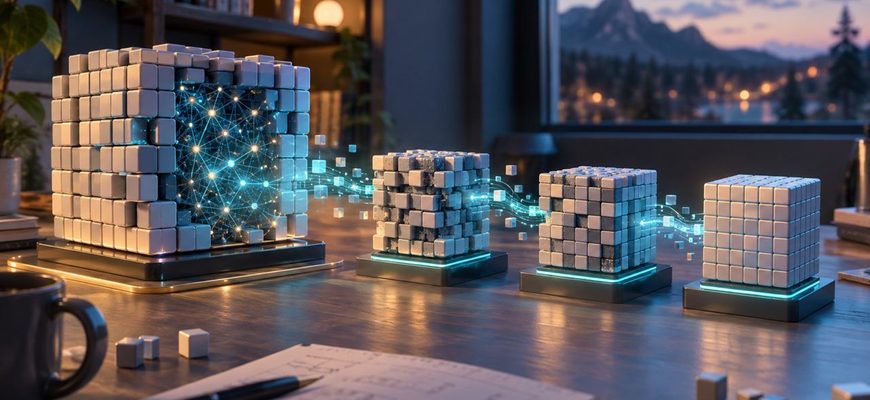
A 14 GB model file does not mean you need exactly 14 GB of memory to run it. And a model described as “8B” does not have one fixed memory requirement. One of the main reasons is quantization: the same model can be distributed at several numerical precisions, producing dramatically different file sizes and memory requirements.
If you download GGUF models for llama.cpp or another compatible local runtime, you will encounter names such as Q4_K_M, Q5_K_M, Q6_K and Q8_0. They are not different model sizes in the usual parameter-count sense. They are different ways of representing approximately the same trained weights.
The practical choice is usually straightforward: use enough precision to preserve the quality you need, but not so much that you waste memory that could instead let you run a larger model, a longer context, or more of the model on the GPU.
- What LLM quantization actually does
- Why quantization matters so much for local AI
- Q4, Q5 and Q8 do not mean exactly 4, 5 and 8 bits per model parameter
- What the common GGUF quantization names mean
- Q4_K_M: the practical starting point
- Q5_K_M: spend more memory for more precision
- Q8_0: high precision, but not automatically the best choice
- How large is the difference in practice?
- Model file size is not total memory usage
- Does lower quantization make inference faster?
- When should you use Q4?
- When should you use Q5 or Q6?
- When does Q8 make sense?
- Do not compare quantizations from different models as if they were one variable
- Re-quantizing a quantized model is a bad shortcut
- How to choose a quantization for your computer
- A practical rule of thumb
- The important trade-off is not Q4 versus Q8 in isolation
What LLM quantization actually does
An LLM contains billions of numerical parameters, usually called weights. Those numbers must be stored somewhere and read repeatedly during inference.
Higher-precision representations require more bits per value. For example, a 16-bit representation needs roughly twice the raw weight storage of an 8-bit representation before accounting for quantization metadata and other implementation details.
Quantization converts model weights into a lower-precision representation. Instead of retaining every weight at its original precision, the quantized model stores a compressed approximation.
FACT: Quantization reduces the memory required for model weights by representing them at lower precision. Modern frameworks support multiple approaches, including 8-bit, 4-bit and still lower-bit representations.
The trade-off is information loss. Quantization is normally lossy: after converting a model to a lower precision, its stored weights no longer reproduce every original value exactly.
The important question is therefore not whether quantization changes the model. It does. The useful question is whether the resulting difference matters for your workload.
Why quantization matters so much for local AI
For local inference, memory is often the first hard constraint.
Consider a model with eight billion parameters. Storing every parameter at 16 bits would require roughly 16 GB just for the raw weights:
8 billion parameters × 2 bytes ≈ 16 GB
That is only a simplified weight calculation. Actual model files and runtime memory usage differ because architectures contain different tensors and runtimes need memory beyond the weights.
At roughly four bits per weight, however, the theoretical raw weight payload is closer to:
8 billion parameters × 0.5 bytes ≈ 4 GB
Again, an actual Q4 file will be larger than this simplistic calculation because quantized formats need scales, metadata and sometimes tensors stored at different precisions.
Still, the magnitude of the difference explains why quantization is fundamental to local AI. It can turn a model that does not fit into available RAM or VRAM into one that does.
Q4, Q5 and Q8 do not mean exactly 4, 5 and 8 bits per model parameter
This is one of the most useful misconceptions to clear up.
The number in a quantization name describes the central quantization scheme, but the final model does not necessarily use exactly that many bits for every parameter. Quantization formats store additional scaling information, and some schemes use different representations for different tensors.
llama.cpp’s K-quant formats illustrate this clearly. Its tensor encoding documentation describes Q4_K as effectively 4.5 bits per weight and Q5_K as 5.5 bits per weight at the tensor encoding level because the blocks include additional scale and minimum information.
This is why estimating a GGUF file by simply multiplying the parameter count by four or five bits will not give an exact result.
What the common GGUF quantization names mean
For someone downloading a model rather than developing a new quantization algorithm, the most useful distinctions are practical.
| Quantization | Relative size | Quality retention | Typical reason to choose it |
|---|---|---|---|
Q4_K_M | Low | Good | Strong memory/quality compromise |
Q5_K_M | Medium | Higher | More quality when memory allows |
Q6_K | Higher | Very high | Preserve more precision without going to Q8 |
Q8_0 | High | Very high | Memory is plentiful and minimizing quantization loss matters |
| FP16/BF16 | Very high | Reference-like | Quantization savings are unnecessary or the workflow requires higher precision |
These descriptions are deliberately relative. There is no universal number saying that Q4 loses a particular percentage of model quality. The effect depends on the model architecture, quantization method, task and evaluation.
Q4_K_M: the practical starting point
For many GGUF models used with llama.cpp-compatible runtimes, Q4_K_M is a useful place to start.
It compresses the weights aggressively enough to produce a substantial memory saving while retaining considerably more practical usefulness than the name “4-bit” might suggest.
The K identifies the K-quant family used by llama.cpp. The M variant is a mixed quantization: the resulting file is not simply every tensor encoded identically at four bits.
RECOMMENDATION: If you do not yet know which GGUF quantization to download, start by checking whether Q4_K_M allows the model to fit comfortably in your available memory. It is a useful baseline, not a universal optimum.
The key word is comfortably. Filling every last gigabyte with model weights can leave too little space for context, runtime buffers and other processes.
Q5_K_M: spend more memory for more precision
Q5_K_M moves the balance toward quality retention. It consumes more storage and memory than Q4_K_M but introduces less quantization error.
That makes Q5 attractive when the same model already fits on your hardware and moving up one quantization level does not create a new bottleneck.
Suppose Q4 leaves several gigabytes of unused VRAM while Q5 also fits together with your intended context. In that situation, there may be little reason to choose the more aggressive compression unless Q4 performs better on your particular runtime or you need the spare memory for another workload.
But there is another choice worth considering: a larger model at Q4 versus a smaller model at Q5 or Q8.
Those are not equivalent decisions. Increasing precision preserves the existing model more faithfully. Increasing parameter count gives you a different model with potentially greater capability but also different speed and memory characteristics.
In many local deployments, allocating memory to a larger model can be more useful than allocating the same memory to a very high-precision version of a smaller model. That is a workload-dependent recommendation, not a guarantee.
Q8_0: high precision, but not automatically the best choice
Q8_0 uses an 8-bit block quantization scheme. llama.cpp describes it as storing blocks of 32 values with a scale plus signed 8-bit quantized values.
The resulting files are much larger than Q4 versions. The benefit is much smaller quantization error.
That does not make Q8 automatically “better” for a local setup.
If Q8 forces part of a model out of GPU memory while Q5 fits completely, the lower-precision version may produce a much more attractive overall setup. Depending on the runtime and hardware, partial CPU execution or GPU offloading can materially change inference performance.
Likewise, using Q8 for an 8B model when the same machine could run a capable 14B model at Q4 presents a different trade-off than simply comparing Q4 and Q8 versions of one model.
RECOMMENDATION: Choose Q8 because you have a reason to prioritize precision and enough memory to do so—not simply because eight is larger than four.
How large is the difference in practice?
The llama.cpp quantization tool provides a useful concrete example for Llama 3 8B. Its current quantization definitions list approximately these model sizes:
| Format | Example size for Llama 3 8B |
|---|---|
Q4_K_S | 4.37 GB |
Q4_K_M | 4.58 GB |
Q5_K_S | 5.21 GB |
Q5_K_M | 5.33 GB |
Q6_K | 6.14 GB |
Q8_0 | 7.96 GB |
FACT: These figures are examples for that model and those llama.cpp quantization types. They should not be treated as universal file sizes for every 8B model.
The practical lesson is more important than the exact numbers: moving from Q4_K_M to Q8_0 can consume several additional gigabytes without changing the model’s parameter count.
Model file size is not total memory usage
A common mistake is to see a 5.3 GB GGUF file and conclude that 6 GB of VRAM must be enough.
The model weights are only part of inference memory.
The runtime also needs memory for data such as the KV cache, compute buffers and its own overhead. Context length can be especially important because the KV cache grows as more tokens are retained, although the exact relationship depends on the model architecture, cache data type and runtime.
So this reasoning is unsafe:
5.3 GB model + 6 GB VRAM = it fits
A better model is:
weights + KV cache + compute/runtime overhead + safety margin
ESTIMATE: The amount of headroom you need cannot be specified with one universal number. It depends on the model, context, runtime, GPU backend, KV-cache configuration and how much of the model is offloaded.
Does lower quantization make inference faster?
Sometimes, but do not assume that fewer bits translate directly into proportionally more tokens per second.
Quantized weights reduce the amount of model data that has to be stored and moved. That can be particularly valuable when inference is limited by memory bandwidth.
But actual speed depends on whether your runtime and hardware have efficient kernels for that quantization type. CPU architecture, GPU backend, memory bandwidth, offloading configuration and prompt-processing workload all matter.
A Q4 model therefore is not universally “twice as fast” as Q8 simply because its weights occupy roughly half as many bits.
RECOMMENDATION: Treat quantization primarily as a memory-versus-quality decision. Measure performance on your actual runtime if inference speed is important.
When should you use Q4?
Q4 makes the most sense when memory capacity is an important constraint.
That includes machines where Q5 or Q8 would push weights out of available VRAM, systems using unified memory, CPU-only inference where RAM footprint matters, or cases where reducing model memory lets you run a larger model.
It is also a sensible default for experimenting with unfamiliar models. You can determine whether the model itself is useful before spending additional storage and memory on a higher-precision version.
More aggressive quantization below common Q4 formats can save still more memory, but the quality trade-off becomes increasingly important. Such formats can be valuable when fitting the model is otherwise impossible, but they should not automatically replace Q4 simply because they are smaller.
When should you use Q5 or Q6?
Move upward when you have memory to spare and want to reduce quantization loss without paying the full cost of Q8 or a 16-bit model.
This is particularly reasonable for a model you already know you will use regularly.
For example, if Q4_K_M leaves enough free VRAM that Q5_K_M also fits with your normal context window, Q5 becomes an attractive option. If Q6 also fits without forcing an undesirable offload configuration, it gives you another step toward higher precision.
There is no need to maximize precision merely because your hardware technically permits it. Free memory can be useful for longer contexts, parallel requests, embeddings, rerankers or other components of a local AI workflow.
When does Q8 make sense?
Q8 is useful when the model already fits easily, memory efficiency is not the primary concern, and you want a quantized GGUF with relatively little precision reduction.
It can also be useful as a local comparison point. If a task behaves unexpectedly at Q4, testing the same model at Q8 can help determine whether aggressive quantization is contributing to the problem.
But if Q8 prevents a model from fitting fully on the device you want to use, its theoretical quality advantage can come with an undesirable systems-level trade-off.
Do not compare quantizations from different models as if they were one variable
Model A Q4 versus Model B Q8 is primarily a comparison between two models, not a clean quantization test.
Model family, parameter count, training data, architecture, fine-tuning and intended workload can matter far more than a one- or two-bit difference in weight precision.
To understand the effect of quantization itself, compare different quantizations of the same model checkpoint.
That distinction is particularly important when deciding what to download. A smaller Q8 model is not automatically superior to a larger Q4 model, and the reverse is not guaranteed either.
Re-quantizing a quantized model is a bad shortcut
If you create your own GGUF files, start from a high-quality source rather than repeatedly compressing an already quantized model.
The llama.cpp quantization tool explicitly warns that requantizing previously quantized tensors can severely reduce quality compared with quantizing from 16-bit or 32-bit weights.
The principle is similar to repeatedly recompressing lossy media: information discarded during the first conversion cannot simply be recovered before the next one.
If you need a Q4 version and have access to the original high-precision weights, create the Q4 output from those weights rather than converting a Q8 or Q5 file into Q4.
How to choose a quantization for your computer
A practical decision process is more useful than trying to identify one universally superior format.
- Choose the model first. Decide which model family and parameter count make sense for your workload.
- Check your available memory. For GPU inference, look at usable VRAM or unified memory, not simply total system RAM.
- Reserve memory beyond the weights. Context and runtime overhead still need space.
- Start around Q4_K_M when memory is constrained. Check whether it fits with the context length you actually intend to use.
- Move to Q5 or Q6 if you have comfortable headroom. Higher precision can reduce quantization loss.
- Use Q8 when the extra memory cost does not compromise the rest of the setup.
- Test your real workload. Coding, structured extraction, long-context work and conversational use can expose different weaknesses.
A practical rule of thumb
| Your situation | Good starting point |
|---|---|
| Memory is tight | Q4_K_M |
| Q4 fits easily and you have spare memory | Q5_K_M |
| You want higher precision but still meaningful compression | Q6_K |
| Memory is plentiful and minimizing quantization loss matters | Q8_0 |
| Even Q4 does not fit | Consider a smaller model or a more aggressive quantization |
This is a starting framework, not a benchmark result. Model architecture and runtime support can change the best choice.
The important trade-off is not Q4 versus Q8 in isolation
For local AI, quantization is ultimately a resource-allocation decision.
Every additional gigabyte devoted to weight precision is a gigabyte that cannot simultaneously be used for something else. Depending on your setup, that memory could allow a larger model, a longer context, more GPU offloading or another model in the same workflow.
That is why Q4_K_M is often such a practical starting point: it compresses models enough to materially change what local hardware can run without immediately moving into the most aggressive quantization territory.
If Q5 or Q6 fits comfortably, using the additional precision is reasonable. If Q8 fits without compromising context or GPU residency, it gives you a high-precision quantized option.
But the goal is not to run the largest quantization number your machine can technically load. The goal is to choose the representation that leaves enough resources for the entire local AI workload while preserving the model quality that workload actually needs.