A local AI server can feel almost instantaneous when one person is using it. Add a second conversation and it may still feel fine. Add several people with long prompts, though, and something changes: the GPU can remain busy while individual users wait longer for the first token and watch responses arrive more slowly.
The tempting question is, “How many users can this GPU handle?” But a GPU does not come with a fixed user capacity. Ten short classification requests and ten 32,000-token conversations are not the same workload. Neither are ten users who arrive one after another and ten who press Send at the same moment.
The more useful question is: how many simultaneous requests can the system serve while staying inside its memory budget and latency target? Once you ask it that way, GPU capacity stops being a specification and becomes something you can measure.
- A GPU has no universal “users supported” number. Capacity depends on the workload and the latency users are expected to tolerate.
- Concurrency adds active sequences and KV-cache state, so VRAM matters beyond simply fitting the model weights.
- Continuous batching can improve aggregate GPU utilization and throughput, but higher throughput does not guarantee lower latency for every request.
- TTFT, inter-token latency, throughput and tail latency together reveal much more than a single tokens-per-second result.
- A defensible capacity number requires a defined prompt distribution, output distribution and concurrency level.
- One GPU can face two completely different workloads
- What actually changes when the second request arrives
- Continuous batching changes how much work the GPU can absorb
- Four metrics make “users per GPU” meaningful
- VRAM becomes a shared resource
- What happens when cache headroom starts disappearing
- Prompt length can hurt before generation even begins
- Shared prompt prefixes can change the result again
- Stop asking for the maximum number of users
- A capacity test should look like the application
- Why a second GPU is not automatically the next step
- The capacity number belongs to the workload, not the GPU box
One GPU can face two completely different workloads
Imagine two servers using the same GPU and the same model.
Server A handles short requests from an internal automation system. Prompts are small, outputs are brief, and requests arrive throughout the day. Server B powers a shared chat interface where people paste documents, maintain long conversations and sometimes generate hundreds of tokens.
The hardware specification is identical. The number of people it can serve comfortably is not.
| Workload change | What changes physically | Likely serving effect |
|---|---|---|
| Longer prompts | More input tokens must be processed and more sequence state may occupy KV-cache capacity. | More prefill work and potentially longer time to first token. |
| Longer outputs | The GPU performs more decode steps while active sequence state remains resident for longer. | Requests occupy serving capacity for longer. |
| More concurrent requests | More active sequences compete for compute and cache resources. | Aggregate throughput may rise while per-request latency worsens. |
| Shared prompt prefixes | A capable runtime may reuse cached prefix state. | Repeated prefill work can be reduced. |
| Tighter latency target | The serving system has less freedom to trade waiting time for batching efficiency. | Practical capacity may be lower. |
This is why “one GPU supports X users” is usually an incomplete statement. Without the workload and a service-level target, the number tells you very little.
What actually changes when the second request arrives
For a single conversation, the inference runtime processes the prompt and then repeatedly generates new tokens. During generation, attention-related state from previous tokens is retained in the KV cache so the model does not need to recompute the entire sequence from scratch for every next token.
With several active conversations, the runtime has several sequences to manage at once. One may be processing a long prompt, another may be decoding its 200th output token, while a third has just arrived.
Concurrency is not merely several browser tabs talking to the same API. At the accelerator, it becomes multiple token sequences competing for matrix-compute time, temporary buffers and a finite pool of GPU memory used for active inference state.
Continuous batching changes how much work the GPU can absorb
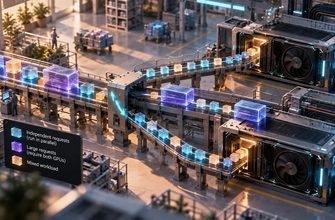
Traditional static batching groups requests and processes the group together. That is awkward for text generation because sequences rarely finish at exactly the same time. A short answer may complete while another sequence in the same group keeps generating.
Continuous batching makes the batch dynamic. As sequences finish, the serving engine can admit new work rather than waiting for every sequence in an original batch to complete.
The objective is straightforward: keep useful work flowing through the accelerator instead of leaving capacity stranded behind requests with different sequence lengths.
But better utilization does not automatically mean a better experience for every user.
A serving configuration can increase total tokens processed per second while making an individual request wait longer. Capacity planning therefore needs two perspectives at once: how much work the GPU completes and what each user experiences while it does so.
Four metrics make “users per GPU” meaningful
Once several requests compete for the same accelerator, a single throughput number is no longer enough. The server needs to be measured from both the machine’s perspective and the user’s.
A single-user tokens-per-second benchmark still tells you something useful about decode performance. It does not tell you how the same server behaves when requests queue, long prefills enter the scheduler or the KV-cache pool becomes crowded.
VRAM becomes a shared resource
Model weights are the obvious fixed resident in GPU memory, but they are not the whole memory budget. Active inference also needs cache space, runtime buffers and temporary allocations.
That becomes more visible under concurrency. Longer active sequences require more state, and several simultaneous sequences can consume cache capacity that a single-user test never approaches.
This is why context length and concurrency are connected. A server that handles many short conversations may struggle with a much smaller number of long ones.
Our guide to context windows and VRAM explains why model weights alone are not enough when estimating memory requirements. Multi-user serving extends the same problem across several active sequences.
Paged KV-cache designs allocate cache memory in blocks rather than requiring one large contiguous region for each sequence. This can reduce fragmentation and make changing batch membership more practical, but it does not create unlimited memory. The cache pool is still finite.
What happens when cache headroom starts disappearing
A serving engine needs a policy for what happens as its cache budget fills. It may delay admission of new work, reclaim cache blocks, offload state to host memory or change how requests are scheduled.
That is an important physical transition. A workload that looked like pure GPU inference can begin involving system RAM and transfers between host and accelerator memory if the runtime and configuration permit offloading.
At that point, asking whether the model itself fits in VRAM misses the operational problem. The more useful question is whether the model plus the expected population of active sequences fits comfortably inside the serving memory budget.
Prompt length can hurt before generation even begins
Every request has at least two important phases: processing the input and generating the output. A long prompt can make the first phase substantial even when the requested answer is short.
In a shared system, that large prefill enters a GPU that may already be decoding tokens for other users. The scheduler has to balance new prompt processing against ongoing generation.
Users experience that trade-off as time to first token and the smoothness of streamed generation.
A benchmark made entirely from short prompts can therefore overestimate practical capacity for document chat, RAG and coding assistants, where real prompts may be much larger.
Two servers can report similar single-user generation speed and behave very differently under real multi-user traffic. The difference can emerge before token generation even starts, when large prompts compete for prefill compute and cache capacity.
Shared prompt prefixes can change the result again
Not every token in every request is unique. Production applications often send the same system prompt, tool definitions or other shared prefixes with many requests.
Inference systems with prefix caching can reuse compatible cached state for matching prefixes instead of repeating all of the same prefill work.
That means two applications with identical average prompt lengths can still have different serving characteristics. One may repeatedly send the same large prefix; another may send almost entirely unique text.
Average context length is useful. It still does not describe the whole workload.
Stop asking for the maximum number of users
For capacity planning, define a service target instead.
- Prompt-length distribution: measure typical and high-percentile input sizes, not only the average.
- Output-length distribution: long generations keep sequences active for longer.
- Concurrent requests: distinguish total registered users from people actually generating at the same time.
- TTFT: track median and tail values as load increases.
- Inter-token latency: measure whether streaming remains comfortable under concurrency.
- Aggregate throughput: observe how much useful work the server completes as more requests arrive.
- GPU memory: monitor cache and runtime headroom rather than model allocation alone.
- Queue time: separate waiting for service from actual model execution where the runtime exposes it.
Increase concurrency until one of those service objectives fails.
That point is much more useful than a theoretical maximum. If p95 TTFT crosses the limit you consider acceptable at eight simultaneous requests, then that workload has already exceeded your practical target even if the server could technically queue many more.
A capacity test should look like the application
Testing with identical 50-token prompts is easy, repeatable and potentially misleading.
A document assistant may regularly receive thousands of input tokens. A coding tool may reuse a large system prefix. An extraction workflow may produce tiny outputs. A chatbot may generate long answers while preserving conversation history.
| Application | Important workload property | Capacity risk |
|---|---|---|
| Document Q&A | Large retrieved context | Prefill cost and KV-cache pressure |
| Interactive chat | Growing conversation history | Longer active sequences over time |
| Classification automation | Short, predictable outputs | Arrival rate may matter more than generation length |
| Coding assistant | Large context plus variable generation | Both TTFT and sustained decode performance matter |
| Shared internal assistant | Bursty human traffic | Queue and tail latency during simultaneous arrivals |
A useful load generator should reproduce a distribution rather than a single ideal request. Even a simple test becomes more credible when it mixes short, medium and long prompts in proportions that resemble the real application.
A useful first-party test would find the point where increasing concurrency stops producing acceptable interactive performance on one GPU.
Why a second GPU is not automatically the next step
Once a single GPU reaches the service target, buying another accelerator is only one possible response.
The bottleneck might instead be excessive context, inefficient scheduling, poor batching, insufficient cache headroom or a workload that could benefit from prefix reuse.
If the model itself fits comfortably on one device, another GPU introduces a separate architectural decision. Requests could be replicated across GPUs, one model could be distributed across devices, or different workloads could be routed to separate accelerators.
Those choices solve different problems. The correct one depends on what the measurements say is actually saturated.
The capacity number belongs to the workload, not the GPU box
A specification sheet can tell you how much VRAM a GPU contains. A single-user benchmark can tell you how quickly a model generated tokens in one test. Neither can tell you how many people will be happy using the server at once.
That number appears only when real requests meet a scheduler, a finite KV-cache pool, accelerator compute and a latency objective.
Before upgrading the server, define the workload and watch what fails first. The first useful capacity limit may not be an out-of-memory error at all. It may simply be the moment a user presses Send and the first token takes too long to appear.