Continuous Batching
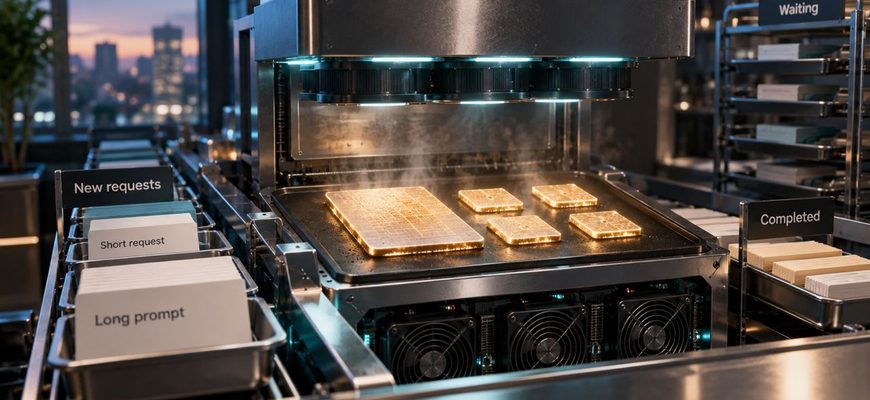
Four people are talking to the same local LLM. One asks a short question and gets an answer in seconds. Another requests a long explanation.
Three people are using the same local AI server. Two answers are already streaming at a comfortable pace. Then a third user pastes a long document and presses Send.
A local AI server can feel almost instantaneous when one person is using it. Add a second conversation and it may still feel fine. Add several people with