AI Server
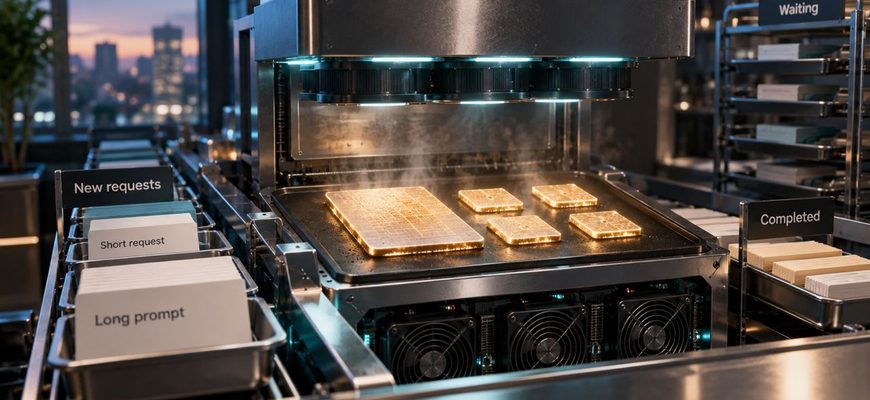
Four people are talking to the same local LLM. One asks a short question and gets an answer in seconds. Another requests a long explanation.
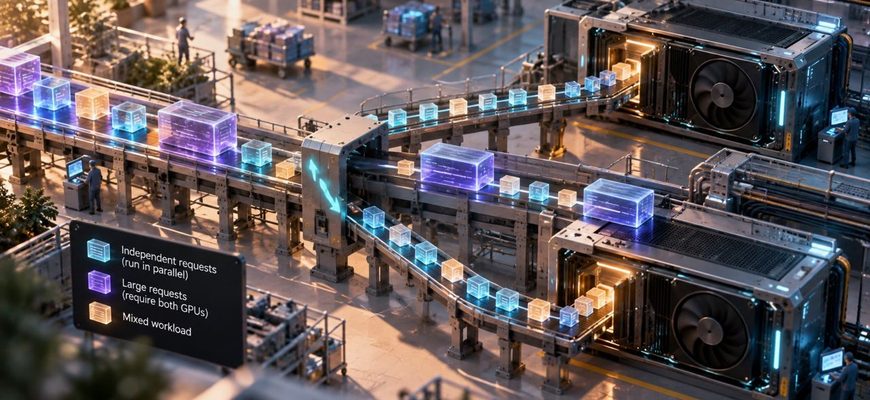
There is an appealingly simple upgrade path for a busy local AI server: install another GPU. Twice the accelerators should mean something close to twice
A local AI server can feel almost instantaneous when one person is using it. Add a second conversation and it may still feel fine. Add several people with