- Four things that make distance matter
- Meta is building one AI computing system across multiple sites
- How a message can cross the AI cluster
- GPU and network interface
- Building-scale fabric
- Backend Aggregation
- Optical link to another site
- A 100 km fiber link adds roughly half a millisecond of travel time
- The delay of distance alone
- Bandwidth and latency solve different problems
- Long fiber links can have enormous amounts of data in flight
- What 800 Gb/s means across 100 km
- The slowest conversation can hold up a larger computation
- Not every message belongs on the longest link
- At this scale, reliability becomes part of performance
- AI superclusters are becoming an infrastructure problem measured in geography
- Sources and Methodology
Imagine two buildings packed with AI servers. The machines are working on the same enormous model, exchanging information through optical fiber. Now move one of those buildings 100 kilometers away.
The computers have not become slower. Their GPUs are just as powerful. The fiber links can still carry an extraordinary amount of data.
Yet every message has farther to travel. Even a perfectly functioning network cannot make light arrive before the laws of physics allow it.
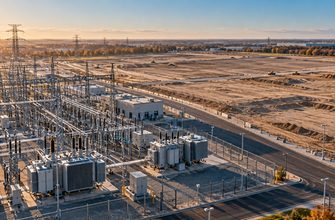
This is no longer merely a thought experiment. In October 2026, Meta revealed details of Prometheus, its expanding AI supercluster. Its backend aggregation network connects computing fabrics across distances ranging from 2 kilometers to more than 100 kilometers.
Meta says the first phase is complete and that Prometheus already contains hundreds of thousands of GPUs. Its longer-term goal is a system approaching one million.
The unexpected engineering problem is how to make geographically separated computers cooperate without spending too much time waiting for one another.
Four things that make distance matter
- Meta reports links in its Prometheus aggregation network spanning from 2 km to more than 100 km.
- Light traveling through ordinary glass fiber takes approximately five microseconds per kilometer.
- Higher bandwidth moves more data per second, but cannot remove propagation delay.
- Meta uses network architecture, deep buffering and communication-aware scheduling to reduce the impact of long-distance connections.
Meta is building one AI computing system across multiple sites
Traditional data centers are often described as collections of servers. At the scale of modern AI training, that description misses a crucial detail: the machines have to exchange vast amounts of information as a coordinated computing system.
A model can be distributed across multiple GPUs. Other GPUs may hold copies of model parameters while processing different training examples. During training, these groups must exchange information to keep their work consistent.
Some communication happens inside a rack, over short and extremely fast connections. Other messages travel across an entire building or between separate data centers.
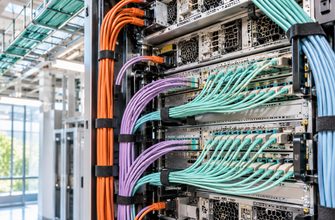
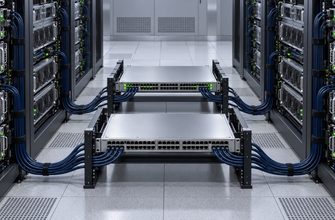
Meta calls its long-distance interconnection layer Backend Aggregation, or BAG. The system links building-scale network fabrics into a larger, regional computing network.
In its October 19 engineering report, Meta described building-level Ethernet fabrics supporting up to 20,736 GPUs apiece, connected through larger aggregation switches.
BAG uses high-capacity networking equipment, including Arista chassis built around Broadcom Jericho3 switching silicon. Meta reports multi-petabit bandwidth between regional network components.
How a message can cross the AI cluster
-
GPU and network interface
A processor produces data that must be exchanged with another part of the training system.
-
Building-scale fabric
High-speed Ethernet switches connect GPUs within the same building or local training domain.
-
Backend Aggregation
Deep-buffered aggregation switches interconnect fabrics and handle traffic crossing between sites.
-
Optical link to another site
Fiber-optic equipment transports data across the physical distance to a remote building or region.
Conceptual explanation, not Meta’s exact topology or a claim that every training message travels through all four stages.
The purpose of this architecture is not to send every GPU message over the longest available cable. It is to combine computing capacity across locations while controlling the cost of communication.
That distinction matters. A 100 km connection can be part of a large supercluster without every processor depending on that connection for every calculation.
02 / The Speed-of-Light ProblemA 100 km fiber link adds roughly half a millisecond of travel time
Light travels through a vacuum at nearly 300,000 kilometers per second.
Inside conventional optical fiber, its group velocity is lower, typically around 200,000 kilometers per second. That gives a useful engineering approximation: five microseconds for each kilometer of fiber.
At first, that sounds insignificant. But compare what happens as the physical path gets longer.
The delay of distance alone
Illustrative calculations using 5 µs/km. These are physical propagation estimates, not measured Meta network latencies. Actual cable routes can be longer than geographic distance. Transceivers, switching, encoding and congestion add further delay.
A 100 km fiber path therefore adds approximately 0.5 milliseconds in one direction.
If a message must travel that distance and a response must return, propagation alone contributes approximately one millisecond to the round trip.
This is a lower-bound illustration for that hypothetical path, not a claim about a measured Prometheus round-trip time.
Upgrading from a fast optical link to an even faster one does not shorten the physical distance between two data centers.
The optical signal still has to travel through the glass.
03 / Why Faster Cables Are Not EnoughBandwidth and latency solve different problems
An 800-gigabit-per-second connection can transport an extraordinary amount of data. Yet the first bit of that data still requires time to reach the receiver.
Bandwidth describes how much information can be sent per second. Propagation latency describes how long a signal takes to cross the physical link.
They are related operationally, but increasing one does not automatically eliminate the other.
| Property | Question | What helps? |
|---|---|---|
| Bandwidth | How much data can pass each second? | Faster optical interfaces, parallel links and network capacity. |
| Propagation latency | How long must the signal travel through the medium? | Shorter physical paths and suitable placement of communicating tasks. |
| Congestion | What happens when several flows compete? | Buffers, traffic engineering, routing and scheduling. |
| Reliability | What happens when a link or switch fails? | Multiple paths, fault detection and recovery mechanisms. |
Meta uses different optical technologies for different distances. Its engineering documentation describes shorter-reach connections within and between nearby buildings, while longer links use coherent optics, including 800G-ZR technology.
Coherent optics allow powerful, high-capacity connections to extend beyond the reach of ordinary short-distance transceivers.
But even coherent optics cannot cancel the travel time imposed by distance.
04 / Why Buffers Get BiggerLong fiber links can have enormous amounts of data in flight
Picture sending a constant stream of packets into a long optical cable. By the time the first packets reach the far end, the sender has already transmitted many more.
Engineers describe this with the bandwidth-delay product: the amount of data that can be outstanding during a chosen delay interval.
What 800 Gb/s means across 100 km
At 800 gigabits per second, approximately 0.5 milliseconds of one-way propagation corresponds to about 50 megabytes of data in flight.
Decimal units. This is a bandwidth-delay calculation, not a specification of Meta’s deployed switch-buffer size. Actual buffer requirements depend on protocol behavior, traffic patterns and congestion-control design.
The calculation helps explain why long-distance congestion management becomes complicated.
If a receiver needs a sender to slow down, that instruction must travel back. Meanwhile, more data may already be moving toward the receiver.
In its 2026 OCP engineering report, Meta explained that buffer headroom has to account for cable length.
Its BAG architecture uses deep-buffered switches for long-distance traffic, while shorter building fabrics can use shallower-buffer switches designed for their local workload.
Meta also described measuring real cable length using timing probes so that buffer allocation can reflect the deployed connection rather than one universal worst-case assumption.
This is a revealing detail: even with petabit-scale network capacity, the physical length of a fiber path affects software and hardware decisions.
05 / The Training ProblemThe slowest conversation can hold up a larger computation
Training large AI models involves more than assigning each GPU a pile of work. The machines must exchange results and synchronize at important points.
Suppose a group of GPUs finishes a computation and needs information from another group.
If the next step depends on that exchange, it cannot begin until the required communication completes.
A small delay may seem harmless once. Repeated across many synchronization phases, it can reduce the fraction of time GPUs spend doing useful arithmetic.
This is why Meta does not treat all network paths as interchangeable.
Its published design keeps particularly latency-sensitive communication close together, within tightly connected training groups.
Communication that can tolerate greater delay is more suitable for the higher aggregation layers connecting sites.
Not every message belongs on the longest link
- Inside a rack: Keep tightly coupled accelerator communication on the fastest local fabric.
- Inside a building: Use high-bandwidth Ethernet fabrics for communication that requires frequent exchange.
- Across sites: Route traffic through BAG when workloads and network architecture can absorb the additional latency.
- During scheduling: Arrange work to avoid unnecessary long-distance synchronization.
Simplified description of the trade-offs discussed by Meta. Actual placement is determined by workload parallelism, available resources, network topology and fault tolerance.
In the October 2026 OCP material, Meta reported that collective communication libraries can lose substantial performance when they ignore the extra distance between network fabrics.
Its response includes routing improvements and scheduling changes that minimize how much communication must cross BAG.
The objective is not to make light faster. It is to make a training job less dependent on waiting for distant messages.
06 / Why the Network Must Survive FailureAt this scale, reliability becomes part of performance
A massive training cluster contains a large number of links, optical modules, network switches and compute devices.
Even when each component is individually reliable, failures become a normal operating concern at fleet scale.
Meta reports using redundant network paths and automatic rerouting so a single fiber or port failure does not necessarily interrupt a training job.
Its team also described recovering from certain GPU failures by restarting affected training replicas while allowing other replicas to continue.
That is a different kind of optimization from simply buying a faster GPU.
A processor is useful only while it can perform productive work. Communication delays and failures can leave expensive accelerators waiting.
This connects to a different physical problem explored in our article about microscopic contamination on fiber connectors . Both stories involve optical infrastructure, but at radically different scales.
A damaged connection can affect link quality over a few centimeters. A perfectly clean connection extending across 100 km still faces unavoidable propagation delay.
07 / What This ChangesAI superclusters are becoming an infrastructure problem measured in geography
For years, the most visible improvements in AI hardware came from faster processors, larger memory systems and denser racks.
Those improvements still matter. But they cannot independently solve the challenge of connecting computing capacity spread across multiple sites.
Every additional building changes the physical network. Every longer optical route affects latency. Every new network tier introduces switching, congestion-control and reliability decisions.
The same concentration of AI equipment creates challenges in other infrastructure layers. We have examined how synchronized GPU workloads affect electrical demand , and why Meta has begun liquid-cooling network switches as well as GPUs .
The network-distance problem belongs to the same physical reality.
A large AI model may run on hardware spread across an entire region. To make it behave like one useful computing system, the engineers must carefully manage which conversations take place locally and which travel farther.
Meta’s Prometheus project shows how far that design has already progressed. Its current interconnection architecture includes distances beyond 100 km, and Meta is exploring still larger geographic training systems.
The next limit on AI performance may not be how quickly a GPU can calculate. It may be how long that GPU has to wait for another one.
Sources and Methodology
- Meta Engineering, October 19, 2026 . Prometheus scale, BAG reach, optical interconnects, scheduling and reliability.
- Meta Engineering, October 12, 2026 . BAG, buffering by cable length, cross-fabric communication and multi-site networking.
- Meta Engineering, October 26, 2026 . OCP technical sessions on multi-site networking and optical systems.
- Meta Engineering, February 9, 2026 . BAG architecture, regional interconnection and deep-buffer design.
- Meta Engineering, October 16, 2025 . Fiber distance classes and coherent optical technology.
- Photonica, Fiber Latency Calculator . Optical propagation based on standard single-mode fiber group refractive index.
All Meta hardware and network details are attributed to Meta’s published engineering disclosures. Propagation delay and bandwidth-delay examples are transparent theoretical calculations, not measurements taken inside Prometheus. il.digital has not independently benchmarked Meta’s network.