Blog
A local model may advertise a 32K, 64K, 128K, or even larger context window. That does not mean you should configure your local runtime to use the maximum.
A local LLM being slow does not automatically mean that your GPU is too weak. The model may be spilling into system RAM, the CPU may be doing more work
Q4_K_M, Q5_K_M and Q8_0 can run the same model with very different memory requirements. Here is how to choose without wasting VRAM.
A local RAG system can use a capable language model and still return weak answers if its embedding model retrieves the wrong passages. The embedding model
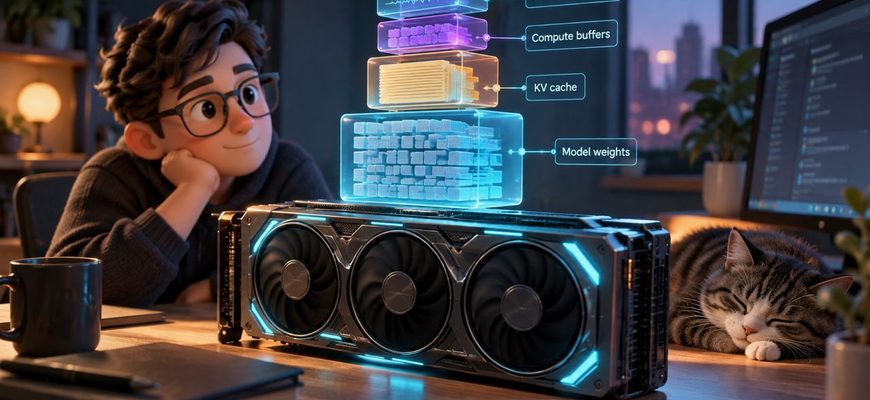
A 14 GB model file does not mean you need exactly 14 GB of VRAM to run it. The weights are only one part of the memory used during inference.
A local LLM can fit comfortably into your GPU at an 8,000-token context and run out of memory when you increase that context several times over.
On an island, the internet has a shoreline. In Tonga, that shoreline is part of a much larger system stretching beneath the Pacific. Fiber-optic cable

A Telegram bot can be more than a chat interface. With a small Python service, it becomes a secure remote control for repeatable workflows: checking system

How to Build a Local AI Server Under $1,000 You do not need a $3,000 workstation to run AI models at home. With the right balance of GPU VRAM, system memory

Choosing a local language model is not about downloading the model with the highest benchmark score. The right choice depends on your hardware, available