Blog
8GB, 12GB and 16GB GPUs belong to very different local-LLM tiers. Here is what models actually fit once quantization, KV cache and context are included.
A 12GB GPU can run a 30B local LLM — but usually not entirely in VRAM. Here is what quantization, CPU offloading and context memory actually do.
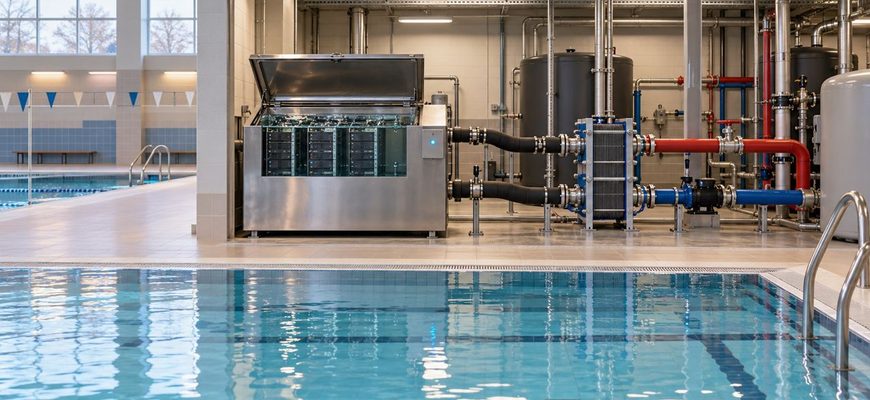
A few metres of pipe connect computing to swimming in Exmouth. The engineering is real. Understanding the savings means following the heat beyond the servers.
Project Natick · Microsoft 864 servers. Two years underwater. No technicians. Microsoft sealed an entire datacenter inside a steel cylinder and lowered
Press regenerate and the answer changes. Move the temperature, narrow the token pool, and watch how one small choice sends a reply down another path.
One long prompt can slow down an entire shared AI server. Learn how prefill, GPU scheduling, and chunked prefill affect latency and keep concurrent LLM
A faster PCIe connection does not always make local LLM inference faster. Learn when PCIe bandwidth matters for model loading, CPU offloading, and GPU performance.
A 16-core CPU can load a quantized local LLM, show activity across many cores, and still generate text much more slowly than expected. Adding threads may help at first.
You download a model described as 30B-A3B. The second number looks reassuring: only about three billion parameters are active for each token.
A shared LLM server is approaching its limit. The model weights still fit. The GPU has not reported an out-of-memory error. But long conversations and