Blog

Illustration showing how an AI question travels from a smartphone through the internet to a data center, where AI generates an answer and sends it backFor Beginners
What Actually Happens When You Ask AI a Question?
085
FOR BEGINNERS · INSIDE A SINGLE AI MESSAGE You type one question. Somewhere else, a computer begins building the reply. Here’s the trip your words take.
Case Studies
Finland’s Sand Battery Heats Buildings With 2,000 Tons of Rock
079
A small Finnish town is heating buildings with 2,000 tons of crushed rock. Discover how this unusual sand battery works, why it stores heat instead of
Case Studies
Google Built Internet Balloons That Worked. Why Did Loon Shut Down?
059
Google sent giant balloons into the stratosphere to bring internet access to remote communities. The technology worked in real deployments, including Puerto
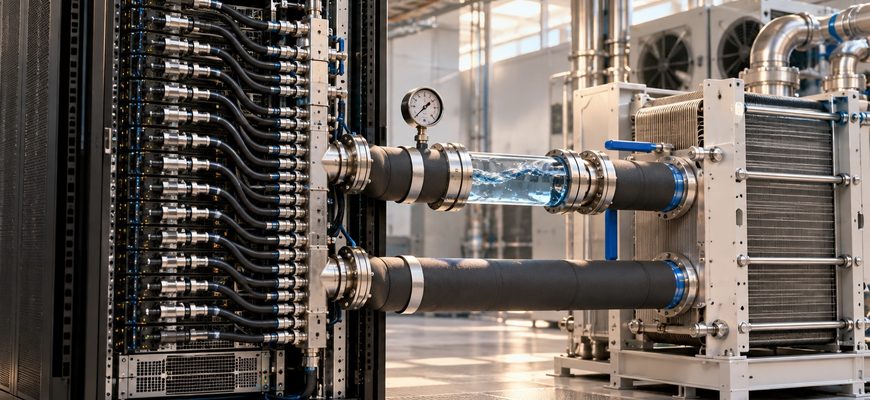
AI rack cooling system with liquid-cooled server hardware, coolant hoses, a manifold and a heat exchanger inside a data centerServers
Inside a 135 kW AI Rack: Where 90% of the Heat Goes
093
A single AI rack can produce an enormous amount of heat. We examine Lenovo's 135 kW GB300 NVL72 design, calculate how much coolant would need to circulate
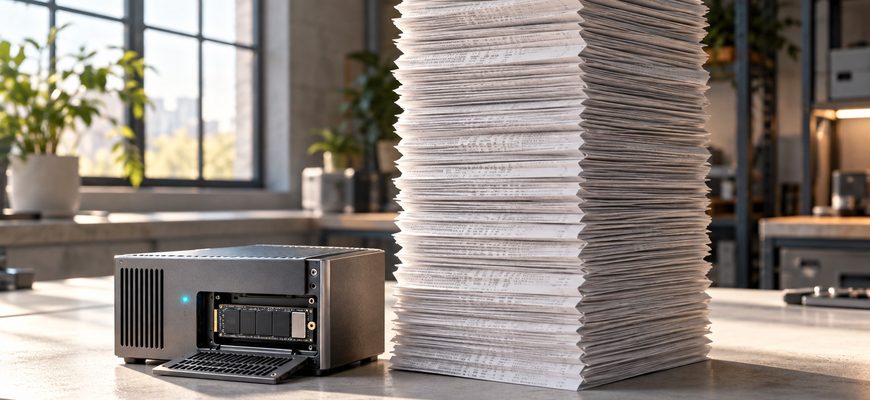
A compact automation server with an exposed NVMe SSD beside a towering stack of execution records, illustrating how n8n workflow history consumes disk space.Automation
Your n8n Workflows Finished. Why Is the SSD Still Filling Up?
0120
Your n8n workflows finish successfully, but the server keeps running out of storage. Discover how execution records, binary files and SQLite consume disk
LLM request cancellation illustrated by an empty office with an inference workstation still running behind glass.Servers
Why Your LLM Server Keeps Working After You Close the Chat
0112
LLM request cancellation should stop work that nobody needs anymore. Yet you can ask your local AI server for a long report, read the first few lines and
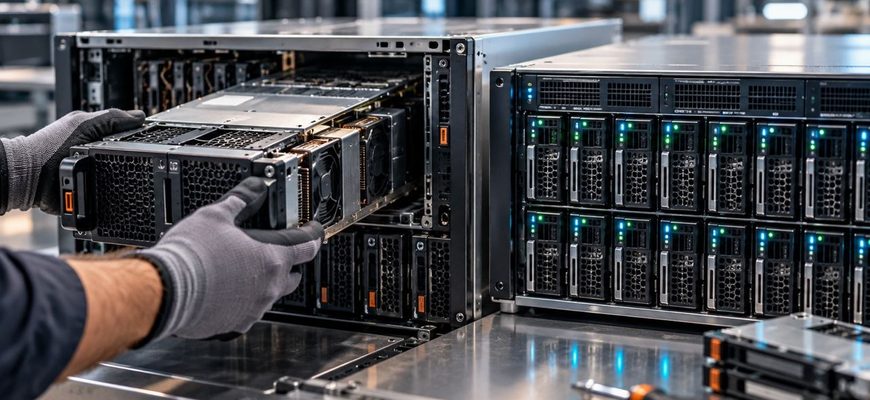
AI agent crash recovery: a technician removes a failed compute server module while a separate storage system remains operational, preserving workflow data.Automation
What Happens When an AI Agent Crashes Halfway Through a Task?
0119
An AI agent crashes halfway through a task. Does it lose its progress or pick up where it stopped? Discover how checkpoints, durable execution, and persistent
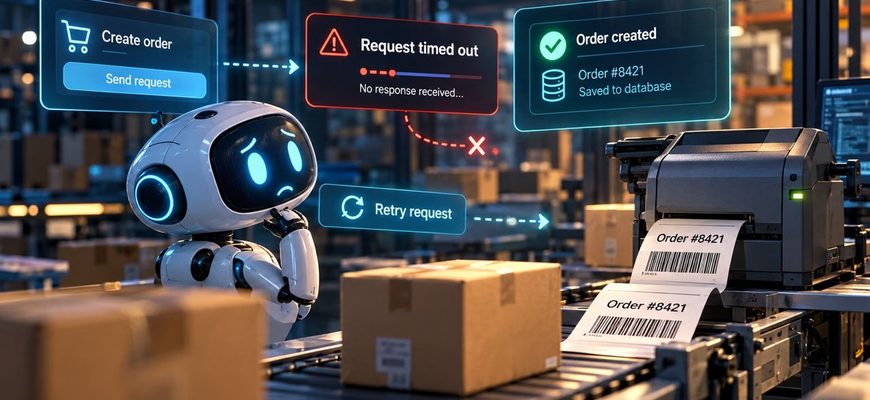
Why AI agents repeat actions after timeout: a confused AI robot monitors a failed request while an automated warehouse produces duplicate orders.Automation
Why AI Agents Repeat Actions After a Timeout
0110
An AI agent can complete an action successfully and still receive a timeout. When the workflow retries, one customer request can become two orders, emails or payments.
Automation
AI Agents Don’t Actually Click Buttons: What Really Happens When a Model Uses Tools
098
An AI agent does not directly control your apps. It requests a tool call, your workflow executes it, and the result comes back. Here is the loop, the risks
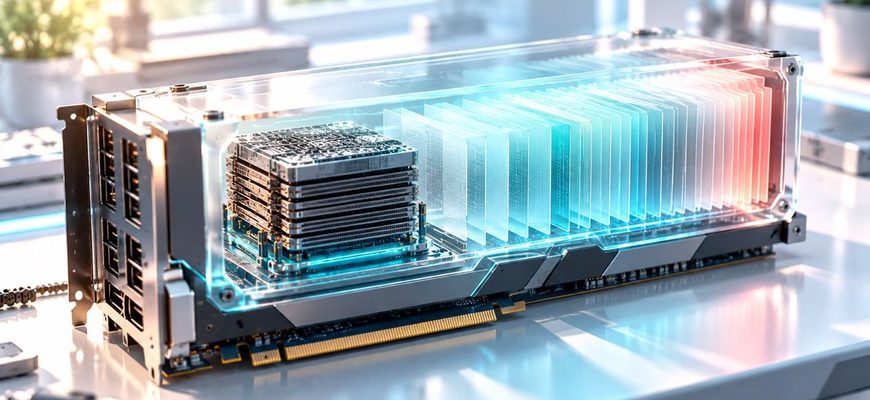
A local LLM fitting inside GPU VRAM while translucent context-memory layers expand and fill the remaining space.Inference
Why a Model Fits in VRAM but Still Runs Out of Memory at Long Context
0182
Your local LLM fits in VRAM — until you increase the context window. Here is why KV cache can consume several extra gigabytes and trigger an OOM.