- 🛰️ The tool loop, without the marketing
- 🧰 A tool is basically a contract
- 🪐 The permission design is more important than the prompt
- 🎛️ Try a tiny mission-control policy
- 🛑 Approval should happen before the side effect
- 🌑 Where agent workflows fail in real life
- 📡 Retrieval is a tool too
- 🖥️ Can the “brain” be a local model?
- 🚀 A practical architecture that stays understandable
- 🪐 Read next
- The useful mental model
Here is what happens when a model uses tools.
Give a model access to email, a calendar, a database or an API and it suddenly looks much more capable.
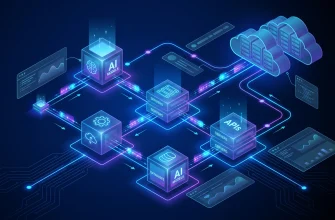
But the interesting part is not the model. It is the loop around it: the model requests an action,
your software decides whether that action is allowed, another system executes it, and the result comes back.
The phrase AI agent can make a fairly ordinary software pattern sound mysterious.
Strip away the branding and you usually find a very understandable mechanism:
a language model chooses from a list of tools, proposes arguments for one of them, and waits while the surrounding application does the real work.
That distinction matters. A model that can write text is relatively contained. A system that can send mail,
change records or call APIs has consequences outside the chat window.
The moment a model can act, permissions, validation and approval become part of the product.
The model chooses
It decides which allowed tool looks useful.
The app executes
Your workflow or backend performs the real API call.
Rules set the boundary
Permissions and validation decide what is allowed.
Humans handle risk
Important actions can pause for approval.
In a well-designed system, the model gets a description of an approved tool.
It can request the tool. It cannot bypass the code that actually owns the credentials.
🛰️ The tool loop, without the marketing
Imagine a support agent receives this request:
“Move my meeting with Dana to Friday afternoon and send her a note.”
A useful agent may need a calendar search tool, a calendar update tool and a message tool.
The sequence is not one giant prompt. It is a loop.
Request arrives
The user asks for an outcome, not a specific API call.
Model sees tools
Names, descriptions and accepted parameters are included.
Tool is requested
The model returns a structured call with arguments.
Software executes
The workflow validates the request and talks to the external service.
Result comes back
The model sees the output and decides whether another step is needed.
The loop can repeat several times. Search the calendar. Read two matching events. Ask a follow-up if there is ambiguity.
Update one event. Draft a message. Pause before sending it.
This is why agent behavior feels different from a normal chatbot.
The model is no longer only generating an answer. It is selecting operations inside a controlled software environment.
🧰 A tool is basically a contract
A good tool definition is boring in the best possible way.
It tells the model exactly what the tool does and what data it expects.
{
  "name": "move_calendar_event",
  "description": "Move one existing event",
  "parameters": {
    "event_id": "string",
    "new_start": "ISO datetime",
    "new_end": "ISO datetime"
  }
}
Notice what is missing.
There is no “do anything to my calendar” permission.
The tool has a narrow job and a small set of inputs.
Narrow tools are easier to validate, easier to audit and much harder to misuse accidentally.
A common mistake is to give an agent one extremely powerful generic tool such as
run arbitrary database query or call any API endpoint.
That may look flexible during a demo. It also moves most of your safety boundary into a probabilistic model.
🪐 The permission design is more important than the prompt
Prompts can tell a model to be careful. Permissions decide what “careful” actually means.
| Tool | What it can do | Typical policy | Why |
|---|---|---|---|
| Search calendar | Read event metadata | Auto-run | Read-only and easy to recover from |
| Draft email | Create text but not send it | Auto-run | No external side effect yet |
| Send email | Communicate externally | Approve when sensitive | A wrong message reaches another person |
| Update CRM record | Change business data | Validate + log | Errors can affect later workflows |
| Delete file | Remove data | Block or require approval | Potentially destructive |
The useful principle is least privilege:
give the agent the smallest set of tools and scopes that can finish the job.
If the agent only needs to read customer records, do not hand it a write credential.
🎛️ Try a tiny mission-control policy
This simplified simulator shows how the same agent can be useful without treating every action equally.
Pick an action and watch the policy around the model change the route.
What should the agent be allowed to do?
Read-only action. Execute it and return the result to the model.
This is the point of human-in-the-loop design.
The person is not approving every harmless lookup. They appear at the boundary where a mistake starts to matter.
Workflow platforms are increasingly building this pattern directly into agent tooling.
For example, n8n can pause selected AI tool calls and request human approval before the action executes.
That is much more useful than asking a model to “double-check itself.”
🛑 Approval should happen before the side effect
A weak approval flow asks a person to inspect the damage afterward.
A strong one pauses the workflow before the irreversible action.
For an email agent, that means the model can search previous messages, retrieve customer context and write a draft automatically.
The send operation is a separate tool. If the message is sensitive, the workflow pauses there.
Drafting an email and sending it are different operations.
Calculating a refund and issuing it are different operations.
Generating a database update and committing it are different operations.
🌑 Where agent workflows fail in real life
Most failures are less dramatic than science fiction.
They are ordinary software problems mixed with uncertain model behavior.
Wrong tool
The model chooses a plausible tool that is not the correct one for the job.
Wrong arguments
The tool is correct, but a date, ID, amount or target is malformed or misunderstood.
Looping
The model keeps calling tools because it does not recognize that the task is already complete.
Stale state
The world changes between reading data and acting on it.
Too much permission
A broad credential turns a small reasoning error into a large operational mistake.
Hidden cost
One task quietly turns into many model calls, searches and API operations.
This is also why testing an agent only through a pleasant chat interface is not enough.
You need to inspect tool calls, arguments, retries, execution time and final side effects.
📡 Retrieval is a tool too
Not every tool changes the outside world.
Search and retrieval tools can give an agent information it does not already have:
internal documents, product data, ticket history or a private knowledge base.
In a RAG-style workflow, the model may call a retrieval tool, read the returned chunks and then decide whether it has enough evidence to continue.
If you are building that side of the system, our guide to
choosing an embedding model for local RAG
explains the retrieval layer in more detail.
🖥️ Can the “brain” be a local model?
Yes. Tool calling is an orchestration pattern, not a cloud-only feature.
A local model can choose tools if the runtime and model support structured tool output well enough for your workflow.
The practical question is whether the model is reliable enough at selecting tools and producing valid arguments.
Smaller local models may be perfectly useful for narrow workflows with three or four clearly described tools,
while a complicated agent with twenty similar tools is a much harder test.
If you want to keep the model and workflow on hardware you control,
see our guide to
building a local AI server under $1,000.
🚀 A practical architecture that stays understandable
You do not need a giant multi-agent system to get useful automation.
A surprisingly strong design is:
If you are just getting started, the broader
AI automation guide
shows where agents fit among normal workflows, AI steps and approval gates.
If you want a visual workflow builder rather than writing the orchestration yourself,
our
n8n introduction
is a good next step.
And if you prefer a small code-first project, try the
Telegram automation bot with Python.
🪐 Read next
Automation
How to Automate Tasks with AI in 2026: Workflows, Agents and Human Approval
Workflow tools
What Is n8n and How It Is Used in AI Automation
Build it
Build a Telegram Automation Bot with Python
Retrieval
How to Choose an Embedding Model for a Local RAG System
The useful mental model
An AI agent is not a model with magical access to your software.
It is a model inside a tool loop.
The model proposes. Your application validates. Tools execute.
Results return. Humans step in where the consequences justify it.
Once you see the architecture this way, agent design becomes much easier to reason about.
The big question is no longer “How smart is the agent?”
It is “What exactly is this system allowed to do, and what happens when it is wrong?”