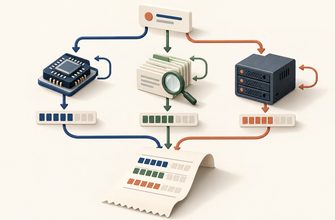
Imagine a thousand AI agents completing their tasks at roughly the same moment. Each one saves a result, checks a record and updates its status. Their language models may run on different machines, yet the requests can converge on one ordinary database. The bottleneck is no longer the intelligence of the agents. It is the queue outside the data store.
This can happen without a malicious attack or an unusually large query. A well-behaved agent multiplied many times creates a very different traffic pattern from one agent working alone. The difficult moment is often not the steady average but the burst when retries, scheduled jobs and completed tool calls line up.
One database, many independent workers
A typical workflow reads a task record, calls one or more tools, writes output and marks the task complete. At small scale, the application may open a database connection and finish in milliseconds. At large scale, thousands of near-simultaneous actions compete for connections, CPU, storage I/O and locks. A database cannot simply execute every request at once.
PostgreSQL exposes a maximum connection setting, but the maximum number of connections is not the same as the number of useful queries per second. Each connection consumes resources, and poorly shaped transactions can create waits even when the server has spare capacity elsewhere.
The connection limit is only the first pressure point
Opening too many connections is a visible failure mode: new clients may wait or be refused. A connection pooler such as PgBouncer can let many application clients share a smaller number of server connections, depending on its pooling mode. That helps manage connections; it does not make the underlying storage infinitely fast.
Inside the database, a second queue can form. Agents updating the same account, inventory counter or workflow status may compete for row locks. Long-running transactions hold those locks while other operations wait. A single hot row can therefore slow unrelated-looking agent tasks that all need to touch it.
Then comes disk work. An agent may write a result, an audit trail, embeddings, intermediate state and several tool events. Even small writes become substantial when repeated thousands of times. When the transaction log, index maintenance or storage I/O falls behind, latency rises and the application may mistakenly assume that requests have failed.
Retries can make an ordinary slowdown worse
Suppose an agent waits two seconds for a database response and times out. It retries. Hundreds of other agents may do the same. If the original operations are still running, the retries increase work at the exact moment the system needs less. A burst becomes a feedback loop.
Blindly increasing timeouts can hide the problem. Raising the connection limit can also move pressure toward memory and CPU. What matters is controlling how much work reaches the database at any instant.
How engineers keep the queue from becoming an outage
- Bound concurrency. Set a global limit on outstanding database operations, not merely a per-agent limit.
- Pool connections. Reuse connections and cap server-side sessions to a capacity established by testing.
- Keep transactions short. Avoid holding locks while an agent waits for an LLM response or an external API.
- Make writes idempotent. An operation retried after a timeout should not duplicate a payment, job or state transition.
- Add backpressure. When queue depth rises, admit work more slowly and return clear retry instructions with jitter.
- Measure the right signals. Watch pool wait time, active transactions, lock waits, query latency, write I/O and rejected requests.
Queues should have limits of their own. If the backlog grows without bound, the system has exchanged a database outage for an unbounded waiting problem. Workers need expiry rules, cancellation handling and enough observability to distinguish “waiting” from “lost.”
Why this is specifically an AI-agent problem
Ordinary web applications also experience bursts. Agents add two complications. First, the number and order of tool calls can vary by task, so demand is harder to predict. Second, agents can trigger more work based on previous results. A new job may fan out into searches, writes and follow-up tasks, all sharing the same database.
Our earlier explanation of why hundreds of agent API calls matter looks at a neighboring cost bottleneck. And two agents editing the same file shows how concurrency can damage correctness, not just speed.
The practical test is simple: a successful agent demo proves that one workflow runs. It does not prove that the shared database survives one thousand workflows arriving together. Scale testing must include bursts, failed calls, retries and the exact writes agents perform.