- The process can end while the thread survives
- Memory within the current conversation is a product decision
- A checkpoint is a saved position, not an exact recording of everything
- Why deleting a chat is not always the same as deleting the data
- Design the stop button and the delete button for different jobs
- Sources
Stopping an AI agent does not necessarily erase what the agent remembers. The process may disappear from a server’s memory while the conversation, an unfinished draft, tool results or a saved checkpoint remain on disk or in a database. Another run may be able to pick them up later. The survival of that data is an architectural choice, not evidence that the AI is still thinking after it stops.
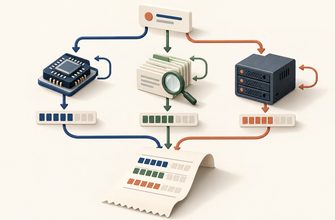
To understand the difference, we have to unpack the word memory. In an agent application it may refer to live working state in RAM, stored conversation turns, workflow checkpoints, longer-lived preference records or operational logs. These are not interchangeable systems, and terminating one does not automatically clear the others.
The process can end while the thread survives
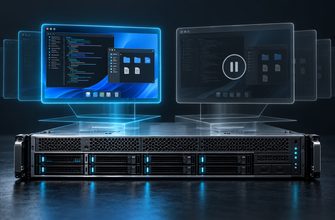
Imagine an assistant asked to review a supplier proposal. It retrieves two documents, writes a partial comparison and stops before producing the final answer. The running process can exit, and its temporary variables may be released. If the application had already committed the conversation and intermediate state to durable storage, those records remain available for a resumed task.
That behavior is a deliberate feature in many agent frameworks. The LangGraph persistence documentation describes checkpoints for thread-scoped state and separate stores for information shared across threads. Those systems allow continuity after an interruption, but they also create records that need governance and retention policies.
It is equally possible to build a simple agent with no durable history. In that case, once the process and its volatile state disappear, the agent may have no record of the earlier request. The difference is not intelligence; it is where the application writes state.
Conceptual architecture, not a universal product design. Durable storage lasts only under the service’s configured policies and actual storage behavior; writing a value to a cache does not guarantee persistence after a restart.
Memory within the current conversation is a product decision
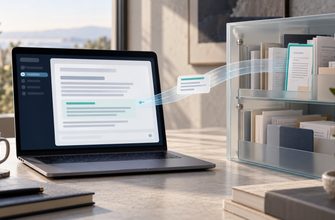
Agent SDKs can maintain history across runs, so the application does not need to resend every earlier message manually. The OpenAI Agents SDK sessions documentation explains patterns including client-managed session history, server-managed conversation state and custom stores. These are options for developers, not a promise that every assistant saves the same data or retains it for the same period.
A conversation record is also different from a long-term profile. Saving the dialogue allows a later step to see previous turns; storing a permanent preference is a separate operation. A system can support one without the other.
When a conversation grows, some applications trim or summarize older turns to fit a model context window. Removing a turn from the next model prompt does not prove its original record has been deleted from a database, log or backup. Context management and data retention have different purposes.
A checkpoint is a saved position, not an exact recording of everything
A checkpoint generally captures the state the workflow engine knows how to save. That might include a task identifier, generated draft, message list or pending step. It does not necessarily contain every byte from a tool’s process memory or every intermediate token generated before a crash.
Timing matters. A process can fail after making a real-world change—such as creating a calendar event—but before recording a checkpoint saying the action succeeded. Restarting from an earlier checkpoint can then repeat the same tool call unless the workflow checks whether the action already happened.
We have explored this distinction in Why AI Agents Repeat Actions After a Timeout. The failure has little to do with how long a model “remembers.” It is about durable acknowledgment and safe retry design.
Similarly, a checkpoint that restores an agent’s draft is not the same as restoring revoked credentials. Our recent article on agents losing access mid-task explains why a saved task state cannot make a denied external operation succeed.
| What happened | Volatile state | Durable records | What a later run knows |
|---|---|---|---|
| User stops a run | In-flight work may be cancelled; effects depend on the runtime. | Previously committed history and tool results may remain. | Only what the application chooses to reload. |
| Worker process crashes | In-process memory is generally lost. | Committed checkpoints and database records can survive. | Last successfully saved state, not necessarily the last action taken. |
| Session history is cleared | Unrelated running processes need not stop. | History in that store may be removed; separate copies can persist. | Depends on other memory stores and retention systems. |
| Workflow completes normally | Temporary state can be released. | Final output, session state, logs or backups may be retained. | Depends on saved session and memory design. |
Why deleting a chat is not always the same as deleting the data
Developers need to distinguish at least four controls: stopping execution, removing a conversation from an interface, deleting the active application’s primary record and applying deletion requirements to logs or backups. Each acts on a different part of the system.
A retained debug trace might contain a tool response even if the main chat history is cleared. A checkpoint database can contain earlier states. A backup may be subject to an independent expiration schedule. Conversely, some applications deliberately keep no persistent checkpoints and retain nothing after the process is terminated. There is no single retention rule that applies to all “AI agents.”
OpenAI’s Agents SDK documentation explicitly describes customizable session storage and retention controls. LangGraph documentation likewise distinguishes persistent records from ephemeral process state and recommends managing checkpoint growth. Those examples show why retention must be defined at the storage layer rather than inferred from a stop button.
For a second angle on durable execution, see What Happens When an AI Agent Crashes Halfway Through a Task?. Its recovery problem is the engineering reason teams intentionally preserve state in the first place.
Design the stop button and the delete button for different jobs
A responsible agent product should make the distinction understandable. Stopping should prevent further work as far as the system can enforce it; a completed external action cannot always be undone. A separate deletion workflow should identify the categories of saved data it covers, who can access them and when residual records expire. “No longer shown in the chat” is not a complete retention specification.
For operators, the most useful test is a controlled resume: stop the worker, inspect committed checkpoints, restart it with the same thread identifier and compare the visible state against what the application claims it retained. Then test deletion separately, including audit logs, external tool outputs and backups within the service’s retention policy. Such testing evaluates a particular implementation; it does not prove what another agent product does.
One boundary worth remembering: an AI model does not need to remain active for an application to retain a record of its earlier work. Persistent storage, not continued model activity, is what makes that record available later.
The right question after an agent stops is therefore not simply “Is its memory gone?” It is which layers held its state, which writes completed, and what deletion policy governs each copy? Without those answers, a stopped agent can be mistaken for an erased one—and a saved checkpoint can be mistaken for a complete record of everything it did.