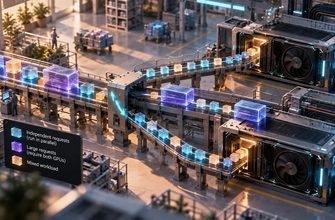
Three people are using the same local AI server. Two answers are already streaming at a comfortable pace. Then a third user pastes a long document and presses Send.
Nothing has changed about the model or GPU. Yet the first two responses may become less smooth while the new user waits for a first token. The machine is still working, but it has encountered a scheduling conflict: a large prompt needs substantial parallel computation just as existing requests need small, frequent decode steps.
This is prefill–decode interference. It explains why a server can look fast in a single-user benchmark and behave differently when long prompts enter a live queue. It also explains why modern serving engines do more than place requests into a conventional batch. They decide which tokens receive GPU time, when new work is admitted, and whether a large prefill should be divided into smaller pieces.
- A long prompt is a compute-heavy prefill job, not merely more text waiting in a queue.
- Existing responses still need repeated decode iterations while the new prompt is processed.
- Processing the entire prefill at once may improve the new request’s TTFT while disturbing inter-token latency for requests already decoding.
- Chunked prefill divides the prompt work so a scheduler can interleave it with ongoing generation.
- The correct configuration depends on whether the service values fastest admission, smooth streaming, maximum throughput or a controlled balance.
- One GPU is serving two very different kinds of work
- The new request can disturb work already in progress
- Why ordinary batching is a poor fit for generated text
- Chunked prefill turns one large obstruction into schedulable pieces
- A faster server can still feel worse
- RAG and coding assistants are natural stress tests
- How to recognize prefill interference
- Existing streams pause when a document request arrives
- TTFT improves while streaming becomes less consistent
- Throughput rises but p95 latency worsens
- Single-user tests look excellent
- Configure the scheduler around the experience you need
One GPU is serving two very different kinds of work
Autoregressive LLM inference has two phases with different execution patterns.
During prefill, the model processes the input tokens supplied with the request. Those tokens can be evaluated with substantial parallelism. A long prompt therefore gives the GPU a large block of computation and creates the model state needed before generation can begin.
During decode, the model generates the response one token at a time. Every active sequence repeatedly returns for another forward pass. A user experiences the interval between those passes as the rhythm of streamed text.
| Phase | Work entering the GPU | User-visible metric | Scheduling concern |
|---|---|---|---|
| Prefill | The request’s input tokens are processed and their attention state is created. | Time to first token | A large prompt can occupy a substantial scheduling interval. |
| Decode | Each active sequence advances by another generated token. | Inter-token latency | Streaming feels smooth only if sequences receive work regularly. |
| Queueing | Requests wait until the scheduler admits their tokens. | Queue delay and tail TTFT | Admission policy decides which request waits. |
| Mixed load | Long prefills and active decodes compete for finite compute and memory. | TTFT, ITL and throughput together | Improving one metric can worsen another. |
The distinction matters because a scheduler is not choosing between identical jobs. It is mixing large parallel prompt-processing work with small latency-sensitive generation steps.
The earlier il.digital guide to prompt processing and token generation explains why local LLM speed has two numbers. A shared server adds another dimension: those two phases can belong to different users and compete at the same moment.
InterferenceThe new request can disturb work already in progress
Imagine that Requests A and B are decoding. Their KV-cache state is already resident, and the scheduler repeatedly advances both sequences. Request C then arrives with a much longer prompt.
If the serving engine processes C’s entire prefill as one large unit, A and B may wait longer than usual for their next decode opportunity. C benefits from immediate prompt processing, but the users watching A and B may see a pause or less consistent streaming.
The conflict is not abstract API traffic. The long prompt becomes tokenized data processed through repeated model layers on the accelerator. Its attention state consumes KV-cache capacity in VRAM, while active responses need their own state and recurring access to the same GPU. A scheduler policy therefore becomes visible as computation, memory occupancy and waiting time.
Why ordinary batching is a poor fit for generated text
Traditional static batching works best when jobs have similar shapes and finish together. Generated responses rarely cooperate that neatly. One request may stop after a short sentence while another continues for hundreds of tokens.
If the entire batch remains tied to the longest sequence, completed slots waste potential capacity. Continuous or in-flight batching changes membership as execution progresses. Finished requests leave, new requests enter, and the scheduler operates at a finer granularity than “run this fixed group until everyone is done.”
This makes the GPU more useful under variable traffic, but it does not eliminate the prefill–decode conflict. A newly admitted prompt may be far larger than one decode step. The scheduler still needs a policy for fitting that work alongside active generation.
ChunkingChunked prefill turns one large obstruction into schedulable pieces
Chunked prefill divides a long prompt into smaller token groups. Instead of processing the complete prefill in one uninterrupted scheduling unit, the engine can place a chunk into a batch, advance existing decode requests, and continue with another chunk later.
This gives the scheduler more control over the interference boundary. Active decodes can receive regular service while the new prompt gradually moves toward its first generated token.
Chunking does not make prompt processing free. The same prompt still needs computation, and its inference state still needs memory. Chunking changes when the work runs and what can run beside it. It is a scheduling mechanism, not a way to erase the physical cost of a long context.
The chunk size and total token budget create a trade-off. Larger chunks may process the new request more aggressively, potentially improving its TTFT, while giving active decode work fewer scheduling boundaries. Smaller chunks offer more opportunities to interleave decoding but may change efficiency and delay completion of the full prefill.
There is no universal best number. The appropriate balance depends on the model, serving engine, accelerator, prompt distribution, output distribution, concurrency and service objective.
| Scheduling direction | Potential benefit | Potential cost | Workload that exposes it |
|---|---|---|---|
| Process a large prefill eagerly | The new request can reach its first token sooner. | Active generations may experience a longer gap between tokens. | One long document arrives while several chats are streaming. |
| Prioritize active decodes | Existing responses can maintain steadier streaming. | New requests may wait longer to complete prefill. | A latency-sensitive interactive service with sustained concurrency. |
| Use smaller prefill chunks | The engine gains more opportunities to mix prompt and generation work. | More fragmented scheduling may affect efficiency and TTFT. | Mixed prompt lengths with strict inter-token latency targets. |
| Use a larger token budget | More work can be included in each scheduling iteration. | Latency behavior may shift even when aggregate throughput improves. | Throughput-oriented serving with enough memory headroom. |
A faster server can still feel worse
A configuration change may increase aggregate tokens processed per second while making the interactive experience less predictable. That is not a contradictory result. It means machine efficiency and per-request latency moved in different directions.
This is why the article on LLM inference benchmark metrics separates throughput from TTFT and inter-token latency. Prefill interference is one of the situations where that separation becomes operationally important.
Median results are not sufficient when interference happens only during large prefills. Track p95 or p99 TTFT and inter-token latency as well. Averages can hide the requests that happened to share the GPU with the largest incoming prompts.
Correlate those latency spikes with prompt length and scheduler activity. GPU utilization near 100 percent does not prove the service is healthy. It only proves that the accelerator is busy.
- Prompt-length distribution, including high-percentile and maximum inputs.
- TTFT by prompt-length bucket rather than one combined average.
- Median and tail inter-token latency for requests already decoding.
- Queue time separately from prefill execution time where telemetry permits.
- Aggregate request and token throughput at each concurrency level.
- KV-cache occupancy, remaining VRAM headroom and preemption or offload events.
RAG and coding assistants are natural stress tests
A basic chat workload may use modest prompts until conversation history grows. RAG and coding systems can introduce large prefills immediately. Retrieved passages, repository context, tool definitions and repeated instructions may all be attached before generation begins.
That makes “average prompt length” especially dangerous. Most requests may be small while a minority of document-heavy requests create the interference users notice.
The same issue can remain hidden in testing if every synthetic request uses an identical prompt. A realistic load test needs variation: short conversational turns, medium prompts and occasional long-context jobs arriving while other sequences are already decoding.
The il.digital capacity guide explains why one GPU has no fixed user count. Prefill interference supplies a concrete example: ten users sending small requests and ten users submitting documents create different schedules on identical hardware.
DiagnosisHow to recognize prefill interference
The strongest symptom is not simply “the server became slow.” Look for a relationship between new long prompts and latency changes in work already underway.
Existing streams pause when a document request arrives
If inter-token latency spikes for active sequences at the same time a large prompt enters prefill, the scheduler may be allowing that prefill to occupy a long execution interval.
TTFT improves while streaming becomes less consistent
A policy that admits prefills aggressively can help new requests begin sooner while making active decode less regular. This is a trade-off, not necessarily a malfunction.
Throughput rises but p95 latency worsens
The server may be completing more total work while distributing GPU time in a way that is less friendly to individual interactive requests.
Single-user tests look excellent
Prefill–decode interference requires competing work. A benchmark with one request at a time cannot reproduce it, regardless of how carefully generation speed is measured.
A useful first-party test would compare unchunked and chunked prefill while long prompts arrive during active generation. The objective would not be to find one universal winner, but to map the latency–throughput trade-off.
Configure the scheduler around the experience you need
For offline processing, maximizing completed work may matter more than a brief generation stall. For interactive chat, smooth streaming and bounded tail latency may justify a different schedule. A shared coding assistant may need both, which means testing with the actual mixture of large prefills and sustained responses.
Do not begin by changing a batching parameter and watching GPU utilization. Start with the service objective, reproduce the workload, and measure which users gain or lose when the scheduler changes.
The important limit is not the longest prompt the model can technically accept. It is the amount of new prompt work the server can admit without making everyone already using the machine feel that their answer has stopped.