There is an appealingly simple upgrade path for a busy local AI server: install another GPU. Twice the accelerators should mean something close to twice the inference capacity. Sometimes that is roughly the direction the system moves. Sometimes the second card mainly gives the first one a very expensive communication partner.
The difference comes from what the second GPU is being asked to do. It can hold part of a model that no longer fits on one device. It can cooperate with another GPU on the same inference request. Or it can host another copy of the model and serve different requests independently.
Those architectures solve different bottlenecks. Before adding another GPU, the useful question is not simply whether two are faster than one. It is what exactly needs to scale: model capacity, request throughput, memory headroom or single-request latency?
- A second GPU can increase capacity without making one individual request twice as fast.
- Tensor parallelism splits work for one model across GPUs, while model replication lets different GPUs serve independent request batches.
- Multi-GPU inference introduces communication between accelerators, so interconnect topology becomes part of inference performance.
- If the model already fits comfortably on one GPU, replication can be more relevant to multi-user throughput than splitting every request across two devices.
- Measure the bottleneck before choosing the scaling architecture.
- A second GPU can solve three different problems
- Splitting a model and replicating a model are not the same thing
- Tensor parallelism makes two GPUs cooperate on the same layers
- The connection between the GPUs becomes part of the machine
- If the model already fits, another copy may be more useful
- More total VRAM does not automatically become one large memory pool
- Will two GPUs make one answer generate faster?
- Start with the bottleneck, then choose the parallelism
- The second GPU should have a job before you buy it
A second GPU can solve three different problems
“Add another GPU” sounds like one upgrade. At the inference layer it can mean several substantially different architectures.
The first problem is capacity: the model or its useful serving state does not fit comfortably on one accelerator. Splitting the model across GPUs can make a larger deployment possible.
The second is throughput: the model fits on one GPU, but one copy cannot serve enough simultaneous traffic. In that case, running additional model replicas can let separate GPUs process separate groups of requests.
The third is latency: you want several accelerators to cooperate on the same request. That can work, but it also introduces synchronization and data movement that a single-GPU request did not have.
| Problem | Possible architecture | What the second GPU does | New constraint |
|---|---|---|---|
| Model does not fit | Tensor or pipeline parallelism | Stores and executes part of the model | GPU-to-GPU communication |
| More users need service | Model replication / data parallel serving | Runs another model instance or serving worker | Load balancing and duplicated model memory |
| Need more KV-cache headroom | Workload-dependent multi-GPU configuration | Provides additional device memory | How the runtime partitions model and cache |
| Need lower request latency | Parallel execution across GPUs | Shares computation for one request | Synchronization can offset compute gains |
Splitting a model and replicating a model are not the same thing
Imagine a server with two GPUs. There are two conceptually different ways to use them.
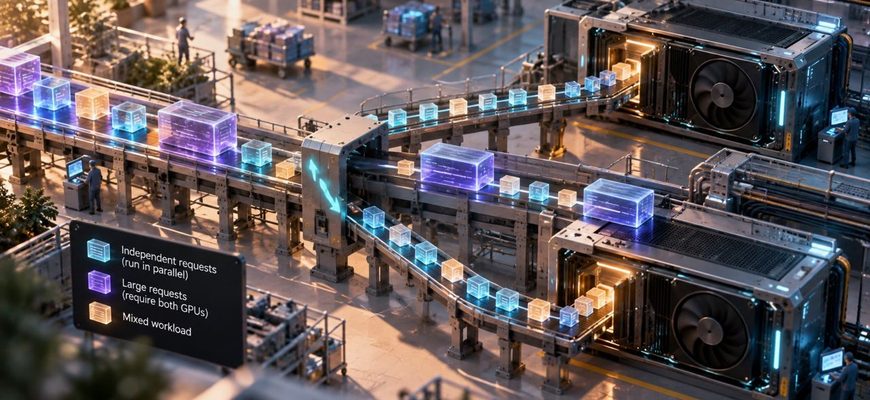
In the first, one model is distributed across both accelerators. Each GPU holds or processes part of the model, and the devices cooperate during inference.
In the second, each GPU runs its own model instance. Request A can go to GPU 1 while request B goes to GPU 2. The GPUs do not need to cooperate on every layer of every request.
The moment one inference request spans multiple accelerators, GPU-to-GPU communication becomes part of the critical path. Partial results may need to move between devices and synchronize before computation can continue. A second GPU therefore adds compute and memory, but it can also add a new data path that did not exist on one GPU.
Tensor parallelism makes two GPUs cooperate on the same layers
Tensor parallelism divides operations within model layers across multiple accelerators. Instead of one GPU executing the entire layer, participating GPUs calculate different portions and exchange the intermediate information required to continue.
The obvious advantage is memory distribution. A model that cannot fit on one GPU may fit when its parameters are divided across several devices.
There can also be performance benefits because more accelerator compute is available. But the computation is no longer local to one card. The GPUs have to communicate repeatedly as inference moves through the network.
Two GPUs do not behave like one hypothetical GPU with twice every specification. They are two physical devices connected by an interconnect. How much useful scaling you get depends partly on how much work can run in parallel and partly on how expensive communication between those devices becomes.
The connection between the GPUs becomes part of the machine
Single-GPU inference keeps most accelerator-side work inside one device. Multi-GPU model parallelism changes that topology.
Now there is a physical route between accelerators. Depending on the platform, communication characteristics can differ substantially, and the serving runtime has to account for that topology when distributing work.
This is why GPU count by itself is an incomplete specification for a multi-GPU inference machine. Two systems with the same number of accelerators can behave differently when the path connecting those accelerators is different.
If the model already fits, another copy may be more useful
Consider a smaller model that fits comfortably on one GPU, including enough memory headroom for the intended context and concurrent requests.
There may be little reason to split every inference request across two GPUs simply because a second card exists. Another option is to load another model instance and route independent requests to it.
This changes the problem from making one model span more hardware to increasing the number of requests the server can work on independently.
For a shared inference service, that distinction is fundamental. The objective may not be to make one user’s answer dramatically faster. It may be to prevent several users from competing for the same accelerator.
If one GPU can already run the model well, the most valuable property of a second GPU may be independence. Two model replicas can give the scheduler two places to send work instead of forcing both accelerators to cooperate on every request.
More total VRAM does not automatically become one large memory pool
This is one of the easiest multi-GPU ideas to misunderstand.
Installing two GPUs with the same amount of VRAM gives the machine more aggregate accelerator memory. It does not mean every application can treat that memory as one transparent, unified allocation.
The inference runtime has to know how to partition the model and associated state across the devices. With replication, the opposite happens: each GPU may need its own copy of the model weights.
That makes the memory arithmetic architecture-dependent.
This matters particularly when context is large. As explained in our guide to context windows and VRAM , model weights are only part of the inference memory budget. Active sequence state and KV-cache requirements matter too.
| Configuration | Model weights | Requests | Primary reason to use it |
|---|---|---|---|
| Single GPU | One complete model | One serving engine handles traffic | Simplicity when model and workload fit |
| Tensor parallel | Partitioned across GPUs | A request uses cooperating devices | Model capacity and distributed execution |
| Pipeline parallel | Layers distributed across stages | Execution moves through GPU stages | Distributing large models across devices |
| Replicated serving | Complete model copy per replica | Requests can be routed independently | Scaling serving throughput |
Will two GPUs make one answer generate faster?
Possibly, but that is not a safe assumption.
Distributed execution adds compute resources while also creating communication and synchronization work. Whether the balance improves single-request latency depends on the model, hardware topology, runtime, parallelism strategy and workload.
This is exactly the kind of situation where a benchmark needs more than tokens per second.
The useful LLM benchmark should distinguish time to first token, generation behavior, aggregate throughput and concurrency. A multi-GPU configuration can improve one of those dimensions without improving all of them.
- Check model fit: determine whether model weights and the required inference state already fit comfortably on one GPU.
- Check concurrency: establish whether the real problem is too many simultaneous requests.
- Check latency: identify whether TTFT, decode latency or queueing is actually failing.
- Check VRAM pressure: separate weight capacity from KV-cache and runtime memory pressure.
- Check topology: understand how the GPUs communicate before assuming distributed execution will scale cleanly.
Start with the bottleneck, then choose the parallelism
The architecture becomes much clearer when the problem is stated before the solution.
| If your actual problem is… | Investigate first | Multi-GPU direction to evaluate |
|---|---|---|
| The model cannot fit on one GPU | Weight memory and required inference headroom | Tensor or pipeline parallelism |
| Users are queueing | Concurrency, throughput and scheduler behavior | Independent replicas / request distribution |
| Long contexts exhaust memory | KV-cache usage and active sequence lengths | Memory-aware partitioning or workload changes |
| One request is too slow | Prefill, decode and communication cost | Benchmark distributed execution before committing |
A useful first-party experiment would compare the same two-GPU machine in three modes: one GPU, a model distributed across both GPUs, and two independently served replicas where the model fits on each card.
The second GPU should have a job before you buy it
Multi-GPU inference becomes easier to reason about once “more GPUs” stops being treated as a single strategy.
If the model is too large, the second accelerator can become part of the model. If traffic is the problem and the model fits independently on each card, the second accelerator can become another place to send requests. If latency is the problem, the answer has to come from measurement because distributed compute also introduces distributed communication.
So do not start capacity planning with the empty PCIe slot. Start with the failing metric. Once you know whether the machine is short on memory, throughput or latency headroom, you can decide what the second GPU is actually supposed to do.