AI Infrastructure
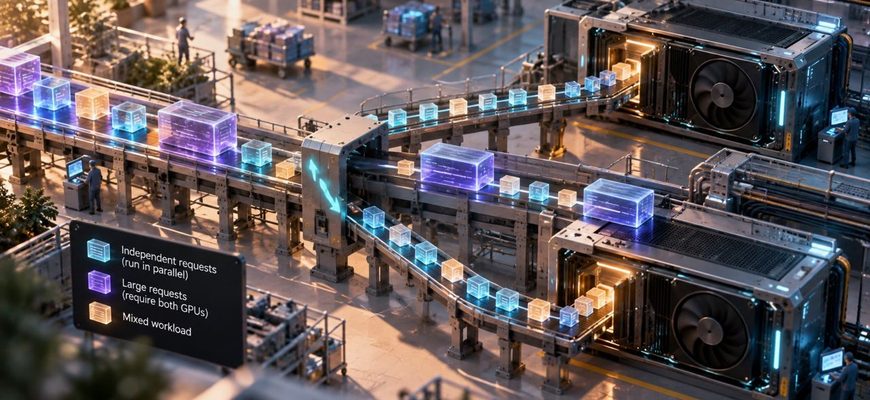
There is an appealingly simple upgrade path for a busy local AI server: install another GPU. Twice the accelerators should mean something close to twice
A local LLM produces 100 tokens per second. On paper, that sounds fast. Then a real user sends a long prompt and waits several seconds before anything