A local LLM produces 100 tokens per second. On paper, that sounds fast. Then a real user sends a long prompt and waits several seconds before anything appears on screen.
Nothing is necessarily wrong with the benchmark. The problem is that it may have measured a different part of the system from the one the user actually experiences.
LLM inference does not have one universal speed. A request moves through several distinct phases: it arrives, may wait for capacity, its input is processed, the first token appears, and then the rest of the response is generated. Add concurrent users and the behavior can change again.
A single tokens-per-second number compresses all of that into something pleasantly simple. Sometimes, it compresses away the part that matters.
- Tokens per second is not a complete measure of LLM responsiveness. A system can generate quickly after making the user wait for the first token.
- TTFT, ITL, throughput and end-to-end latency describe different parts of inference. They should not be treated as interchangeable.
- Concurrency changes the benchmark. A fast single-request test does not tell you how the same server behaves under real traffic.
- Prompt length matters. A benchmark using short synthetic prompts may say little about a workload built around long documents or large context windows.
- The useful benchmark is the one that resembles the workload you actually intend to run.
- There Is No Single “LLM Speed”
- Tokens per Second Can Be Technically Correct and Practically Misleading
- TTFT Measures the Part Users Notice First
- ITL Tells You What Happens After the Answer Starts
- Throughput Answers a Different Question
- Concurrency Is Where a Benchmark Starts Becoming a Service
- Your Prompt Distribution Is Part of the Hardware Test
- Why Synthetic Benchmarks Still Matter
- The Benchmark Should Match the User
- Do Not Ignore the Percentiles
- Cold Starts Can Distort the Result Too
- What a Useful LLM Benchmark Should Record
- A Better Way to Compare Two Inference Systems
- il.digital Lab
- Question
- Why this experiment matters
- Read Benchmark Headlines Backwards
- The Fastest Number Is Rarely the Most Useful One
There Is No Single “LLM Speed”
Consider what happens after someone presses Send in an AI application.
These stages do not stress the system in exactly the same way.
Processing the prompt, often called prefill, takes the input tokens and builds the internal state required for generation. Once that work is done, the model enters decode, repeatedly producing new tokens.
Then there is the serving layer around the model: scheduling, batching, concurrent requests, cache management and potentially queueing before inference even starts.
This gives us several clocks rather than one.
Modern serving benchmark tools reflect this distinction. SGLang’s serving benchmark, for example, reports time to first token, inter-token latency, time per output token and throughput rather than reducing serving performance to a single number.
That is a clue about how production inference should be measured: the metric depends on the question.
Tokens per Second Can Be Technically Correct and Practically Misleading
Tokens per second is useful. If you want to know how quickly a model generates once decoding is underway, generation rate tells you something important about the machine and runtime.
But imagine two systems.
| System | Before First Token | Generation | User Experience |
|---|---|---|---|
| System A | Short wait | Moderate | Starts responding quickly and streams steadily |
| System B | Long wait | Fast | Feels frozen, then generates very quickly |
System B could win a benchmark focused narrowly on decode speed while feeling slower in an interactive application.
The numbers do not contradict each other. They describe different moments in the request.
A benchmark is not useful because the number is accurate. It is useful when the number measures the behavior you care about.
This becomes especially important when comparing published results. “Tokens per second” might describe output throughput across many requests, generation speed for one request, or another measurement with different batching and workload assumptions.
Two values carrying the same unit are not automatically measuring the same experiment.
TTFT Measures the Part Users Notice First
For an interactive assistant, time to first token (TTFT) is one of the most visible latency metrics.
The user has already finished typing. Nothing is happening on screen. The system may be processing thousands of input tokens, waiting behind other requests, or performing other work, but from the user’s perspective the interface is simply waiting.
TTFT captures the time between sending the request and receiving the first generated token.
That makes it particularly relevant for chat, coding assistants and other interactive workloads.
It is also sensitive to conditions that a simple decode benchmark may barely expose.
A longer input requires more prompt processing. Concurrent traffic can introduce scheduling and queueing. Runtime behavior and batching can change how quickly a request begins producing output.
A machine can therefore have excellent generation speed and disappointing TTFT at the same time.
[INTERNAL LINK: Why a Local LLM Is Slow: How to Find the Real Inference Bottleneck]
ITL Tells You What Happens After the Answer Starts
The first token solves only the first part of the experience.
Once text begins streaming, the gaps between tokens determine whether the response feels fluid or hesitant. Inter-token latency (ITL) measures those gaps.
This matters because averages can hide interruptions.
A response may stream smoothly most of the time while occasionally pausing long enough for the user to notice. Looking only at a mean value can make those tail events almost invisible.
That is why latency distributions matter.
Average latency describes the average request. Users also encounter the slow tail.
If a service matters interactively, percentiles such as P95 or P99 can reveal behavior that an average conceals. The relevant percentile and target depend on the application and its service requirements.
This is not specific to LLMs. Production systems have always had to care about tail latency. Generative AI simply makes the problem more visible because users watch the output arrive token by token.
Throughput Answers a Different Question
If TTFT and ITL describe parts of the individual experience, throughput asks how much useful work the infrastructure can perform over time.
That matters enormously when a model moves from a developer’s workstation to a shared service.
A single user might care primarily about responsiveness. An operator serving hundreds of requests also has to care about how effectively expensive accelerator capacity is being used.
These goals can pull in different directions.
Batching more work together can improve hardware utilization and aggregate throughput. But under some serving conditions, waiting to assemble or schedule more work can affect latency.
The interesting benchmark is therefore rarely “How fast can this GPU go?”
It is closer to:
How much traffic can this system serve while keeping latency within the limits the application requires?
That question joins software behavior directly to physical infrastructure.
Throughput determines how much work one accelerator can absorb. Latency requirements constrain how aggressively that accelerator can be shared. Together, they influence how many GPUs, how much VRAM and how much server capacity a service actually needs.
Concurrency Is Where a Benchmark Starts Becoming a Service
A benchmark with one request at a time can be useful for isolating model behavior.
It is not automatically a realistic serving benchmark.
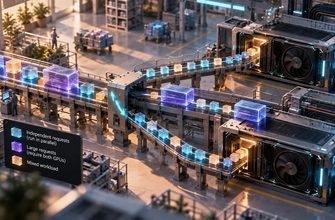
When multiple requests arrive, the inference runtime has to decide which sequences run, how they are batched, how memory is allocated and how available compute is divided.
At that point, a GPU is no longer executing a neat laboratory request. It is managing demand.
Current SGLang benchmarking guidance makes this distinction explicit. Its online serving benchmark sends requests at controlled rates with configurable concurrency and measures TTFT, ITL and throughput. Its documentation separately describes offline throughput tests that remove HTTP overhead and are intended to measure maximum engine throughput.
Those are both valid experiments.
They answer different questions.
| Benchmark | Useful For | What It May Miss |
|---|---|---|
| Single request | Basic latency and generation behavior | Queueing and contention |
| Offline throughput | Engine-level maximum throughput | Real serving overhead and user-facing latency |
| Fixed concurrency | Behavior with several active requests | Real arrival patterns if workload is too synthetic |
| Online load test | Production-like latency and throughput | Realism if prompts and arrival rates do not match the application |
This distinction explains a common surprise: the same hardware can look extraordinary in a throughput benchmark and much less impressive once a latency target is imposed.
Your Prompt Distribution Is Part of the Hardware Test
Hardware is only half of an inference benchmark.
The other half is the workload.
A server processing 200-token prompts is solving a different physical problem from one processing 16,000-token prompts.
Longer inputs require more prompt processing. They also create more sequence state, including KV-cache demand during inference. Under concurrency, that memory pressure is multiplied across active sequences.
[INTERNAL LINK: Why LLM Context Windows Consume So Much VRAM]
This is why benchmark results without workload details are difficult to interpret.
At minimum, useful context includes input length, output length, concurrency or request rate, model precision or quantization, runtime configuration and hardware.
Without those details, a large throughput number may be impressive but hard to apply to another system.
A prompt is not an abstract piece of text once it reaches the server. It becomes tokens to process, tensors to move, cache state to store, memory bandwidth to consume and GPU time that cannot simultaneously be given to something else.
Why Synthetic Benchmarks Still Matter
None of this makes synthetic benchmarks useless.
Controlled workloads are essential when the goal is comparison. Keeping input lengths, output lengths and request patterns fixed makes it easier to isolate what changed between two GPUs, runtimes or configurations.
The problem begins when a controlled benchmark is interpreted as a prediction for a workload it was never designed to represent.
A synthetic test should answer a clearly defined question.
A production test should represent the application.
The strongest evaluation often needs both.
The Benchmark Should Match the User
Different AI applications need different performance priorities.
| Workload | Metrics to Watch Closely | Why |
|---|---|---|
| Interactive chat | TTFT, ITL, tail latency | The user is waiting and watching the response stream |
| Coding assistant | TTFT, ITL, prompt-length behavior | Large code context can make prefill important |
| Batch generation | Throughput, total completion time | Aggregate work may matter more than immediate first-token response |
| Shared inference API | Throughput, TTFT, ITL, P95/P99 latency, concurrency | Capacity and user experience have to coexist |
| Long-document analysis | TTFT, memory use, prompt throughput | Large inputs shift pressure toward prefill and memory |
The table is not a universal ranking. Real applications can combine several of these patterns.
Its purpose is to force the useful question before the benchmark begins:
What behavior are we trying to preserve?
Do Not Ignore the Percentiles
Suppose the average TTFT looks excellent.
That does not tell you whether a smaller portion of requests waited dramatically longer.
This is where percentiles become useful. Median latency describes the middle of the distribution. P95 and P99 move attention toward the slower tail.
That tail can reveal queueing, workload variation or contention that disappears inside a mean.
Production benchmarking should therefore resist the temptation to reduce an entire run to one average number.
A useful report describes a distribution.
Cold Starts Can Distort the Result Too
Another easy mistake is mixing cold-start behavior with steady-state performance without saying so.
The first run after startup may involve work that later requests do not encounter in the same way: initialization, memory allocation, cache population or runtime-specific compilation and setup.
That behavior can be important. A service that frequently scales from zero may care deeply about cold starts.
A continuously running inference server may care more about warmed-up steady state.
The mistake is not measuring either one.
The mistake is failing to say which one was measured.
What a Useful LLM Benchmark Should Record
For a serving benchmark, record enough information that another person can understand what the number actually represents.
- Model: exact model and version.
- Precision: data type or quantization configuration.
- Hardware: GPU, VRAM and relevant system configuration.
- Runtime: inference engine and version.
- Input length: preferably a distribution for realistic traffic.
- Output length: again, representative of the application.
- Concurrency or arrival rate: how much simultaneous demand was applied.
- TTFT: including useful percentiles.
- ITL or TPOT: how generation behaves after the first token.
- Throughput: clearly state whether it means requests, input tokens, output tokens or total tokens per second.
- End-to-end latency: where complete-request time matters.
- Memory behavior: VRAM usage and cache pressure when relevant.
Not every experiment needs every metric.
But every published number needs enough context to explain what was measured.
A Better Way to Compare Two Inference Systems
Suppose you want to compare two GPUs or two serving runtimes.
Running one prompt on each and recording tokens per second is a useful first check. It is not the end of the experiment.
A stronger comparison would hold the model and workload constant, then gradually increase demand.
Start with one request.
Measure TTFT and generation latency.
Then increase concurrency or request rate while keeping prompt characteristics consistent.
Watch what happens to throughput and latency together.
Eventually, the system will approach a region where additional demand produces less useful throughput improvement while latency rises significantly. The exact behavior depends on the model, runtime, hardware and workload.
That curve is often more informative than the largest tokens-per-second number you can extract from the machine.
It shows where a fast GPU becomes a constrained service.
il.digital Lab
Question
How different does the same GPU look when we benchmark maximum throughput versus interactive serving performance?
Why this experiment matters
The interesting result is not which configuration produces the largest isolated number. It is where each configuration begins trading responsiveness for additional throughput.
That would turn an abstract benchmark discussion into something visible: the point at which one physical GPU stops behaving like a fast personal machine and starts behaving like a busy shared service.
No benchmark values are included here because il.digital has not yet supplied first-party measurements for this experiment.
[VISUAL: dual-axis chart concept showing throughput rising with concurrency while TTFT also begins to rise, with the transition region clearly marked]
Read Benchmark Headlines Backwards
When you see an impressive inference benchmark, the first question should not be whether the number is high.
Ask what had to be true for that number to exist.
How long were the prompts? How much text was generated? Was the test offline or serving real requests through an endpoint? Was it one user or hundreds of concurrent sequences? Was the machine warm? Is the reported number an average, median or tail percentile? Does “tokens per second” refer to one sequence or aggregate output across the system?
Those details are not footnotes to the benchmark.
They are the benchmark.
There is no useful answer to “How fast is this LLM server?” until you define what the server is being asked to do.
The Fastest Number Is Rarely the Most Useful One
Peak throughput tells you something real about a machine. So does single-request generation speed. So do TTFT, ITL and end-to-end latency.
The mistake is asking one of them to describe the whole system.
A production LLM server lives at the intersection of model behavior, GPU compute, memory, scheduler decisions, prompt length and human patience. Change the workload and the same hardware can tell a very different performance story.
So before optimizing your next benchmark, define the experience you are trying to protect. Then reproduce that experience as closely as you can under controlled load.
The best benchmark is not the one that makes the GPU look fastest. It is the one that tells you when your users will start waiting.