- Why AI Agents Repeat Actions After Timeout Errors
- One Customer Request, Two Execution Attempts
- The agent requests an action
- The order is created
- The acknowledgment disappears
- The workflow reaches a timeout
- The action is requested again
- The Failure Happens Outside the AI Model
- Where the Uncertainty Exists
- Idempotency: How to Prevent Duplicate Agent Actions
- One Intent, Two Effects
- One Intent, One Effect
- Why Checking the Database Before Retrying Is Not Enough
- A Local Lock Cannot Guarantee an External Result
- 5 Best Fixes for Unsafe AI Agent Retries
- Give Every Business Action a Stable Identity
- Store Execution State Durably
- Protect Against Concurrent Execution
- Carry the Idempotency Key to the Final System
- Make Uncertain Outcomes Visible
- Not Every AI Agent Tool Should Be Retried the Same Way
- What Happens When an AI Agent Retries a Task in n8n?
- Durable Workflows Are Not Automatically Exactly-Once
- Four Metrics That Reveal Unsafe AI Agent Retries
- A Practical Test: Lose the Reply, Not the Order
- Frequently Asked Questions
- A Reliable AI Agent Must Know What Already Happened
Why AI agents repeat actions after timeout errors is not always a question of the model making a bad decision. Sometimes the requested action succeeds, the confirmation disappears, and an otherwise reasonable retry creates a second real-world effect.
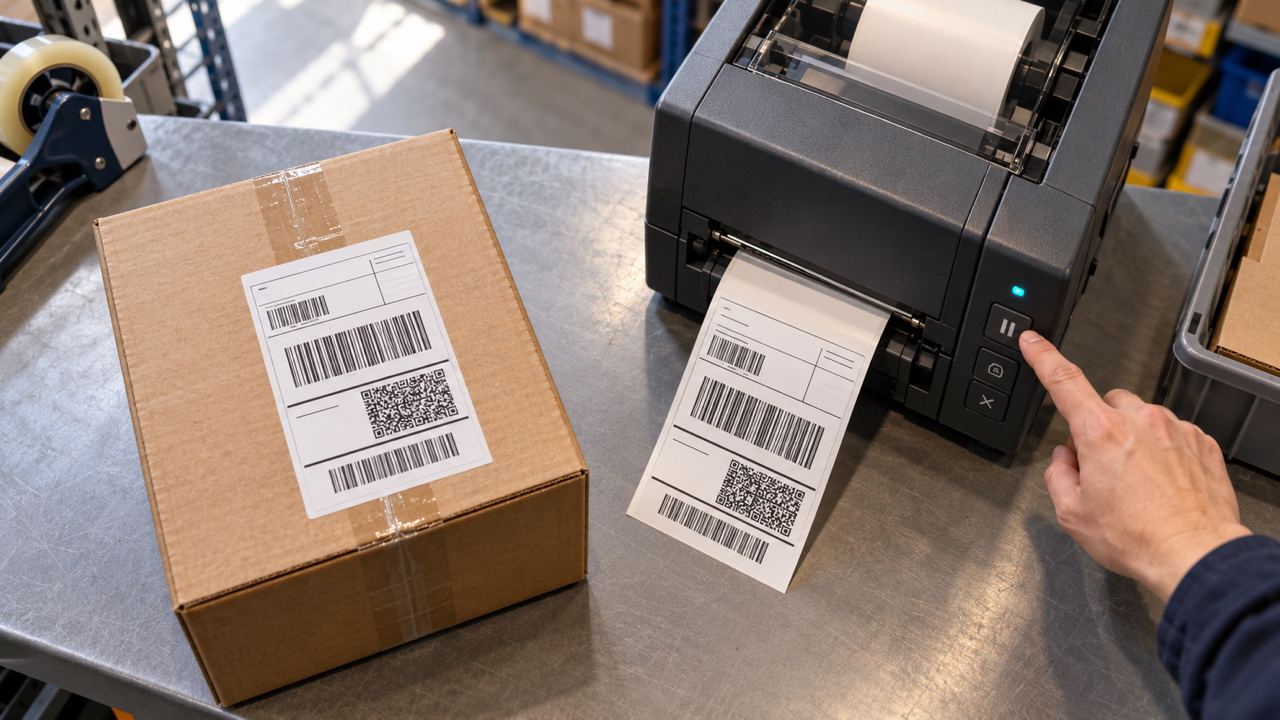
Imagine an AI agent processing a customer order. It sends the order to a warehouse system. The database records it successfully. A shipping label is printed.
Then something goes wrong.
The agent never receives confirmation that the order was created. Its workflow reaches a timeout and attempts the operation again.
The warehouse receives another request. Without duplicate protection, it creates another order and prints another label.
The customer asked for one shipment. The automation may have created two.
This failure reveals something important about AI automation: reliable execution depends not only on what an agent decides to do, but also on how software records completed actions, handles network failures and recovers from uncertainty.
- A timeout does not prove that an operation failed. The receiving system may have completed it before the response disappeared.
- Retrying an operation can improve reliability, but some actions create duplicate orders, payments, messages or database records.
- Idempotency keys help receiving services recognize repeated attempts to perform one logical operation.
- Durable state and concurrency protection are necessary when multiple workers can execute or retry the same task.
- Reliable AI automation requires measuring actual external effects, not just successful workflow executions.
Why AI Agents Repeat Actions After Timeout Errors
The most dangerous timeout is sometimes the one that happens after an operation has already succeeded.
Consider a workflow that processes incoming customer requests.
An AI model reads a message, extracts the requested product and quantity, and proposes an order-creation action. Application code validates the information before sending it to the order API.
The order service receives the request and writes a new record to its database.
That is a real, persistent change.
But the response confirming success must still travel back across the network.
If the connection drops, the requesting workflow might never receive the new order ID.
It can only observe that the request did not complete normally from its perspective.
Understanding why AI agents repeat actions after timeout failures begins with this distinction.
The server may know the operation succeeded. The agent’s workflow may know only that confirmation never arrived.
If the workflow retries without a way to identify the original operation, the receiving system may execute the action again.
One Customer Request, Two Execution Attempts
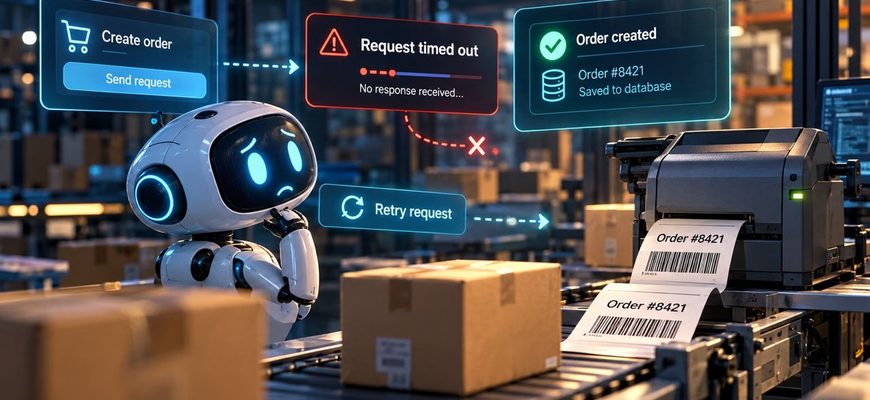
The failure can be broken into five events. None requires the model to hallucinate or misunderstand the customer’s instructions.
The agent requests an action
The workflow sends an order-creation request to an external API.
The order is created
The receiving service validates the request and commits the order to its database.
The acknowledgment disappears
The server completes the operation, but its success response never reaches the worker.
The workflow reaches a timeout
The caller cannot establish whether the operation completed.
The action is requested again
The retry reaches the API. Without duplicate protection, a second order may be created.
This is a classic distributed-systems problem. Two components can have different information about the same operation because the message connecting them was lost.
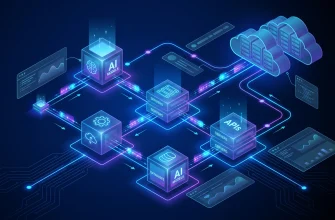
Simplified execution path. The problem appears when the receiving service cannot recognize the second request as another attempt to perform the original operation.
The Failure Happens Outside the AI Model
An AI agent usually does not write directly into a warehouse database.
The model proposes a structured tool call. Application software validates the request, checks permissions and executes the operation.
Our earlier article on how AI agents actually use tools explains this architecture in detail.
Once the tool call is approved, ordinary infrastructure takes over.
A worker process sends a request over a network. Another service receives it, performs an operation, writes persistent state and prepares a response.
Every boundary creates opportunities for interrupted communication.
Where the Uncertainty Exists
The AI model runs on compute hardware. The orchestration worker consumes CPU time and memory. The tool request travels through a network connection.
The receiving application executes on another process or machine and may write data to persistent storage.
If the operation succeeds but its acknowledgment disappears, the requesting worker and the receiving server no longer have the same information about the result.
More GPU memory or a faster model does not solve this problem. The failure concerns communication, persistent state and the relationship between an operation and its confirmation.
Idempotency: How to Prevent Duplicate Agent Actions
One of the most useful tools for preventing duplicate operations is idempotency.
An idempotent operation can be applied repeatedly without producing additional effects beyond the first successful application.
Consider a customer asking for one new order.
Instead of treating every HTTP request as an unrelated action, the workflow assigns a stable identifier to the logical operation.
That identifier is an idempotency key.
The key stays the same across retries of the same intended action.
A genuinely new order receives a different operation identity.
These values are illustrative.
The important property is that the receiving system can recognize both attempts as requests for the same business operation.
When an API correctly supports idempotency, a repeated request can be resolved without creating another independent effect.
The exact response depends on the API contract. A service may return a stored result, identify the existing resource or handle an in-progress operation according to its documented rules.
Important: An idempotency key is not a magical HTTP header. The receiving service must actually implement and enforce duplicate protection. Sending an arbitrary key to an API that ignores it changes nothing.
Stripe provides a familiar real-world example. Its API supports idempotency for appropriate operations, allowing clients to recover from certain connection failures without unintentionally repeating the same business effect.
However, idempotency behavior varies by provider, endpoint and API version.
Always check the provider’s documentation, including key expiration, parameter matching and handling of concurrent requests.
One Intent, Two Effects
The first API request creates order A.
Its acknowledgment is lost.
The workflow retries the same action.
The receiving service interprets the retry as an entirely new request.
It creates order B.
Final result: two orders.
One Intent, One Effect
The first API request uses a stable operation key.
The service creates order A and records the operation.
The acknowledgment is lost.
The retry uses the same key.
The service recognizes the previous operation instead of creating another order.
Final result: one order.
Why Checking the Database Before Retrying Is Not Enough
There is a simple-looking solution to duplicate operations: check whether the order already exists before creating it.
This can help, but it is not automatically safe under concurrency.
Imagine two workers receive requests for the same logical operation at nearly the same moment.
Both check the database.
Neither finds an existing order.
Both create one.
The check itself was correct. The problem was that the check and the subsequent write were not protected as one coordinated operation.
Reliable implementations use appropriate database uniqueness constraints, conditional writes, atomic operations or coordinated idempotency records.
The AWS Well-Architected guidance for agentic systems discusses these patterns, including deterministic operation keys and conditional database writes.
A Local Lock Cannot Guarantee an External Result
Consider an even harder failure.
Your workflow reserves an operation key, sends a request to an external API and the external service succeeds.
Then the worker crashes before recording the successful result.
After restarting, the workflow may find an unfinished local operation without knowing whether the external effect happened.
A local lock cannot solve this uncertainty by itself.
The system may need receiver-side idempotency, stable business identifiers, reconciliation against the external service or another documented recovery protocol.
If the external API offers neither duplicate protection nor a reliable way to inspect the outcome, automatic retries may be unsafe.
5 Best Fixes for Unsafe AI Agent Retries
Preventing duplicate actions is not simply a matter of disabling retries.
Retries are useful. They allow applications to recover from temporary network problems, overloaded services and interrupted workers.
The goal is to make recovery safe.
If you are investigating why AI agents repeat actions after timeout errors in production, these five design decisions are a practical starting point.
Give Every Business Action a Stable Identity
Define what counts as one logical operation. A customer order, refund or email delivery should have an identifier that survives worker restarts and retries. Do not create a fresh identifier every time the network request is attempted.
Store Execution State Durably
Record whether an operation is pending, running, completed or unresolved. Process memory alone disappears when a worker crashes. Persistent state allows recovery logic to distinguish unfinished work from previously confirmed results.
Protect Against Concurrent Execution
Multiple workers must not independently claim the same operation. Use suitable database constraints, conditional writes or transactional mechanisms to enforce uniqueness at the point where it matters.
Carry the Idempotency Key to the Final System
When a receiving API supports idempotency, pass the same logical operation key on every retry. If the provider lacks that capability, design a reconciliation procedure before repeating a potentially irreversible action.
Make Uncertain Outcomes Visible
Record operation IDs, attempt IDs, failure types and external results. Use bounded retries with suitable backoff. Send unresolved high-impact actions for human review rather than silently creating another operation.
One more boundary: Idempotency records may expire. If a retry arrives after the receiving service’s protection window, the same key may no longer identify the original action. Retention rules must be considered alongside realistic retry and redelivery windows.
Not Every AI Agent Tool Should Be Retried the Same Way
Reading data and changing data are different kinds of operations.
Repeating a product lookup usually does not create another product.
Repeating an order-creation request, however, can create a second order.
This distinction helps explain why AI agents repeat actions after timeout failures with very different consequences depending on the tool being called.
| Tool Action | Risk on Retry | Safer Approach |
|---|---|---|
| Search customer records | Usually no duplicate write, although repeated calls consume resources. | Bounded retries with appropriate timeouts and backoff. |
| Create an order | Multiple orders may be created. | Stable operation identity and enforced idempotency. |
| Send an email | A customer may receive the same message twice. | Delivery-state tracking, provider-supported deduplication where available, and reconciliation of uncertain sends. |
| Issue a payment or refund | Duplicate financial effects may occur. | Provider-supported idempotency and verification of final transaction state. |
| Update a database record | Setting a fixed value may be safe, but repeating an increment may not be. | Conditional updates, version checks or stable operation identifiers. |
| Delete a resource | The final state may be repeatable, but related side effects can still occur. | Verify resource identity, inspect API behavior and require approval when appropriate. |
The HTTP method is a useful starting point, but it does not describe the complete business effect of an operation.
One API call may trigger several downstream actions: a database write, an email, a warehouse job and a webhook.
Duplicate protection should cover the real-world effect that matters, not merely the initial request.
This is why good AI automation design separates model decisions from deterministic validation, permissions and execution rules.
What Happens When an AI Agent Retries a Task in n8n?
Visual workflow builders make automation easier to construct, but they do not remove distributed-systems failures.
An HTTP request can still time out after the receiving service successfully completes an operation.
n8n supports retry behavior for failing nodes, including temporary API errors.
This can improve availability, provided the operation is safe to repeat.
There is an important distinction between one workflow execution and one business action.
n8n exposes execution identifiers, but a manually retried or newly triggered workflow can have a different execution ID.
If duplicate protection must extend across separate workflow runs, an identifier based only on the current execution may not be sufficient.
A stable business operation ID, such as the original customer order ID, can be a better basis for identifying the intended action.
n8n discusses this distinction in its guide to API idempotency .
Readers new to the platform can start with our introduction to n8n and AI automation .
Durable Workflows Are Not Automatically Exactly-Once
A durable workflow engine can remember completed steps and resume after a crash.
This is particularly useful for long-running AI agents that interact with several external systems.
However, external activities can still be attempted more than once when their outcome is uncertain.
Temporal’s activity documentation describes retries following timeouts and worker failures.
Recovering workflow state and preventing duplicate business effects are related, but separate guarantees.
Four Metrics That Reveal Unsafe AI Agent Retries
A completed workflow does not necessarily mean the correct number of business actions occurred.
An automation may report success while an external service records two orders, sends two messages or performs another action twice.
Understanding why AI agents repeat actions after timeout errors is easier when each logical operation can be connected to its individual execution attempts.
How frequently operations require another attempt after a failure or timeout.
How often an existing operation identifier prevents repeated execution of the same action.
Operations whose external result cannot yet be confirmed.
The number of real orders, messages, refunds or other effects per logical request.
The final measurement is especially important.
A workflow may report that the agent completed one task while an external application records two separate effects.
Monitoring should connect the original business request to the records created in the systems that actually performed the work.
A Practical Test: Lose the Reply, Not the Order
The failure described in this article can be reproduced in a controlled local environment.
A useful experiment would place a small order API behind a test proxy and deliberately interrupt the response after the server commits a database write.
The workflow would then retry the same logical operation.
Two configurations could be compared: ordinary retries and retries protected by an enforced idempotency key.
One local workstation or small server, with CPU, RAM, persistent storage and a test network.
Workflow runner, mock order API, database and a controllable HTTP fault-injection proxy.
Whether the receiving operation enforces a stable idempotency key.
Drop the API acknowledgment after the order is committed.
Request attempts, actual database order count, duplicate suppression events and unresolved outcomes.
A reproducible demonstration of the difference between retrying a request and repeating its real-world effect.
This is a proposed experiment. It does not represent a first-party benchmark already performed by il.digital.
Frequently Asked Questions
Why do AI agents repeat actions after timeout errors?
The workflow may not receive confirmation that an external operation succeeded. A retry mechanism can send the same request again, potentially duplicating an action that was already completed.
Does idempotency prevent every duplicate action?
No. Protection depends on stable operation identity, correct server-side enforcement, concurrency behavior, retention windows and the receiving API’s actual contract.
Is retrying a POST request always unsafe?
No. Some POST endpoints provide idempotency guarantees or other duplicate protection. The correct retry policy depends on the documented behavior of the receiving service.
Can human approval prevent duplicate actions?
Human approval can determine whether an operation should be authorized, but it does not automatically prevent a previously approved operation from being retried after a timeout. Approval and idempotency solve different problems.
Do local AI agents experience the same problem?
Yes. A locally hosted model can call external tools through a workflow runner. Network, process and storage failures still apply even when inference runs entirely on local hardware.
What is the best way to prevent duplicate API calls?
Assign a stable identity to each logical operation, persist execution state, enforce duplicate protection atomically and use the receiving API’s documented idempotency mechanism where available. Uncertain outcomes should be reconciled rather than blindly retried.