A local LLM being slow does not automatically mean that your GPU is too weak. The model may be spilling into system RAM, the CPU may be doing more work than expected, a long prompt may be expensive to process, or several requests may be competing for the same memory.
The first useful question is therefore not “What hardware should I buy?” It is “Which stage of inference is actually slow?”
A model that takes 20 seconds before producing its first token has a different problem from one that starts immediately but generates text slowly. A system that is fast with a short chat and sluggish with a large document has another problem again.
This guide provides a practical way to diagnose those differences before changing models, quantization settings, or hardware.
- Local LLM performance is not one number
- Start with time to first token versus generation speed
- Case 1: long pause, then reasonably fast output
- Case 2: output starts quickly but tokens arrive slowly
- Case 3: short prompts are fast, long prompts are slow
- Check whether the model really fits where you think it does
- GPU offloading can completely change performance
- Why partial offloading can feel disproportionately slow
- VRAM capacity and GPU compute are different bottlenecks
- System RAM can be the bottleneck too
- Memory mapping changes how RAM usage looks
- Watch for swapping
- Context length can turn a fast configuration into a slow one
- RAG can create a prompt-processing problem
- Quantization changes more than disk size
- Concurrency changes the calculation
- A practical local LLM bottleneck test
- 1. Start with one model
- 2. Use a short prompt
- 3. Verify model placement
- 4. Repeat with a realistic long prompt
- 5. Reduce the model size
- 6. Reduce context
- 7. Eliminate concurrency
- What the symptoms usually suggest
- When a hardware upgrade actually makes sense
- The practical rule: change one constraint at a time
Local LLM performance is not one number
When people describe a model as “slow,” they often combine several separate delays into one impression.
For local inference, it is useful to distinguish at least four stages:
| Stage | What you experience | Common constraints |
|---|---|---|
| Model loading | Delay before the model is ready | Storage, RAM, VRAM allocation, model size |
| Prompt processing | Long wait after submitting a large prompt | Prompt length, compute, memory bandwidth, backend |
| Token generation | Answer appears slowly token by token | Model size, memory bandwidth, GPU/CPU execution, offloading |
| Concurrent serving | Performance degrades when more requests arrive | VRAM, KV cache, batching, parallel sequences |
These stages can behave very differently on the same computer. Diagnosing local AI performance becomes much easier once you determine which one is causing the problem.
Start with time to first token versus generation speed
The simplest diagnostic is to observe what happens immediately after you submit a request.
Case 1: long pause, then reasonably fast output
If the model spends a long time doing nothing visible and then generates the answer at an acceptable rate, investigate prompt processing and model loading first.
A long input must be processed before generation can begin. Sending a large document, a long conversation history, or many retrieved RAG passages can therefore increase the delay before the first generated token even when subsequent generation is reasonably fast.
The model may also have been unloaded between requests. Ollama supports keeping models resident in memory specifically so repeated requests do not always require a fresh load. Its API exposes a keep_alive parameter for controlling this behavior.
Case 2: output starts quickly but tokens arrive slowly
This points more strongly toward the generation path.
Possible causes include a model that is large relative to the available hardware, CPU-heavy inference, insufficient GPU offloading, memory bandwidth limitations, or a configuration in which data must repeatedly move between CPU and GPU memory.
Case 3: short prompts are fast, long prompts are slow
Context is likely part of the problem.
Longer active sequences increase the amount of work involved in prompt processing and increase the memory required for the KV cache. The exact cost depends on model architecture, cache representation, runtime settings, and hardware.
This is why testing only with “Hello” is a poor way to evaluate a local AI machine. Test with inputs that resemble the workload you actually intend to run.
Check whether the model really fits where you think it does
One of the most common local-inference mistakes is assuming that a model “fits on the GPU” because its model file is smaller than the GPU’s VRAM capacity.
The model weights are only part of the inference memory budget.
A useful conceptual model is:
memory requirement ≈ model weights + KV cache + runtime buffers + temporary allocations + overhead
This is not an exact sizing formula. Actual allocation depends on the runtime, architecture, context configuration, cache data type, concurrency, backend, and other settings.
But it explains an important practical point: filling nearly all available VRAM with weights leaves little headroom for inference.
A configuration can therefore work with a short prompt and become constrained when context grows.
GPU offloading can completely change performance
Local inference engines such as llama.cpp can place model layers on accelerator devices instead of executing everything through the CPU.
The current llama.cpp command-line interface exposes --gpu-layers / --n-gpu-layers for controlling the maximum number of layers stored in VRAM. It also supports selecting devices for offloading.
The important practical distinction is between three broad configurations:
| Configuration | What it means | Typical implication |
|---|---|---|
| Full or near-full GPU execution | Most relevant model data fits in VRAM | Usually the most responsive arrangement on a capable supported GPU |
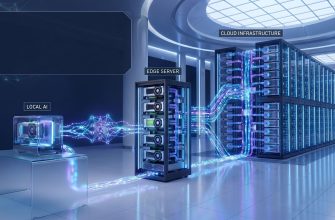
| Partial GPU offload | Some model work remains on the CPU/system-memory side | Allows larger models but introduces a performance trade-off |
| CPU inference | Model primarily uses system RAM and CPU | Capacity can be high with enough RAM, but interactive generation may be substantially slower |
The exact performance difference cannot be predicted from the layer count alone. CPU speed, memory bandwidth, GPU architecture, model architecture, backend implementation, and quantization all matter.
RECOMMENDATION: If a model is unexpectedly slow, verify its actual placement before assuming that GPU acceleration is working as intended.
Why partial offloading can feel disproportionately slow
Suppose a quantized model is slightly too large for your available VRAM. Moving part of the workload to system memory may allow it to run rather than fail with an out-of-memory error.
That is useful, but capacity and speed are different questions.
System RAM is separate from discrete GPU VRAM on a conventional PC. Mixed CPU/GPU execution can therefore involve slower compute paths and movement across the system interconnect rather than keeping the relevant workload entirely on the GPU.
The result is an important local-AI trade-off:
A model that can run is not necessarily a model that runs at a useful interactive speed.
This is why a smaller model that fits comfortably in VRAM can sometimes provide a better practical experience than a larger model that only works through substantial CPU offloading.
VRAM capacity and GPU compute are different bottlenecks
More VRAM does not automatically mean faster inference.
VRAM capacity determines what can be kept on the GPU. Once the workload fits, other GPU characteristics become increasingly relevant, including memory bandwidth and available compute.
Consider two different failures:
- A model does not fit in VRAM and requires CPU offloading.
- A model fits entirely in VRAM but still generates more slowly than you want.
The first is primarily a capacity problem. The second may be a throughput problem.
Buying additional VRAM can solve the first without necessarily solving the second to the same degree.
This distinction matters when evaluating upgrades. Do not use VRAM capacity as a complete proxy for inference performance.
System RAM can be the bottleneck too
System RAM becomes especially important for CPU inference and partially offloaded models.
There are two separate questions:
Capacity: Is there enough RAM to hold the required model data, runtime allocations, operating system, and other applications?
Bandwidth: Can the CPU access the model data quickly enough for the desired generation rate?
Adding RAM solves a capacity shortage. It does not necessarily solve a bandwidth bottleneck.
This is an important reason not to interpret “I have 128 GB of RAM” as “I can run any model quickly.” Large system memory may let you load much larger quantized models, but interactive inference performance remains constrained by the rest of the memory and compute path.
Memory mapping changes how RAM usage looks
Memory reporting can also be misleading.
llama.cpp supports memory-mapped model loading. Its documentation describes mmap as allowing the system to map a model and load required portions as needed instead of treating the entire model like a conventional eagerly copied allocation.
It also provides an mlock loading mode that forces model memory to remain resident rather than being swapped or compressed, at the cost of greater RAM commitment.
This means the number shown by a system monitor does not always translate directly into “the runtime copied this many gigabytes into RAM.” File-backed pages, cache behavior, shared mappings, and resident memory complicate that interpretation.
RECOMMENDATION: Treat operating-system memory statistics as diagnostic evidence rather than as a simple model-size meter.
Watch for swapping
One memory condition is much less ambiguous: severe memory pressure.
If the operating system cannot keep the active workload in physical memory and begins relying heavily on swap or compressed memory, latency can deteriorate dramatically.
Typical symptoms include:
- the entire machine becoming less responsive;
- very high disk activity during inference;
- large pauses that were not present with smaller models;
- performance changing significantly when other applications are closed.
Running a model from an NVMe SSD does not make SSD-backed swap equivalent to RAM. Storage is useful for model loading and persistence; it is not a substitute for adequate working memory during inference.
Context length can turn a fast configuration into a slow one
A model that performs well with a 2,000-token prompt may behave very differently with a 20,000-token active sequence.
There are two reasons.
First, the runtime must process the input before generating the answer. More input tokens mean more prompt-processing work.
Second, autoregressive inference normally keeps key-value states for previous tokens so that they do not have to be recomputed from scratch for every new token. This is the KV cache.
As the active sequence grows, KV-cache memory requirements generally grow as well, although the exact relationship depends on the model’s attention architecture and runtime.
If VRAM was already close to full, increasing context can expose a memory bottleneck that was invisible during short tests.
RECOMMENDATION: Benchmark a local model at approximately the context lengths you will actually use. Maximum advertised context is not automatically the best context setting for your machine.
RAG can create a prompt-processing problem
Retrieval-augmented generation introduces a particularly easy way to make a local model feel slower: retrieving too much text.
Imagine that a user asks a short question, but the RAG system inserts ten large document chunks before it. From the model’s perspective, this is no longer a short request.
The additional material must be processed, consumes context capacity, and contributes to the inference workload.
More retrieved text is not automatically better RAG.
A well-tuned retrieval system should provide enough relevant evidence to answer the question without filling the prompt with marginally useful passages.
If a local RAG assistant is much slower than ordinary chat with the same model, compare the actual prompt lengths before investigating hardware.
Quantization changes more than disk size
Quantization reduces the precision used to represent model weights and can substantially reduce model storage and memory requirements.
This can indirectly improve practical performance when a lower-memory quantization allows more of the model to stay on the GPU instead of being offloaded.
But the rule “more quantization equals more speed” is too simplistic.
Actual inference performance depends on whether the runtime has efficient kernels for the chosen quantization, the hardware backend, model architecture, and where the workload is executed.
More aggressive quantization can also affect output quality.
RECOMMENDATION: Choose quantization as a combined memory, performance, and quality decision. The smallest model file is not automatically the best configuration.
Concurrency changes the calculation
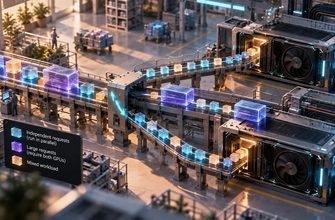
A setup that is fast for one person can become constrained when several requests run simultaneously.
Ollama’s documentation explicitly notes that parallel request processing increases context-related memory requirements. It exposes controls including OLLAMA_NUM_PARALLEL and OLLAMA_MAX_LOADED_MODELS for managing parallel requests and concurrently resident models.
This means a local AI server should not be sized only by asking whether one copy of a model fits.
You also need to consider:
- how many models remain loaded;
- how many requests may execute in parallel;
- typical context size per request;
- whether users need simultaneous generation or can tolerate queuing.
A single-user workstation and a five-user local server can therefore require very different memory strategies even when both run the same model.
A practical local LLM bottleneck test
You do not need a sophisticated benchmark suite to locate the first major problem. A controlled comparison is often enough.
1. Start with one model
Do not compare several models while changing hardware settings at the same time. Pick one model and one quantization so that the experiment has a stable baseline.
2. Use a short prompt
Run a simple request and observe two things separately: how long the system takes to begin answering and how quickly text appears afterward.
3. Verify model placement
Check whether the model is actually using the GPU, how much VRAM is occupied, and whether significant work or model data remains on the CPU/system-memory side.
4. Repeat with a realistic long prompt
Use the kind of document or conversation length you expect in normal operation.
If the short test is fast and the realistic test is not, investigate context, prompt processing, and memory headroom.
5. Reduce the model size
Try a smaller model or lower-memory quantization while keeping the workload similar.
If performance improves sharply because the new configuration fits entirely in VRAM, the previous GPU-offloading strategy was probably an important part of the bottleneck.
6. Reduce context
Repeat the same workload with less conversation history or fewer retrieved passages.
A large improvement points toward prompt-processing or context-memory pressure.
7. Eliminate concurrency
Make sure only one request and, where practical, one relevant model are active.
If the server becomes responsive again, the problem is not simply single-request model performance.
What the symptoms usually suggest
| Symptom | Investigate first |
|---|---|
| Slow model startup, normal generation afterward | Model loading, storage, model residency |
| Long delay on large prompts | Prompt processing, context length |
| Slow token-by-token generation all the time | Model size, CPU/GPU execution, memory bandwidth, offloading |
| Fast small model, very slow larger model | VRAM capacity and partial offloading |
| Fast short chat, slow long conversation | Context and KV-cache memory |
| Whole computer becomes unresponsive | System-memory pressure and swapping |
| Fast with one user, slow with several | Concurrency, KV cache, batching and VRAM |
| RAG much slower than normal chat | Retrieved prompt size and context |
This table is a diagnostic starting point, not a guarantee. Several bottlenecks can exist simultaneously.
When a hardware upgrade actually makes sense
Hardware upgrades are useful once you know which resource is limiting the workload.
If a model repeatedly spills beyond VRAM and a smaller model is not acceptable, more GPU memory can allow a larger fraction of the workload to stay on the accelerator.
If the workload already fits completely in VRAM but generation remains too slow, a faster GPU may matter more than simply adding capacity.
If you deliberately run large models on the CPU, system-memory bandwidth and CPU capability become more important. Adding RAM helps only when capacity itself is the constraint.
If performance collapses mainly with long documents, buying a GPU before reducing unnecessary context may be an expensive way to solve a prompt-design problem.
And if performance degrades only with simultaneous users, the relevant question is server concurrency rather than single-user benchmark speed.
The practical rule: change one constraint at a time
Local LLM performance is a system problem. Model size, quantization, context, KV cache, RAM, VRAM, GPU offloading, memory bandwidth, and concurrency interact with one another.
That makes random optimization ineffective.
Instead, establish a repeatable prompt and change one variable at a time: model size, quantization, context, GPU offloading, or concurrency. Watch whether the delay occurs before the first token or during generation.
The goal is not to maximize every specification. It is to identify the resource preventing your actual workload from running comfortably.
A smaller model fully resident on the GPU may be preferable to a larger model split across slower memory. A shorter, better-selected RAG context may outperform a huge prompt. And more RAM will not fix a workload whose real constraint is GPU throughput.
Once you know which stage is slow, local AI performance stops being guesswork. You can decide whether to change the model, change the inference configuration, reduce the workload, or upgrade the specific hardware resource that is actually limiting it.