- A file match is only the first useful clue
- From a correct source to a supported answer
- The relevant sentence may have lost its surroundings
- One exception can change the whole answer
- A filter inspection interval: 90 days or 30?
- Enough context does not guarantee correct use
- Inspect the handoff where the answer went wrong
- A citation and a faithful answer are different checks
- Make the next test small enough to explain
- Sources
Your AI assistant cites the right manual. You open it, find the relevant section and discover that its answer is wrong. The source is real. The citation even leads to the correct file.
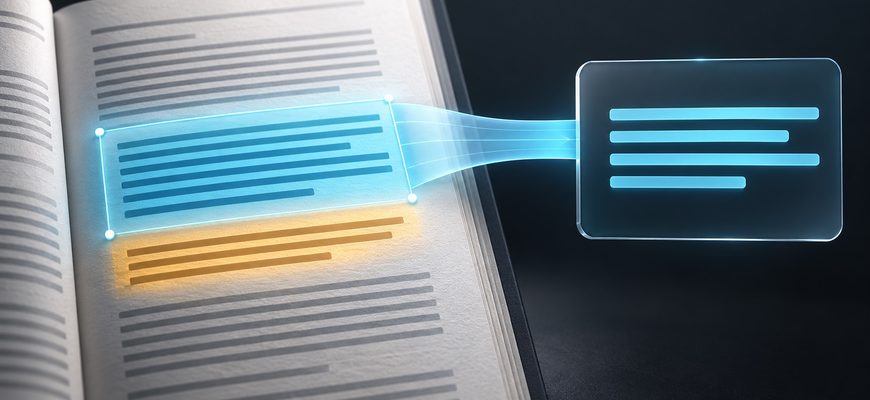
The missing link may be much smaller than a document. The system might have retrieved the general rule but missed an exception, dropped a useful passage before generation, or given the model sufficient evidence that it then interpreted incorrectly.
Retrieval-augmented generation, usually called RAG, adds retrieved information to a model’s input. Finding a relevant document is one stage in that process. It does not establish which words reached the model or whether the answer follows them.
A file match is only the first useful clue
In a typical RAG pipeline, documents are converted into searchable passages called chunks. Search selects passages for a question, and the application assembles context for the language model. Microsoft’s RAG overview separates the retrieval and answer-generation responsibilities.
A displayed filename identifies a source. It does not prove that the model received the entire file. Our guide to building a private local RAG knowledge base explains how documents become searchable material.
From a correct source to a supported answer
-
01 → Source
The document contains the answer
Check the applicable version, section, table and exceptions.
-
02 → Searchable passages
Extraction preserves the meaning
Headings, units and qualifying text must remain connected to the facts they describe.
-
03 → Model input
The needed evidence reaches the model
Inspect the final selected context, not just the search-results list.
-
04 → Answer
The response follows that evidence
Check each claim and preserve conditions that change the result.
The relevant sentence may have lost its surroundings
A paragraph can be copied accurately and still be incomplete evidence. Its heading might identify a different product. A table value might need a column label. An exception might appear immediately after the retrieved passage.
Microsoft’s structure-aware chunking documentation describes preserving document structure through headings and coherent content sections. That is useful because the unit selected by search needs enough context to retain its meaning.
Extraction is worth checking before changing the search model. If a table was flattened incorrectly, the index may faithfully retrieve text that no longer represents the original layout. Our examination of what happens when AI processes a long PDF explains why uploading the complete file does not guarantee complete interpretation.
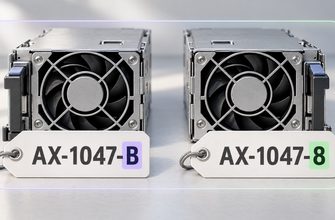
One exception can change the whole answer
A filter inspection interval: 90 days or 30?
Question: How often should we inspect AX-unit filters in a high-dust workshop?
The fictional guide says: “Inspect AX-unit filters every 90 days. In high-dust environments, inspect them every 30 days.”
The model receives only the first sentence and recommends a 90-day interval for the workshop. The correct file was found, but the context omitted the condition needed for this question.
The model receives both sentences and still recommends a 90-day interval for the high-dust workshop. The necessary exception was available; the response failed to apply it.
A supported answer: “For the high-dust workshop described, inspect the filters every 30 days. The 90-day interval is the guide’s general rule.”
Invented wording and intervals for explanation only. This is not maintenance advice, a manufacturer specification or an observed benchmark.
These two failures can produce the same visible answer and the same citation. They need different investigations. Case A calls for examining passage selection and context assembly. Case B calls for testing whether the model follows the supplied condition.
Enough context does not guarantee correct use
Even when a passage reaches the model, its position and surrounding material can affect performance. The Lost in the Middle study found position-sensitive performance in its tested question-answering and retrieval tasks, including weaker results when relevant information appeared in the middle of long contexts.
That finding is not a rule that every modern model always misses the middle. A 2026 reproducibility study found that context size and ordering effects interact with retrieval quality, model choice and evaluation setup.
For your application, test representative questions with the actual evidence supplied to the model. Adding more passages changes the input; it does not automatically resolve the failure.
Inspect the handoff where the answer went wrong
| Failure point | Evidence to inspect | Targeted test |
|---|---|---|
| Extraction | Parsed text beside the original page. | Check headings, table labels and exceptions. |
| Passage selection | The exact chunks returned by search. | Check whether the decisive clause was retrieved. |
| Context assembly | The evidence in the final model input. | Check whether filtering, trimming or summarization removed it. |
| Generation | The response beside sufficient supplied evidence. | Ask for the applicable clause, condition and answer. |
This comparison should use one captured request where possible. Running a new search can return different passages and obscure what happened in the failed attempt. Retain only the diagnostic information your access and data-handling rules permit.
A citation and a faithful answer are different checks
A source link helps a reader locate a document. The stronger question is whether the cited material supports the specific claim next to it.
Ragas defines faithfulness as consistency between the response and retrieved context, assessed by checking whether response claims are supported. That is a useful evaluation dimension, but it is narrower than overall correctness.
In Case A, the general 90-day rule is present in the incomplete context, yet it does not establish the right interval for the workshop. In Case B, the recommended interval conflicts with the applicable exception supplied to the model. Source coverage and evidence use therefore need separate checks.
Make the next test small enough to explain
Start with the failed question, the applicable source passage and an expected answer written from that passage. Include any condition that changes the result.
Then run two tests: one through the full retrieval pipeline, and one with the verified passage supplied directly. If the direct test works but the full pipeline fails, investigate how evidence is selected and assembled. If the direct test also fails, retrieval changes alone will not explain the problem.
Record the model, prompt and context used in each test. A single successful retry does not establish reliability, so keep the case in a small regression set alongside related questions and cases with insufficient evidence.
When a required condition is missing, a useful answer can identify that gap instead of selecting a convenient rule. When the evidence is present, the response should carry the condition into its conclusion. That is what turns a correct document match into an answer worth using.