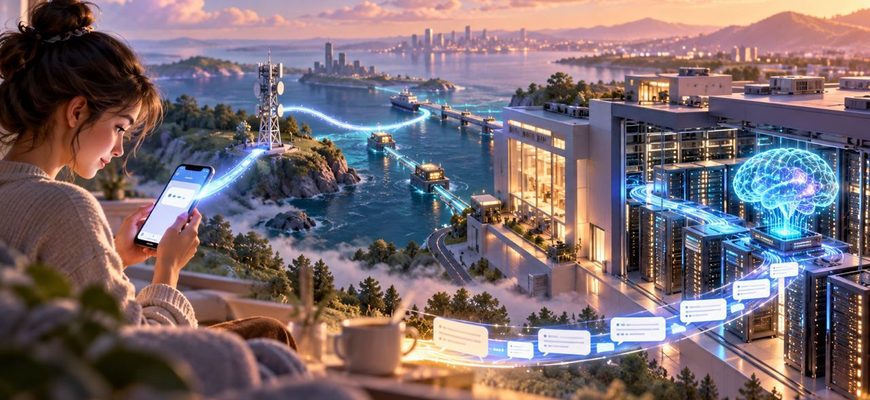
- Five stops between Send and the answer
- Your app packs the question
- Your words travel across networks
- A server gets the job
- The reply is built, piece by piece
- You see the answer appear
- Why does AI sometimes pause before answering?
- Does every AI question go to a data center?
- Does the AI know whether its answer is true?
- Your question doesn’t disappear into a cloud
- Sources & further reading
You type one question. Somewhere else, a computer begins building the reply. Here’s the trip your words take.
Open an AI chat. Type “Why does the Moon change shape?” Press Send. A few moments later, an explanation appears. It feels immediate. But between those two moments, your question may cross networks, reach a data center, pass through a model and return in little pieces. Following that journey reveals how AI answers questions.
Why does the Moon change shape?
The Moon doesn’t change shape. We see different portions of its sunlit half
- Send
- Travel
- Arrive
- Generate
- Return
To understand how AI answers questions, you don’t need a computer-science degree. Just follow that one sentence about the Moon.
Five stops between Send and the answer
Your app packs the question
The text doesn’t leave as a little glowing bubble. The app turns it into data and sends a request to the AI service. Depending on the product and settings, that request may also include parts of the current conversation, an attached image or instructions about how the assistant should respond.
It doesn’t necessarily send every conversation you’ve ever had. What gets included depends on the service.
Your words travel across networks
For a cloud AI service, your request crosses the internet. It might pass through your home router, your internet provider and several other networks before reaching the company running the model.
A properly configured HTTPS connection encrypts the traffic in transit. That protects it from casual interception along the route; it does not mean the service processing your question cannot read it. Privacy and retention rules depend on the provider and account settings.
A server gets the job
The service receives the request and decides where to process it. That may involve checking the request, choosing a model, and placing the work on an available machine. If many people are asking questions at once, a request may spend some time waiting.
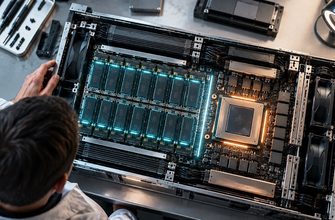
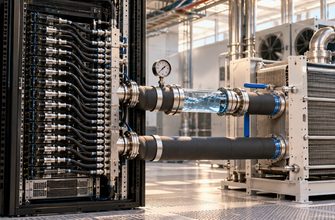
Behind the scenes are real computers. Many large AI models run on specialized chips, often GPUs, housed in data centers. The chips do the calculations; cooling equipment keeps them from overheating.
The reply is built, piece by piece
First, the system converts the text into tokens — small pieces of language that may be whole words, parts of words or punctuation. The model processes the question and its available context, then predicts and selects what token should come next. It uses the growing response to select the next one, and the next.
For our Moon question, the answer isn’t usually fetched as a finished paragraph from a secret library. The model generates the explanation. If the service has browsing, search or another tool enabled, it may also retrieve outside information — but that’s an additional step, not a requirement for every answer.
Illustration only: these displayed words aren’t an exact tokenization.
You see the answer appear
Some services wait until the reply is complete. Others stream it: they send small updates while the model is still producing text. Your app joins those updates into the message you watch unfolding on screen.
That’s why an answer can start appearing before it’s finished. What looks like typing is usually the interface displaying newly received text.
Why does AI sometimes pause before answering?
There isn’t one universal delay. The request may be traveling over the network, waiting for processing, or taking longer because the model must read a long conversation before it begins generating a reply. The reply itself can also be slower or faster depending on the workload and hardware.
If you’ve ever watched one AI answer start immediately and another take its time, you’re seeing a mix of these stages — not necessarily the model “thinking harder.” For a deeper look, see why one long prompt can slow down other users.
Does every AI question go to a data center?
No. Some smaller models run on a phone or laptop. In that case, the calculation can happen locally. Other apps mix on-device and cloud processing. Check the specific feature before assuming your text stays on the device.
Does the AI know whether its answer is true?
Not automatically. Generating plausible language and checking facts are different jobs. A convincing explanation can still contain a mistake. Ask for sources when the details matter, and verify important claims.
Your question doesn’t disappear into a cloud
In a typical cloud AI chat, it reaches real infrastructure, is processed through a model and comes back as data your screen can display. The impressive part is how much work happens between your tap and the first sentence. The useful part is knowing what happens to your words along the way.
One more question: why might the same prompt get a different answer?
Some generation settings allow different tokens to be chosen from several plausible options. Context, model versions and service behavior can also change. If you’re curious, we explain this in Same Model, Same Prompt. Why a Different Answer?
Sources & further reading
This is a general explanation of common cloud-based text AI, not a trace of any particular company’s private systems. Actual routing, storage, safeguards and tool use vary by provider.
- Hugging Face — Text generation: how models generate one token after another.
- OpenAI API — Streaming events: how output text updates can be delivered to an app.
- Cloudflare — SSL/TLS overview: what encryption protects during transit.
- il.digital — Inside a 135 kW AI Rack: what the machines and cooling systems look like behind the interface.
Editorial explainer · For Beginners · Illustrated journey, not a network capture or hardware benchmark.