- Why n8n Disk Space Keeps Growing After a Workflow Finishes
- Workflow Trigger
- Node Execution
- Execution History
- Physical Infrastructure
- Why the GPU Can Be Idle While the SSD Fills Up
- VRAM and Persistent Storage Solve Different Problems
- n8n Disk Space Diagnostics: What Is Filling the Drive?
- Storage Diagnostics Matrix
- How n8n Execution Pruning Controls Disk Usage
- n8n Execution Retention Configuration
- Why n8n Disk Space Can Still Grow With Pruning Enabled
- Why n8n Disk Space May Stay Full After Pruning
- What Happens Inside the SQLite File?
- Before Pruning
- After Pruning
- After Compaction
- Large Database File ≠ Failed Pruning
- How to Diagnose an n8n Disk Space Problem
- Storage Troubleshooting Matrix
- How to Reduce n8n Disk Space Usage Safely
- 1. Back Up Persistent State
- 2. Review Execution Save Settings
- 3. Choose Deliberate Retention Limits
- 4. Inspect Binary Storage
- 5. Plan Database Maintenance
- 6. Monitor Storage Growth
- A More Restrictive Execution Retention Policy
- How Much Storage Does One n8n Execution Need?
- Small Saved Payloads Can Add Up
- Why Deleting Every Execution Is Not Always the Answer
- Measuring Real n8n Disk Space Growth
- Frequently Asked Questions
- Does n8n automatically delete old executions?
- Why is n8n disk space still full after deleting old executions?
- Does PostgreSQL eliminate n8n storage problems?
- Can I delete the n8n database file?
- How can I prevent another n8n disk space warning?
- A Finished Workflow Still Has a Physical Footprint
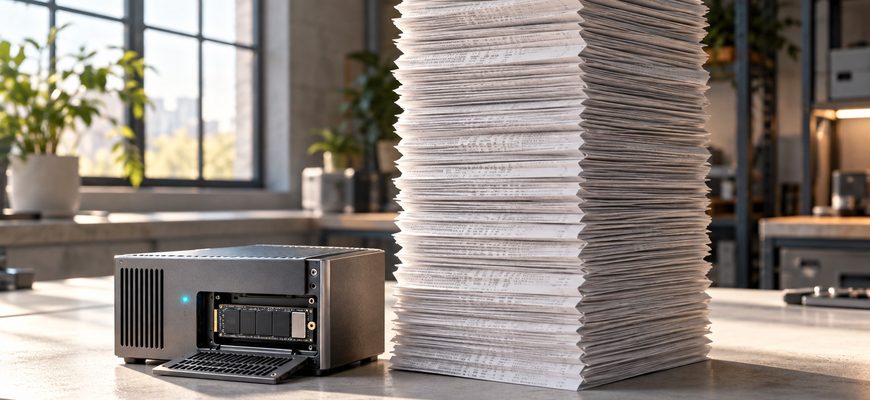
The workflow finished successfully. The database kept the evidence. Now the server is running out of storage.
An n8n disk space warning appears on a server that has been running automation workflows without problems for weeks. Every scheduled job completes successfully. CPU usage looks normal. The AI model is idle. Nothing suggests that the system is suddenly doing more work.
Yet the SSD keeps filling up.
The missing space may be occupied by records of work that already finished. n8n can preserve execution inputs, outputs and metadata so administrators can inspect previous runs. Binary files and runtime logs can add further storage pressure.
The interesting part is what happens after the final workflow node completes. Following that path reveals how a successful automation becomes persistent data, why cleanup does not always shrink database files, and which measurements identify the real storage problem.
Why n8n Disk Space Keeps Growing After a Workflow Finishes
A completed automation is not necessarily an automation that leaves no trace.
Imagine a workflow that receives customer messages, sends their contents to a language model, extracts relevant information and updates a spreadsheet.
During execution, multiple nodes process information and produce intermediate results. The system also knows when the execution started, whether it succeeded and which workflow produced it.
Some information is temporary. Other information can be preserved for debugging, inspection and supported retry operations.
According to the official n8n execution configuration , saving execution data on success and on error is enabled by default.
This is useful when a workflow produces an unexpected result. Instead of guessing, an administrator can inspect historical execution information.
But those saved records need persistent storage. Depending on configuration, execution data can be stored in a database or another supported backend.
Workflow Trigger
A webhook, message or scheduled event starts an execution.
Node Execution
Nodes process input and generate intermediate results.
Execution History
Selected execution information is retained.
Physical Infrastructure
Persistent data occupies capacity in the configured storage system.
Simplified execution lifecycle. Actual storage locations depend on the deployment, execution-data mode and database configuration.
Why the GPU Can Be Idle While the SSD Fills Up
AI automation often involves several independent systems.
An inference server generates a response. The automation platform passes that response to other nodes, handles integrations and records execution information.
When inference finishes, GPU activity may drop. But retained execution records can remain available for days or weeks.
VRAM and Persistent Storage Solve Different Problems
GPU memory stores model weights and temporary inference state while a local language model runs.
Persistent execution records belong to another part of the system. On a self-hosted installation with local storage, they ultimately occupy physical disk capacity.
Increasing VRAM does not solve a storage problem caused by excessive saved execution history.
Our investigation of what happens when an AI agent crashes explains why durable state is essential for some recovery mechanisms.
This article examines the other side of persistence: stored history consumes resources long after the original computation has finished.
n8n Disk Space Diagnostics: What Is Filling the Drive?
A full disk is a symptom. It does not identify the component responsible for the growth.
Several kinds of stored information can contribute to the same warning. They have different locations, retention policies and maintenance requirements.
The first step is to distinguish execution history from binary payloads, logs and unrelated files.
Storage Diagnostics Matrix
TABLE 01| Storage Source | What Accumulates | What to Inspect | Pruning Relationship |
|---|---|---|---|
| Execution History | Retained workflow execution data, including saved node results. | Execution count, save settings and configured storage backend. | Directly managed |
| SQLite Database | Database records, indexes and previously allocated pages. | Database file size and the amount of reusable internal space. | File may remain large |
| Binary Payloads | Images, documents and other stored workflow files. | Binary-data mode, active storage location and retained objects. | Mode-dependent |
| Container Logs | Application output collected by the container runtime. | Docker logging configuration and host log storage. | Separate management |
| Other Host Files | Backups, temporary files and unrelated application data. | Filesystem usage and mounted-volume ownership. | Outside n8n pruning |
Execution pruning can also remove associated binary data, subject to the active storage mode. It does not manage every file on the host.
The distinction matters when a workflow handles large documents.
A small text-processing workflow and an automation downloading hundreds of PDFs may execute equally often but create very different storage demands.
With current n8n versions, administrators should also check the execution-data storage mode rather than assuming all retained information lives inside SQLite.
The relevant configuration includes
N8N_EXECUTION_DATA_STORAGE_MODE.
Supported modes and licensing requirements
depend on the deployment and n8n version.
How n8n Execution Pruning Controls Disk Usage
n8n includes automatic cleanup for eligible completed executions.
According to the official execution-data documentation , pruning is enabled by default.
The system uses age-based and count-based limits. When an execution becomes eligible, n8n first marks it for deletion and later removes it permanently.
The default settings provide a useful starting point for understanding how retained history is managed.
Fourteen days before an eligible completed execution qualifies for age-based pruning.
The documented count threshold for retained executions.
The default safety buffer before eligible data is permanently deleted.
Documented defaults verified in October 2026. Actual behavior depends on the installed version, deployment settings and execution eligibility.
n8n Execution Retention Configuration
TABLE 02| Setting | Default | Purpose |
|---|---|---|
EXECUTIONS_DATA_PRUNE
|
true | Enables automatic removal of eligible old executions. |
EXECUTIONS_DATA_MAX_AGE
|
336 | Maximum age in hours before age-based pruning. |
EXECUTIONS_DATA_PRUNE_MAX_COUNT
|
10000 | Count threshold used when pruning execution history. |
EXECUTIONS_DATA_SAVE_ON_SUCCESS
|
all | Controls whether successful execution data is saved. |
EXECUTIONS_DATA_SAVE_ON_ERROR
|
all | Controls whether execution data is saved on error. |
EXECUTIONS_DATA_SAVE_ON_PROGRESS
|
false | Controls saving progress during node execution. |
EXECUTIONS_DATA_HARD_DELETE_BUFFER
|
1 | Safety buffer in hours before permanent deletion. |
These are documented defaults, not recommended values for every workload. Workflow-level overrides and operational retention requirements still matter.
Why n8n Disk Space Can Still Grow With Pruning Enabled
Retention limits do not mean every execution disappears immediately.
Running, waiting and new executions are not eligible for pruning. Annotated executions are also excluded.
The deletion process runs periodically, so changes in retained history are not necessarily instantaneous.
More importantly, removing database records does not guarantee that the physical database file becomes smaller.
This is where SQLite introduces an important distinction.
Why n8n Disk Space May Stay Full After Pruning
Deleting information from a database and returning physical storage space to the operating system are different operations.
SQLite is the default database for a standard self-hosted n8n installation, unless another supported database is configured.
SQLite stores data in pages inside a database file.
When records are deleted, pages can become available for reuse by future database writes. That does not necessarily make the file smaller.
As a result, pruning may successfully remove historical executions while the filesystem still reports a large SQLite database.
The file can have reusable internal space even when its visible size remains close to its previous maximum.
What Happens Inside the SQLite File?
A conceptual comparison of stored pages, reusable space and file compaction.
Before Pruning
Retained records occupy database pages.
After Pruning
Deleted records leave reusable internal space. The file may remain the same size.
After Compaction
A successful VACUUM can reorganize the database and reclaim unused file space.
Conceptual diagram, not a benchmark or a proportional representation of measured database capacity.
SQLite provides the VACUUM operation to rebuild database files and reclaim unused storage space.
n8n also documents the
DB_SQLITE_VACUUM_ON_STARTUP
configuration option.
However, compaction is a maintenance procedure rather than a command to run blindly whenever the drive approaches capacity.
SQLite explains that VACUUM may require substantial additional free disk space while rebuilding a database.
A nearly full drive can therefore be a particularly poor environment for an unplanned compaction operation.
Large Database File ≠ Failed Pruning
A large SQLite database can contain free internal pages that are available for future executions.
Before concluding that pruning has failed, distinguish retained logical records from the size of the physical database file.
Always verify backups, available capacity and maintenance requirements before database compaction.
How to Diagnose an n8n Disk Space Problem
Begin with measurements. A storage warning alone cannot tell you which component needs attention.
On a Linux server, basic read-only commands can establish the first part of the picture.
df -h
df -i
du -sh ~/.n8n
These commands inspect filesystem capacity, inode availability and the size of the default n8n user directory.
Run them in the appropriate host or container context. Custom storage locations, Docker volumes and external databases may live elsewhere.
A PostgreSQL deployment requires inspection of its actual database storage, not just the application container’s filesystem.
Once you know what is growing, the next action becomes much clearer.
Storage Troubleshooting Matrix
TABLE 03| Observed Symptom | Possible Explanation | Recommended Investigation |
|---|---|---|
| Disk usage grows every day | Execution records or other files are accumulating faster than they are removed. | Compare retained executions, database growth and filesystem usage over time. |
| SQLite file remains large after pruning | Deleted records may have left reusable pages inside the database file. | Verify execution cleanup and assess whether scheduled database maintenance is needed. |
| Image or document workflows use substantial storage | Binary payloads may account for much of the occupied space. | Inspect binary-data mode, storage location and retention behavior. |
| Application data looks small, but the host disk is full | Container logs, backups or unrelated files may occupy the capacity. | Inspect host-level usage, mounted volumes and log rotation. |
| Retention limits appear ineffective | Executions may be ineligible for pruning or affected by configuration overrides. | Check execution states, annotations and global versus workflow settings. |
These symptoms have multiple possible causes. The table is a diagnostic starting point, not proof of a specific failure.
How to Reduce n8n Disk Space Usage Safely
The correct fix depends on what is consuming storage and which historical data the workflow must preserve.
1. Back Up Persistent State
Before changing retention or database configuration, create a recoverable backup. Include the relevant database, user configuration, credential encryption key and any separately stored data required for recovery.
Verify the recovery procedure rather than assuming that a copied directory represents a complete backup.
2. Review Execution Save Settings
Stable workflows may not need complete successful-execution history. Failed executions are often more valuable for troubleshooting.
However, disabling saved history may remove information required for debugging, auditing or supported retry operations.
3. Choose Deliberate Retention Limits
Age-based and count-based thresholds should reflect actual execution volume, payload size and operational requirements.
A busy workflow may reach the count threshold before the age threshold.
4. Inspect Binary Storage
Workflows that download documents, generate images or process large files deserve separate attention.
Do not manually delete arbitrary binary-data directories without understanding storage references and supported cleanup behavior.
5. Plan Database Maintenance
For SQLite, determine whether the file contains reusable internal space before considering compaction.
For PostgreSQL, use PostgreSQL-specific monitoring and maintenance practices. SQLite configuration options do not apply to PostgreSQL.
6. Monitor Storage Growth
Measure filesystem usage, database size and retained execution counts over time.
A reliable retention policy should produce understandable storage behavior, not merely a temporary improvement in available disk space.
A More Restrictive Execution Retention Policy
The following is an illustrative configuration for a self-hosted instance. It is not a universal recommendation or the default configuration.
EXECUTIONS_DATA_SAVE_ON_SUCCESS=none
EXECUTIONS_DATA_SAVE_ON_ERROR=all
EXECUTIONS_DATA_SAVE_ON_PROGRESS=false
EXECUTIONS_DATA_PRUNE=true
EXECUTIONS_DATA_MAX_AGE=168
EXECUTIONS_DATA_PRUNE_MAX_COUNT=5000
This example stops saving successful execution data under the applicable settings, retains error execution data, and establishes a seven-day age threshold with a 5,000-execution count limit.
The settings must be applied through the appropriate deployment configuration. Workflow-level overrides and version-specific behavior should also be checked.
Changing retention settings does not immediately shrink an existing SQLite database file.
How Much Storage Does One n8n Execution Need?
There is no universal number.
A workflow saving short text results has a different storage profile from one retaining long AI responses, thousands of items or large files.
Execution frequency alone therefore cannot determine disk requirements.
Small Saved Payloads Can Add Up
Imagine a server completing 600 executions per day.
Assume each retained execution contributes an average of 250 KB of serialized payload data.
Over 14 days, that represents approximately 8,400 executions and 2.1 GB of logical payload data.
This calculation is illustrative, not a measured n8n benchmark.
It excludes database indexes, storage overhead, separate binary objects, logging and other files. Actual retention can also be limited by the configured execution count.
The most useful measurement is how much additional persistent storage a representative workload creates under its real retention policy.
Measuring that relationship makes future capacity planning substantially more reliable than assuming a fixed storage cost per execution.
Why Deleting Every Execution Is Not Always the Answer
Persistent execution history exists for a reason.
When an automation calls an external API, saved records can help determine which action was requested and what response the workflow received.
This becomes particularly important when requests time out or a workflow retries an operation.
Our article about why AI agents repeat actions after a timeout explains how a completed external action can still lead to duplicate operations when confirmation is lost.
Execution history can be valuable evidence during that investigation.
But storing everything indefinitely introduces different problems: larger backups, growing storage requirements and additional retained information that must be protected.
A good retention policy balances recovery, debugging, accountability, privacy and storage cost.
Frequently Asked Questions
Does n8n automatically delete old executions?
Yes. n8n provides automatic execution pruning with documented age-based and count-based limits. Actual cleanup depends on configuration, execution status and eligibility.
Why is n8n disk space still full after deleting old executions?
SQLite can retain previously allocated file space for future reuse. The database file may therefore remain large after execution records have been deleted. Other files, such as binary payloads or logs, may also contribute to total disk usage.
Does PostgreSQL eliminate n8n storage problems?
No. PostgreSQL changes database architecture and maintenance, but retained execution data still requires storage capacity. Migration does not replace monitoring and retention planning.
Can I delete the n8n database file?
No. The database can contain essential application information, including workflows, credentials and execution records. Deleting it is not a safe storage cleanup method.
How can I prevent another n8n disk space warning?
Monitor filesystem and database growth, review execution-save settings, configure appropriate retention limits and investigate binary-data and log storage separately.