Token Generation
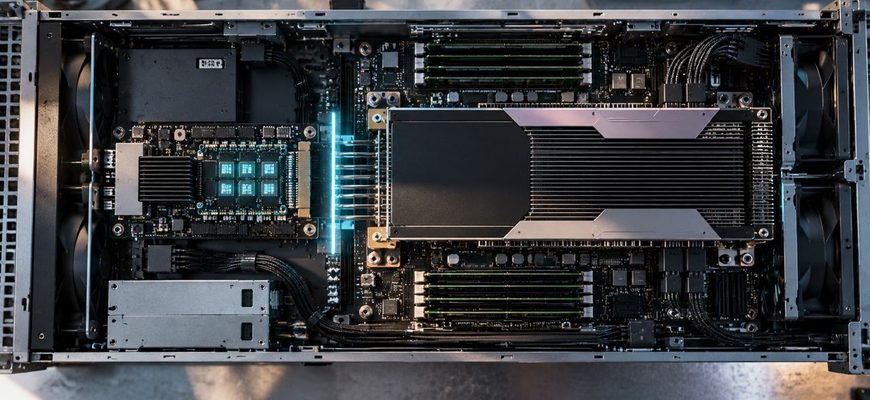
A large language model can have a powerful GPU almost to itself and still produce a single conversation one token at a time. The accelerator finishes one
A local LLM does not have one meaningful “tokens per second” number. Before it can write the first token of an answer, it has to process the tokens already in the prompt.