Inference Server
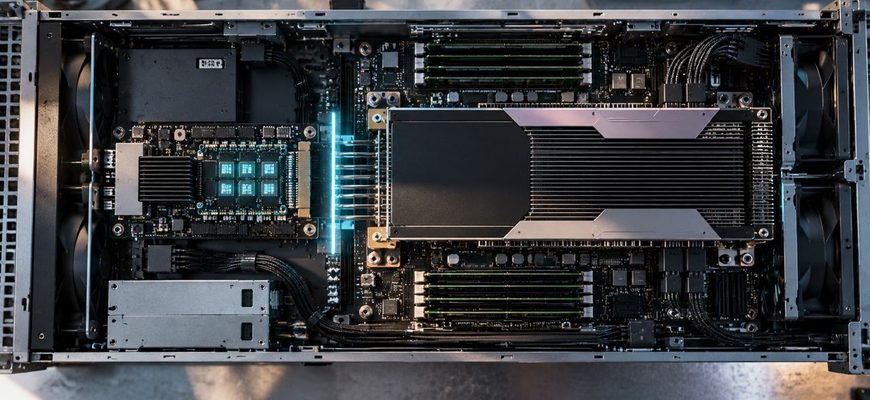
A large language model can have a powerful GPU almost to itself and still produce a single conversation one token at a time. The accelerator finishes one
Local AI, Local LLMs, GPU hardware, inference, RAG and AI server infrastructure explained clearly.