- What the percentage actually counts
- The GPU’s clock and your request’s clock
- Continuous GPU activity can include your waiting time
- A long prompt can consume work without producing answer tokens
- Busy arithmetic and busy memory are different limits
- More tokens for the server, fewer for each person
- Choose the result you want before maximizing the meter
- Sources
NVIDIA’s GPU-utilization percentage counts time with at least one kernel executing. A kernel is a program running on the accelerator.
A 100% reading therefore means continuous activity during the reported interval. It does not establish peak compute efficiency or tell you how much of that activity advanced your request.
The GPU might be moving data, processing somebody else’s prompt or sharing its capacity among many responses. Your waiting time needs its own measurement.
What the percentage actually counts
The nvidia-smi documentation defines its GPU utilization reading over a sampling period that varies by product. The key condition is kernel execution during that period, rather than a measurement of achieved arithmetic throughput.
This interpretation applies to NVIDIA’s GPU-utilization field. Other dashboards may use different counters or aggregate devices. Check the metric behind the label.
The GPU’s clock and your request’s clock
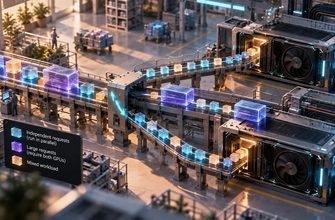
A shared inference server has work belonging to multiple requests. Your request can wait for admission while another one keeps the accelerator occupied. It can then spend time processing its input before a first output token appears.
Continuous GPU activity can include your waiting time
Time progresses from left to right →
Serving engines expose separate measurements for these intervals. The vLLM metrics documentation distinguishes queue time, time to first token, prompt-processing time, decode time and end-to-end latency. None is replaced by a device-utilization percentage.
The distinction continues after output starts. Smooth streaming depends on how regularly the request receives further generation work. A high utilization reading does not tell you how long the user waits between updates.
A long prompt can consume work without producing answer tokens
Before an autoregressive language model starts its response, it processes the input in a phase called prefill. During decode, it advances the generated response. These phases have different computational patterns and compete for serving resources.
vLLM’s optimization guide explains the scheduling trade-off around chunked prefill: splitting large prompt-processing work allows it to be scheduled alongside decode work. Tuning changes the balance between first-token latency, subsequent output latency and throughput.
The visible result can be a fully occupied GPU while a new request has not produced a word, or while existing streams receive less frequent updates. The relevant question is which requests and phases are receiving that work. The effect is examined in more detail in how long prompts disrupt shared inference.
Busy arithmetic and busy memory are different limits
A neural-network operation needs both calculations and data movement. If data cannot reach the arithmetic units quickly enough, additional theoretical compute capacity does not automatically make that operation faster.
NVIDIA’s matrix-multiplication performance guide describes the distinction using arithmetic intensity: the amount of calculation performed for each byte accessed. Operations with different shapes and data reuse can be limited by memory movement or by arithmetic capacity.
A memory-limited kernel is still an executing kernel. Its time contributes to the busy reading even when achieved arithmetic throughput is far below the GPU’s advertised peak.
That is why GPU utilization alone cannot establish the bottleneck. It needs to be interpreted alongside workload behavior and, when deeper analysis is necessary, profiling information about compute and memory activity.
More tokens for the server, fewer for each person
Batching adds another distinction: aggregate throughput and individual response speed.
Consider an illustrative arithmetic example, not a hardware benchmark. One configuration serves a single stream at 40 output tokens per second. Another serves eight simultaneous streams at 20 tokens per second each. The second configuration produces 160 output tokens per second in total, while each person receives text at half the first configuration’s rate. Both could show sustained high GPU utilization.
The numbers demonstrate the difference between the two measurements; they do not predict how a particular GPU scales. Real results depend on the model, batch composition, context lengths and serving engine.
Continuous batching lets a server combine changing sets of active requests. Its value is doing more useful shared work, but the acceptable balance depends on the service. An overnight batch job and an interactive assistant have different tolerances for waiting.
Choose the result you want before maximizing the meter
For an interactive assistant, define an acceptable wait before output begins and an acceptable pace after it starts. Then ask how many requests the server can support while meeting those conditions.
For offline processing, completed work per unit of time may be the more useful objective. High utilization is helpful when it accompanies that result. It is insufficient evidence on its own.
The definitions matter when comparing systems, too: LLM benchmark metrics distinguish throughput from first-token delay and output timing. Compare like workloads and report latency distributions rather than relying on one average or percentage.
The useful target is completed work within an acceptable wait. Utilization helps explain how the hardware is being used; request timings establish whether that use is serving the people who depend on it.