You download a model described as 30B-A3B. The second number looks reassuring: only about three billion parameters are active for each token. It is tempting to treat the model as a fast 3B model wearing a much larger label.
Then you try to run it locally. The model file is still large. Loading it consumes far more memory than a dense 3B model. Moving its experts into system RAM can make it fit, but performance becomes dependent on a memory path that did not matter nearly as much for the smaller dense model.
Nothing is contradictory. A Mixture-of-Experts model separates two resources that dense models make easy to confuse: how many parameters exist and how many parameters participate in the computation for a particular token.
Understanding that distinction is the key to sizing local hardware for MoE models.
- An MoE model can activate only a fraction of its expert parameters for each token while still requiring the full expert pool to be stored somewhere accessible.
- “3B active” describes sparse computation. It does not mean a 30B MoE has the memory footprint of a dense 3B model.
- MoE can reduce arithmetic work relative to activating every expert, but local performance can still be constrained by VRAM, system RAM and movement of expert weights.
- Quantization reduces the size of the stored weights; it does not change the basic distinction between total and active parameters.
- For local inference, evaluate total model footprint, active parameters and expert placement separately.
- Dense models make the memory question simpler
- What a Mixture-of-Experts layer actually changes
- Inactive parameters still have to live somewhere
- Why “30B total, 3B active” is not a 3B local model
- Where the experts live becomes a performance decision
- The router chooses experts; the memory system has to deliver them
- Sparse compute does not guarantee dense-model speed
- MoE changes what “fits” means
- System RAM matters differently for MoE
- Quantization still matters enormously
- Context memory does not disappear either
- When CPU expert placement makes sense
- Do not size an MoE machine from the A-number
- What to check before downloading a local MoE model
- The useful way to think about MoE locally
Dense models make the memory question simpler
In a conventional dense transformer, the model repeatedly uses the same major weight matrices as tokens move through its layers. If you have an 8B dense model, the useful mental model is that roughly eight billion learned parameters belong to the model and most of the relevant layer weights participate in every forward pass.
Quantization can make those weights smaller, but it does not make them conditional. A Q4 version stores a compressed representation of the model; the basic architecture remains dense.
This creates a reasonably intuitive relationship between parameter count, weight storage and work per token. It is not exact enough to calculate total VRAM usage—the KV cache, runtime buffers and other allocations still matter—but the parameter count gives you a useful first clue about the scale of the machine required.
MoE changes that relationship.
What a Mixture-of-Experts layer actually changes
An MoE transformer replaces some dense feed-forward computation with a collection of separate feed-forward networks called experts. A routing mechanism decides which experts should process each token.
The crucial part is that the router does not normally send every token through every expert.
Qwen’s Qwen3-30B-A3B is a useful concrete example. Its published configuration contains 128 experts and selects eight experts per token. Qwen describes the model as having 30.5 billion total parameters while activating about 3.3 billion parameters during inference.
That is where the attractive A3B number comes from.
The router therefore creates computational sparsity. The machine does not have to execute every expert for every token.
But the experts that were not selected have not disappeared from the model.
Inactive parameters still have to live somewhere
Imagine a workshop containing 128 specialized machines. A particular job uses only eight of them. Electricity and machine time for that job depend mainly on the machines that actually run, but the workshop still needs physical space for all 128 because the next job may need a different set.
An MoE model creates a related hardware problem.
The router may activate only a small subset of experts for the current token, but future tokens can be routed elsewhere. The runtime therefore needs access to the entire expert pool.
On a local machine, those weights must ultimately exist in a memory tier available to the runtime. Depending on the configuration, that can mean GPU VRAM, system RAM, memory shared by an integrated architecture, or a combination of memory locations.
This is why active parameter count is not a VRAM requirement.
Why “30B total, 3B active” is not a 3B local model
Consider Qwen3-30B-A3B again. Qwen lists 30.5B total parameters and 3.3B activated parameters. The model is sparse during computation, but the complete checkpoint still represents roughly 30B parameters.
If those weights are quantized, their storage requirement falls. That can make the model practical on hardware that could not hold the original BF16 representation. But quantization and sparsity solve different problems.
Quantization asks: how many bits should be used to represent the stored weights?
MoE routing asks: which subset of those weights should participate in this token’s computation?
You can therefore have a quantized MoE model. The weight representation is compressed, and only selected experts are active at a given MoE layer. Neither fact means the inactive expert weights cease to require storage.
Where the experts live becomes a performance decision
If the complete quantized model fits comfortably in GPU memory, the hardware problem is comparatively straightforward: the GPU can access the expert weights from its own high-bandwidth memory.
The more interesting case appears when the model is too large for available VRAM.
Current llama.cpp exposes MoE-specific placement controls. Its command-line interface includes --cpu-moe for keeping all MoE expert weights on the CPU side and --n-cpu-moe for keeping expert weights from a specified number of layers on the CPU.
That distinction exists for a reason. Expert weights can represent a large share of an MoE checkpoint, making them an obvious target when VRAM capacity is limited.
Moving them to system RAM can turn an otherwise impossible configuration into one that loads. But it changes the physical path of inference.
The router chooses experts; the memory system has to deliver them
A routing decision is software. Serving the selected expert weights is physical. If those weights are already in VRAM, the GPU reads them through its local memory system. If relevant expert data lives in system RAM, inference can become dependent on CPU memory bandwidth, CPU execution, host-device transfers and synchronization, depending on the runtime and placement strategy.
MoE therefore moves part of the performance question from “how much arithmetic is active?” to “where are the selected weights when they are needed?”
Sparse compute does not guarantee dense-model speed
It is tempting to turn active parameter count directly into a speed prediction. If only about 3B parameters are active, shouldn’t generation behave like a dense 3B model?
No reliable universal conversion exists.
The active parameter number captures an important part of the arithmetic workload, but inference speed also depends on the architecture around those experts, routing overhead, quantization format, kernel implementation, memory bandwidth, batch shape, expert placement and the hardware running the model.
If the expert pool fits in fast local memory, sparsity can be very attractive. If the runtime repeatedly depends on slower memory tiers, the advantage can be constrained by data movement rather than arithmetic.
This is the same distinction that appears elsewhere in local inference: a model being computationally possible is not the same as it being efficiently placed.
MoE changes what “fits” means
For a local user, there are at least three useful definitions of fit.
| Question | What it really asks | Possible failure |
|---|---|---|
| Can the model load? | Can its weights and runtime allocations exist across available memory? | Out-of-memory or insufficient RAM |
| Can enough of it stay on the GPU? | Can the fast memory tier hold the tensors needed for the desired execution path? | Heavy CPU placement or offloading |
| Can it run interactively? | Can selected experts and other tensors be processed fast enough for the workload? | Acceptable capacity but poor latency |
This is why a machine with abundant system RAM can be surprisingly capable at loading large MoE models while still delivering a very different interactive experience from a system that keeps the relevant model state in high-bandwidth GPU memory.
The distinction is especially important when reading community reports. “Runs on 32 GB” may describe successful loading. It does not automatically describe the generation speed, prompt-processing speed, context length or expert placement used by that configuration.
System RAM matters differently for MoE
Large system memory is already useful for CPU inference and GPU-offloaded dense models. MoE makes the capacity-versus-bandwidth distinction even more visible.
RAM capacity answers whether the expert pool can be stored. Memory bandwidth and the execution path help determine how quickly the system can use the relevant weights.
Adding more RAM can solve the first problem without solving the second.
A local workstation with enough RAM to hold a large quantized MoE checkpoint may therefore be a useful experimentation machine even when it cannot deliver the same latency as a system with enough accelerator memory to keep far more of the workload close to the GPU.
Quantization still matters enormously
MoE does not make weight quantization irrelevant. In fact, total parameter count means quantization can be especially important when the expert pool is large.
Qwen distributes GGUF versions of Qwen3-30B-A3B in several quantization formats, including Q4_K_M, Q5_K_M, Q6_K and Q8_0.
Lower-bit weights reduce the complete stored model footprint. That can change whether the model fits in system RAM, whether more experts can remain in VRAM and how much memory remains for the KV cache and runtime allocations.
But the familiar trade-off remains: more aggressive quantization reduces memory consumption by representing weights with less precision. It should be treated as a quality-versus-resource decision rather than free capacity.
For more background, the practical memory budget is covered in our guide to local LLM VRAM requirements.
Context memory does not disappear either
The total-versus-active distinction applies to weights. It does not eliminate the other allocations involved in inference.
The runtime still needs working memory, including the KV cache used to retain attention state for active sequences. Longer contexts and concurrent requests can therefore increase memory pressure even when the model uses sparse experts.
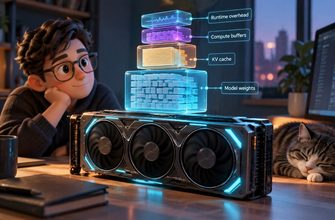
That means a useful MoE memory budget still looks conceptually like:
model weights + KV cache + compute buffers + runtime overhead
The model-weight term can be distributed differently across VRAM and RAM, but it does not become equal to the active parameter count.
When CPU expert placement makes sense
Keeping MoE experts in system memory is most interesting when capacity is the primary obstacle and accepting slower execution is preferable to not running the model at all.
It can also make sense on machines with substantial RAM but limited accelerator memory, particularly for experimentation, background processing or workloads where maximum interactive generation speed is not required.
But the correct comparison is not simply “GPU versus CPU.” Measure the complete configuration.
The existing CPU-offloading guide explains why moving model work outside VRAM can make a larger model runnable without making it equally fast.
Do not size an MoE machine from the A-number
A label such as A3B is useful for understanding sparse activation, not for estimating the complete memory footprint. Start with the actual checkpoint or GGUF size, then add context and runtime headroom. After that, determine which weights the runtime can keep in VRAM and which will remain elsewhere.
What to check before downloading a local MoE model
Start with the model card rather than the marketing shorthand. Find both the total parameter count and the activated parameter count. If the architecture documents its number of experts and experts selected per token, those figures explain where the sparse computation comes from.
Then check the actual file size of the quantization you intend to run. That is a much better starting point for capacity planning than the activated parameter count.
Next, decide where that model state will live. If the complete workload fits in VRAM, the problem is different from a configuration where a large expert pool remains in system memory.
Finally, test the workload you actually care about. Record prompt-processing speed and generation speed separately. Watch VRAM and system-memory use. If the runtime exposes enough information, verify the placement of the MoE weights rather than assuming that successful GPU initialization means the complete model is GPU-resident.
| Model specification | What it tells you | What it does not tell you |
|---|---|---|
| Total parameters | Scale of the complete learned parameter set | Exact runtime memory or speed |
| Activated parameters | Approximate sparse compute involved per token | Complete model storage requirement |
| GGUF / checkpoint size | Useful baseline for stored weight capacity | Total inference memory |
| Quantization | How aggressively weight storage has been compressed | Where those weights will execute |
| VRAM capacity | How much can reside in accelerator memory | Whether the resulting configuration will meet a latency target |
| System RAM | Additional capacity for CPU-resident model state | GPU-class memory bandwidth or compute |
The useful way to think about MoE locally
A dense model asks the computer to repeatedly use a large shared set of weights. An MoE model adds a router and a much larger menu of possible expert weights, then chooses only some of them for each token.
That can make the arithmetic sparse without making the model physically small.
For local AI, this distinction matters more than the model name. The total parameter count tells you about the state that has to exist. The active parameter count tells you something about the work selected for each token. Quantization determines how compactly the weights are represented. Placement determines whether those bytes live in VRAM, system RAM or across both.
If an MoE model looks surprisingly lightweight because its name ends in A3B or A22B, do not start with the active number. Start by asking where the entire expert pool will live—and how quickly the machine can deliver the experts that each token selects.